

Why use Cloud Adapter
A move to another cloud can mean changing the APIs your application calls, the tools your team uses, or both. Cloud Adapter lets you evaluate supported target services while keeping the origin API your application already understands. For example, an application that writes objects through the S3 API can store them in Google Cloud Storage. A supported DynamoDB read can retrieve an item from Azure Cosmos DB. Your application continues to send the origin request format; the adapter handles the selected target API.How it works
- Choose the service pair. Configure the origin service, the selected target service and the resources the workload will use. Confirm that the operations and request shapes you need are supported for that pair.
- Point your client at the adapter. Use the adapter endpoint with your familiar CLI or SDK and its configured origin-side credentials.
- Send a supported request. Cloud Adapter calls the selected target service, then returns a response in the origin API’s format.
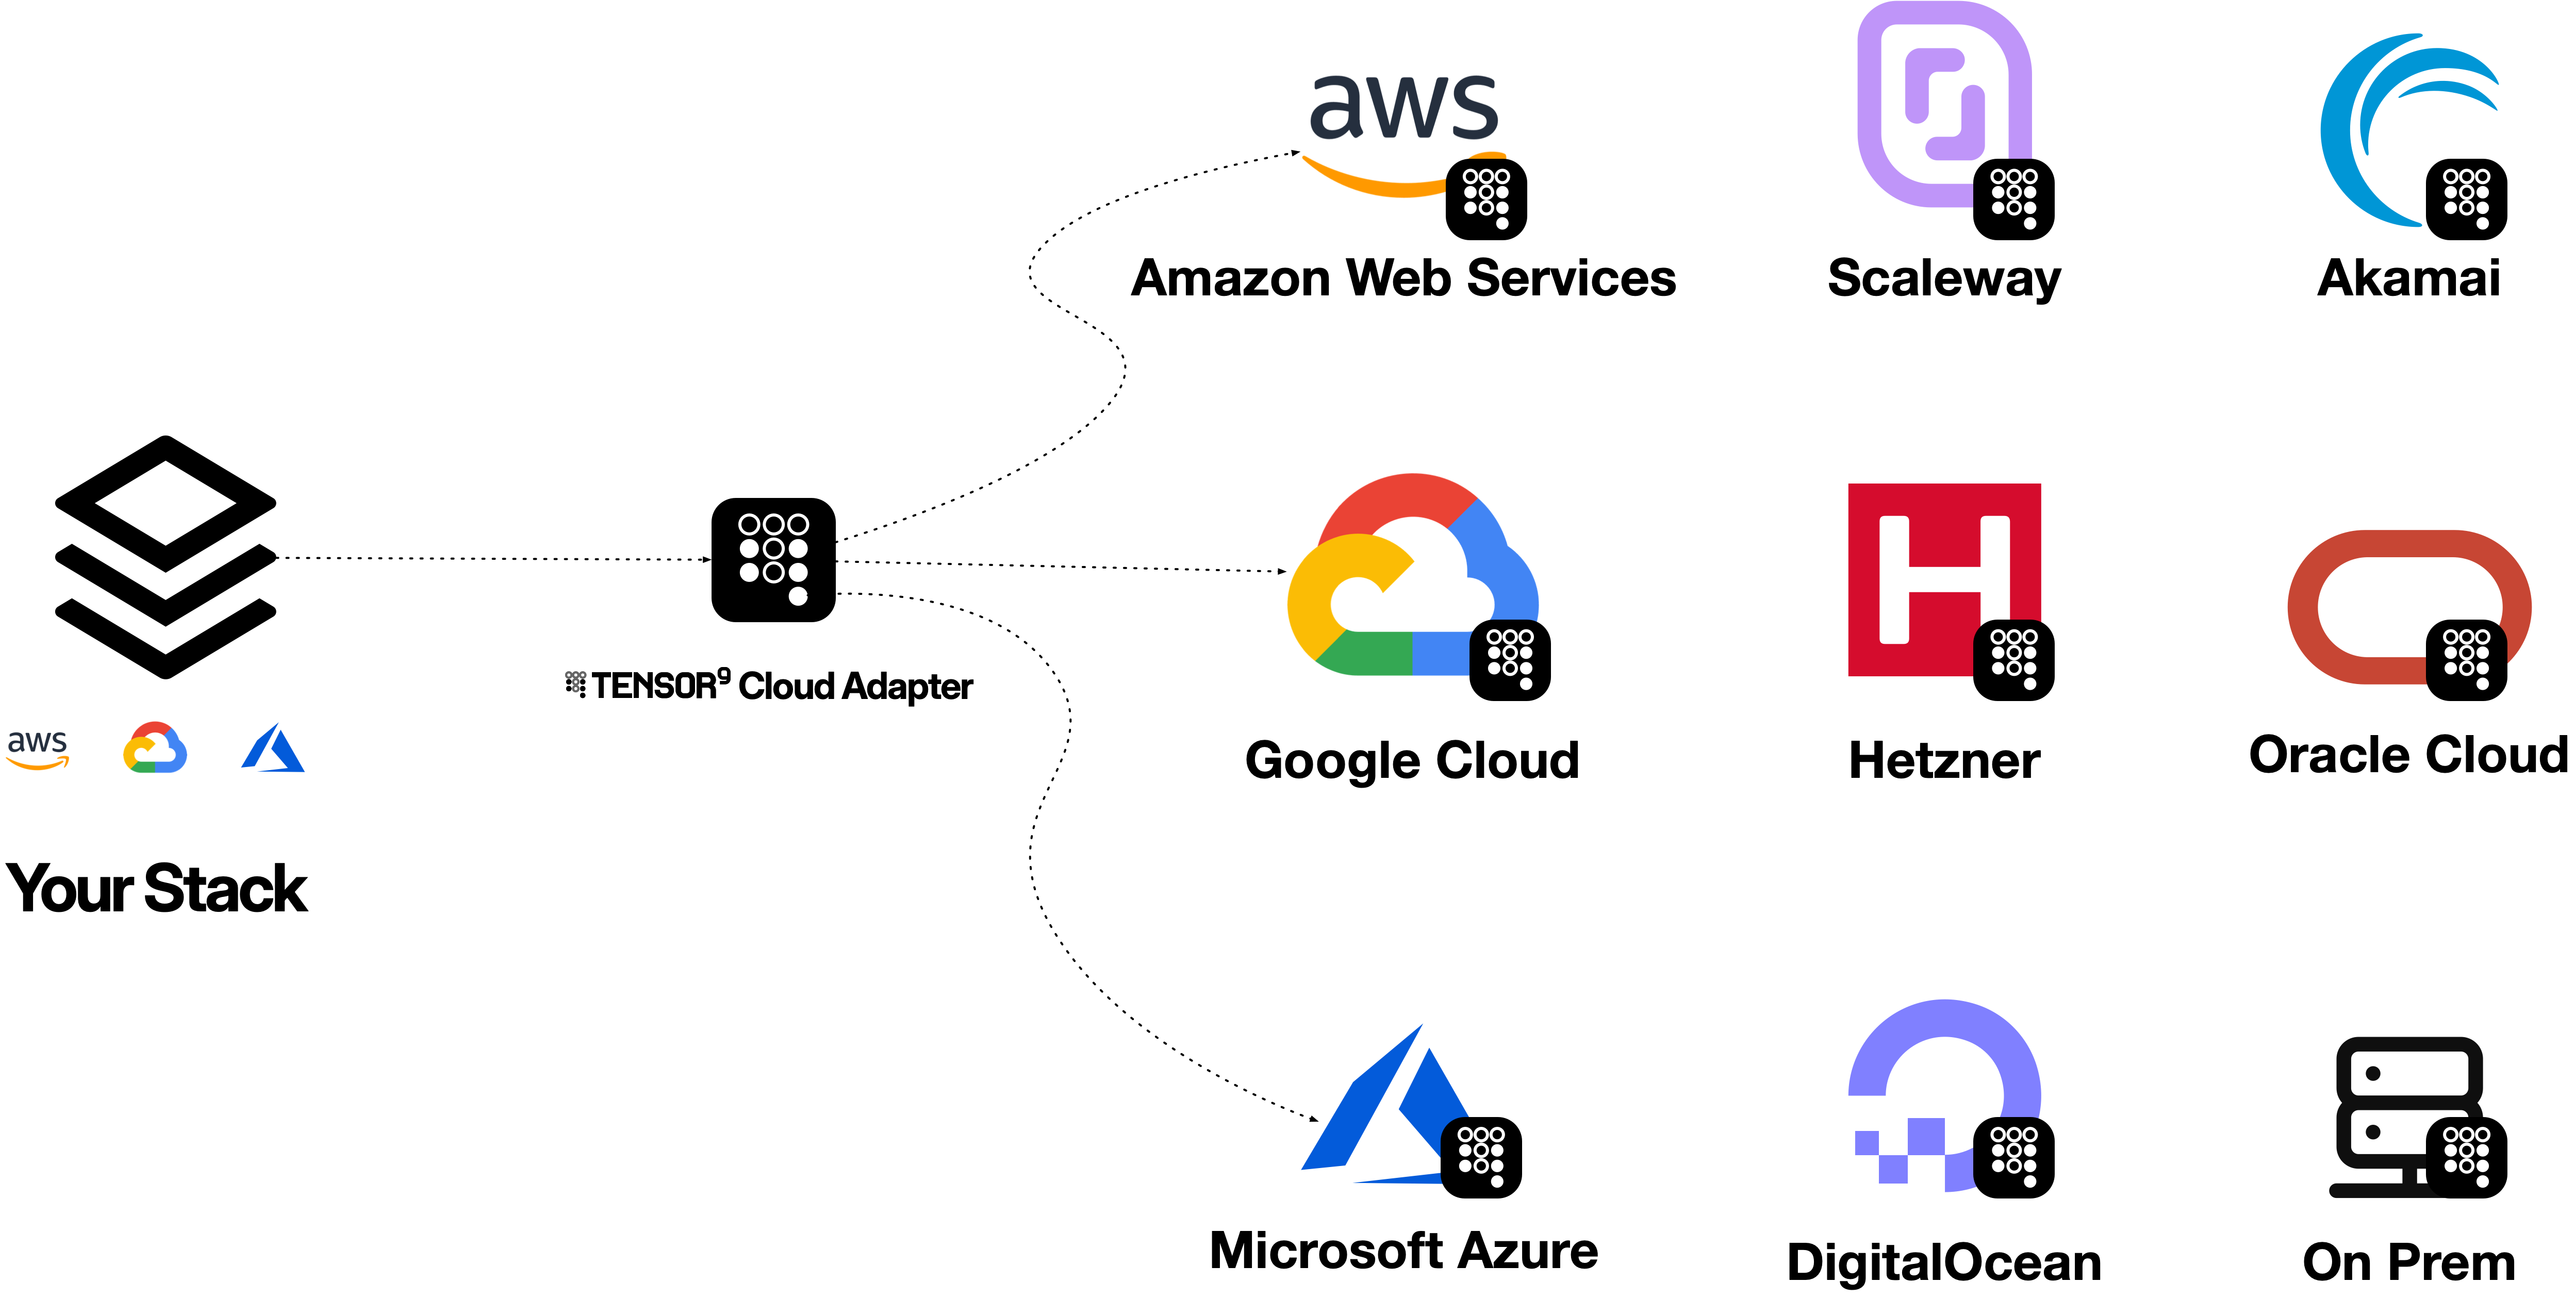
Request and response architecture
Your client speaks its normal origin API. Cloud Adapter handles the selected target API and returns the origin response format.

Use a standard SDK
You can use standard, unmodified SDKs for the supported origin API. Configure the adapter endpoint using the SDK’s normal endpoint option. The SDK continues to build, sign and parse requests using that origin API. For example, the standard AWS SDK for Python, boto3, can write the same object through the S3 API. Configure your region and origin-side credentials through the normal AWS credential chain before running this example. With the selected S3-to-Cloud Storage profile and bucket configured:endpoint_url and path-style S3 addressing are standard SDK configuration. No SDK fork or custom request format is required for this example. The same operation and service-pair limitations apply to SDK and CLI requests.
Examples with the AWS CLI
Before trying either example, the adapter must be running, its endpoint and origin-side credentials must be configured, and the named target resources must exist. SetT9_CLOUD_ADAPTER_ENDPOINT to your adapter endpoint. The commands below use illustrative resource names.
Store an object in Google Cloud Storage using S3
With S3 mapped to Google Cloud Storage, send an S3PutObject request:
Read an Azure Cosmos DB item using DynamoDB
For a DynamoDB table mapped to provisioned Azure Cosmos DB, send a supportedGetItem request:
Use Terraform or OpenTofu
Terraform and OpenTofu can call Cloud Adapter through a standard origin-cloud provider. Cloud Adapter is not a Terraform provider: it implements the supported cloud API operations that the provider calls. For an existing test bucket using S3 backed by Google Cloud Storage, the AWS provider’s standardendpoints setting directs S3 calls to the adapter. This configuration fragment comes from the bounded S3 example for AWS provider 5.100.0; adapter_endpoint is the endpoint of your running adapter:
skip_* options keep that provider version’s startup checks from contacting metadata, region validation or AWS STS outside the configured S3 route; they do not disable Cloud Adapter authentication. Reassess the provider’s API calls before changing versions.
Start with an isolated workspace and an existing test bucket. Check the exact resource lifecycle you need, including create, read, refresh and delete, through both the origin API and the target service. Changing a provider endpoint is not application-data migration and can affect refresh or replacement plans. Verify behavior before redirecting a production workspace.
Get started with Cloud Adapter
Install the Tensor9 CLI with Homebrew:tensor9 adapt svc run workflow. Full deployments use sip install to prepare the target-cloud fabric that hosts the serving image, with configuration, networking and credentials prepared for that environment.
The local container launcher is pending. The Homebrew commands above install the CLI; they do not deploy a running adapter or establish production readiness. Confirm supported operations and verify one bounded request before expanding the workload.