

azure::1.0.0::cache::redis, with backend choices shown together. Read how Tensor9 estimates service-adapter costs for price scope and capacity qualification, or return to additional services.
Azure Cache for Redis allocated cache capacity → ElastiCache
Origin API:azure::1.0.0::cache::redis. Target backend: aws::1.0.0::elasticache.
Designed mapping. This cost model describes an intended adapter. Its estimated price does not establish a delivered or selectable backend.
Azure Cache for Redis allocated cache capacity · Redis key reads per second
Estimated monthly service charges by Redis key reads per second. Adapter hosting and Tensor9 fees are excluded. Source: eastus; target: us-east-1; currency: USD.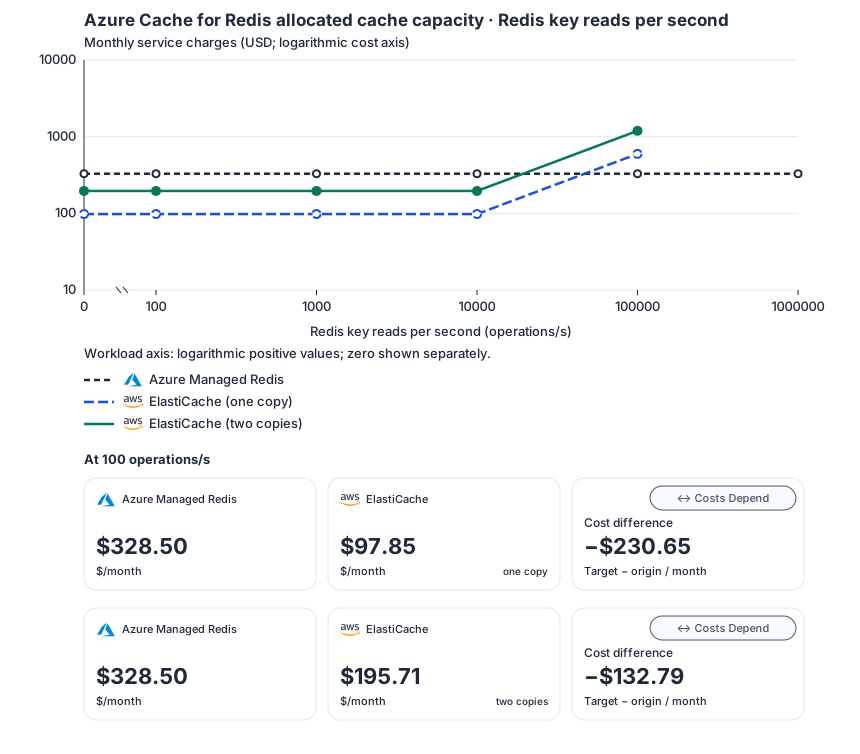
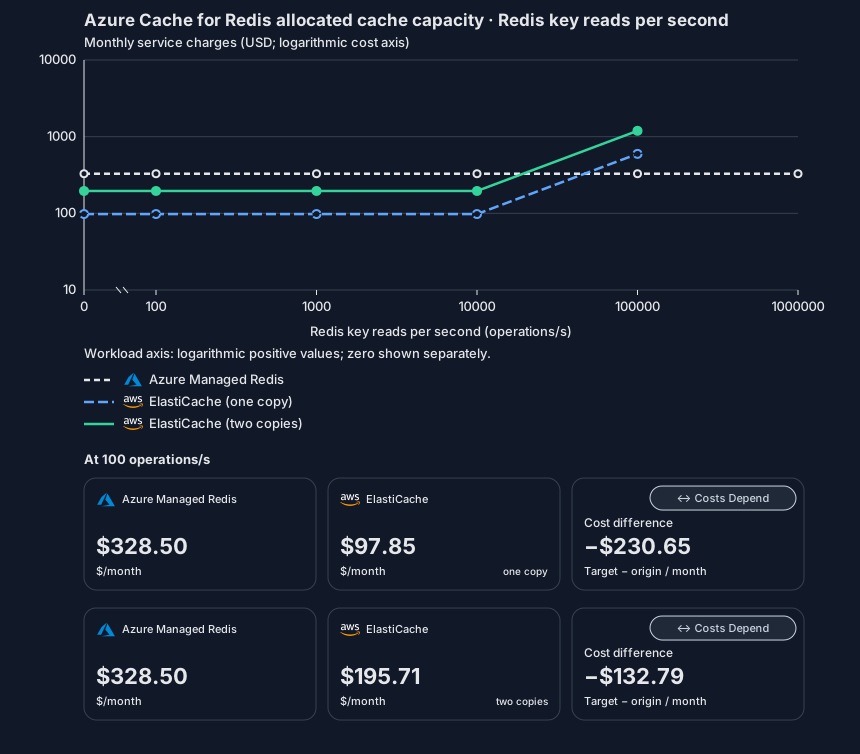
Estimated allocation from planning assumptions; not benchmark calibrated.
The sizing policy grows compute with translated work and peak headroom, memory with compute and working set, and disk with resident working state and reserve. Monthly usage is distinct from resident data; each workload’s assumptions define the translation. HA changes pricing, not this policy’s throughput estimate. Unpriced workloads exceed the policy’s configuration range; no silent vertical cap or automatic sharding is assumed.
- Row-store throughput (capacityOpsPerVcpuSecond, default 1500) is measured-by-tensor9 as a lower bound: the DynamoDB adapter on Cloud SQL db-custom-2-7680 (2 vCPU, PostgreSQL 16, us-west1) served 2,974 ops/s of YCSB-A at 16 threads without recorded saturation (src/main/kotlin/t9/prime/equiv/generated/eval/CloudsqlPostgresqlYcsbAT16GoYcsbV1_0_0.kt). Published CPU-bound pgbench reaches 3,101 read-write transactions and 20,289 point reads per vCPU-second (AWS z1d.2xlarge, PostgreSQL 14.5), so actual capacity is likely higher. Reads and writes share one coefficient: at the same adapter version, read-only YCSB-C was not faster than 50%-update YCSB-A.
- Log-broker throughput (capacityStreamMiBPerVcpuSecond 20 at 0.5 utilization, 4 GiB RAM per vCPU) is provider-documented by Google Managed Service for Apache Kafka sizing (https://docs.cloud.google.com/managed-service-for-apache-kafka/docs/plan-cluster-size): write-equivalent bytes are replicated writes plus a quarter of reads. Producer batches below 10 KB lower per-CPU throughput; that penalty is not modeled.
- Disk utilization 0.8 is provider-documented headroom below Cloud SQL automatic storage increase, which triggers near 91-95% full (https://docs.cloud.google.com/sql/docs/postgres/instance-settings). The 20 GiB reserve exceeds PostgreSQL’s 1 GB default max_wal_size; the remainder of that reserve is unmeasured.
- CPU tiers, 4 GiB per vCPU, at most 6.5 GiB per vCPU, 96 vCPU and 65,536 GiB disk follow Cloud SQL Enterprise custom machine limits (provider-documented, same page); 624 GiB is 96 × 6.5. Targets billed per node, unit or throughput unit are sized by their backend instead.
- No public evidence: peak/mean work (2) and the RAM working-set fraction (0.1). Proposed measurements: the p99 one-minute rate over the monthly mean from customer CloudWatch metrics; the buffer hit ratio while stepping RAM under a fixed YCSB-B load.
- Stored GiB already includes the origin family’s physical footprint assumptions; no second storage amplification is applied.
- The workload family already selected resource-hours; the throughput coefficient is not applied again.
- Copies and allocation fractions change cost only; they do not increase modeled primary capacity.
- Cache resident GiB is RAM provenance. Family-selected RAM-hours cover the working set;
- no SSD allocation is modeled. Persistence, snapshots and backup disks remain excluded.
- Only the selected native meter varies; other usage quantities and assumptions retain their displayed defaults. Editable authored planning guesses, not verified provider tariffs, benchmark measurements or a commercial quote. Other native meters retain their explicitly displayed default quantities.
- Planning estimate · editable authored rates and sizing assumptions dated 2026-10-22; not verified provider prices. eastus → us-east-1, USD/month.
- Source prices are reference charges, not an invoice. Target lines cover selected service usage/configuration only; adapter hosting and Tensor9 fees are excluded.
- Explicit tariff samples are not performance measurements or capacity qualification. No interpolation or break-even guarantee is implied.
- Variant assumptions show the first axis sample; any axis-dependent configuration is described by this curve’s workload note.
- Rates are cited provider list prices, editable for discounts, commitments or another region. Workload translation and capacity coefficients remain editable planning assumptions, not benchmark measurements or a commercial quote.
- Default-zero rates are explicit assumptions, not evidence that the deployed service or resource is free.
- Provisioned-unit minimums use an editable approximate allocation floor. Modeled target service cost is max(usage/allocation, minimum), with billable network, durable staging and dependent sinks added separately; actual RU/TU sizing, scaling increments and throughput remain unqualified.
- Durable staging is priced once: provisioned targets include adapter state in their selected allocation; native targets add a separate staging allocation when required. Adapter hosting is a separate allocation and must exclude resources already priced as staging, workers or target capacity.
- A declared adapter mapping and cost model do not establish implementation availability or service equivalence.
- This exact directed mapping has a design profile. Cost modeling does not establish an implemented or deployable adapter.
- Origin unit prices are cited provider list prices; capacity coefficients are editable authored planning guesses, not measured capacity.
- The origin is the exact registered azure::1.0.0::cache::redis identity. Renamed products and future aliases require explicit mapping updates.
- Source allocated CPU-hours and memory-hours establish independent minimum target allocation. Neither management API requests nor a key-operation count is an instance count.
- Peak weighted key-operation work and resident data can promote the allocation above those minima. CPU rounds to whole cores and RAM to quarter GiB.
- CPU and RAM are aggregate resources over 730 hours. Selected backend tariffs own replica count, availability configuration and actual instance shapes.
- A multi-core estimate assumes the workload can be partitioned. Redis command execution, hot keys, cross-key transactions and clustering can prevent linear scale.
- Zero allocated resources and zero workload do not prove target scale-to-zero; the selected backend may retain a provisioned minimum.
- Azure Cache for Redis bills per cache size; cache-hours times the size’s memory set the RAM minimum and CPU follows the selected memory shape.
- ElastiCache for Redis OSS node-based clusters bill whole nodes per hour; the capacity rate is cache.r7g.large’s price per GiB, and each replica is another full-price node. Valkey nodes list 20% lower (cache.r7g.large 0.1752 per hour, 0.0134047 per GiB-hour); ElastiCache Serverless is not selected. The CPU rate is zero because capacity GiB is the billed quantity, and the billed capacity is the cache family’s selected RAM rather than the generic planning CPU tier’s RAM; key-operation CPU demand raises cost only through the family’s RAM-per-CPU shape, which approximates managed throughput growing with capacity and is not a measured fit. The capacity charge and the minimum compare using their maximum, not their sum.
- Cache storedGiB represents resident RAM footprint, not billable SSD. Persistence, snapshots and backup disks require a separate explicit allocation.
- Row-store throughput (capacityOpsPerVcpuSecond, default 1500) is measured-by-tensor9 as a lower bound: the DynamoDB adapter on Cloud SQL db-custom-2-7680 (2 vCPU, PostgreSQL 16, us-west1) served 2,974 ops/s of YCSB-A at 16 threads without recorded saturation (src/main/kotlin/t9/prime/equiv/generated/eval/CloudsqlPostgresqlYcsbAT16GoYcsbV1_0_0.kt). Published CPU-bound pgbench reaches 3,101 read-write transactions and 20,289 point reads per vCPU-second (AWS z1d.2xlarge, PostgreSQL 14.5), so actual capacity is likely higher. Reads and writes share one coefficient: at the same adapter version, read-only YCSB-C was not faster than 50%-update YCSB-A.
- Log-broker throughput (capacityStreamMiBPerVcpuSecond 20 at 0.5 utilization, 4 GiB RAM per vCPU) is provider-documented by Google Managed Service for Apache Kafka sizing (https://docs.cloud.google.com/managed-service-for-apache-kafka/docs/plan-cluster-size): write-equivalent bytes are replicated writes plus a quarter of reads. Producer batches below 10 KB lower per-CPU throughput; that penalty is not modeled.
- Disk utilization 0.8 is provider-documented headroom below Cloud SQL automatic storage increase, which triggers near 91-95% full (https://docs.cloud.google.com/sql/docs/postgres/instance-settings). The 20 GiB reserve exceeds PostgreSQL’s 1 GB default max_wal_size; the remainder of that reserve is unmeasured.
- CPU tiers, 4 GiB per vCPU, at most 6.5 GiB per vCPU, 96 vCPU and 65,536 GiB disk follow Cloud SQL Enterprise custom machine limits (provider-documented, same page); 624 GiB is 96 × 6.5. Targets billed per node, unit or throughput unit are sized by their backend instead.
- No public evidence: peak/mean work (2) and the RAM working-set fraction (0.1). Proposed measurements: the p99 one-minute rate over the monthly mean from customer CloudWatch metrics; the buffer hit ratio while stepping RAM under a fixed YCSB-B load.
- Stored GiB already includes the origin family’s physical footprint assumptions; no second storage amplification is applied.
- The workload family already selected resource-hours; the throughput coefficient is not applied again.
- Copies and allocation fractions change cost only; they do not increase modeled primary capacity.
- Cache resident GiB is RAM provenance. Family-selected RAM-hours cover the working set;
- no SSD allocation is modeled. Persistence, snapshots and backup disks remain excluded.
- Azure Retail Prices API: https://prices.azure.com/api/retail/prices
- AWS Price List API: https://pricing.us-east-1.amazonaws.com/offers/v1.0/aws/AmazonElastiCache/current/us-east-1/index.json
- AWS Price List API, AWSDataTransfer: https://pricing.us-east-1.amazonaws.com/offers/v1.0/aws/AWSDataTransfer/current/us-east-1/index.json
- Replication traffic, snapshots, persistence write IOPS, network egress, cluster management premiums, licenses and migration.
- Command-specific complexity, Lua/scripts, module behavior, eviction/expiry churn, blocking commands, multi-key locality and benchmark-qualified latency.
- Taxes, discounts, credits and free-tier allowances unless explicitly reflected in edited rates.
- Unmodeled dependent services, task execution and operations outside the selected workload family.
plan-6f38d8e2054ca3166dde937a9c647167e1adeb1e / 2026-10-22.planning.2. Curve: workload-1.
Sources: Azure Retail Prices API, AWS Price List API, AWS Price List API, AWSDataTransfer.
Azure Cache for Redis allocated cache capacity · Redis key writes per second
Estimated monthly service charges by Redis key writes per second. Adapter hosting and Tensor9 fees are excluded. Source: eastus; target: us-east-1; currency: USD.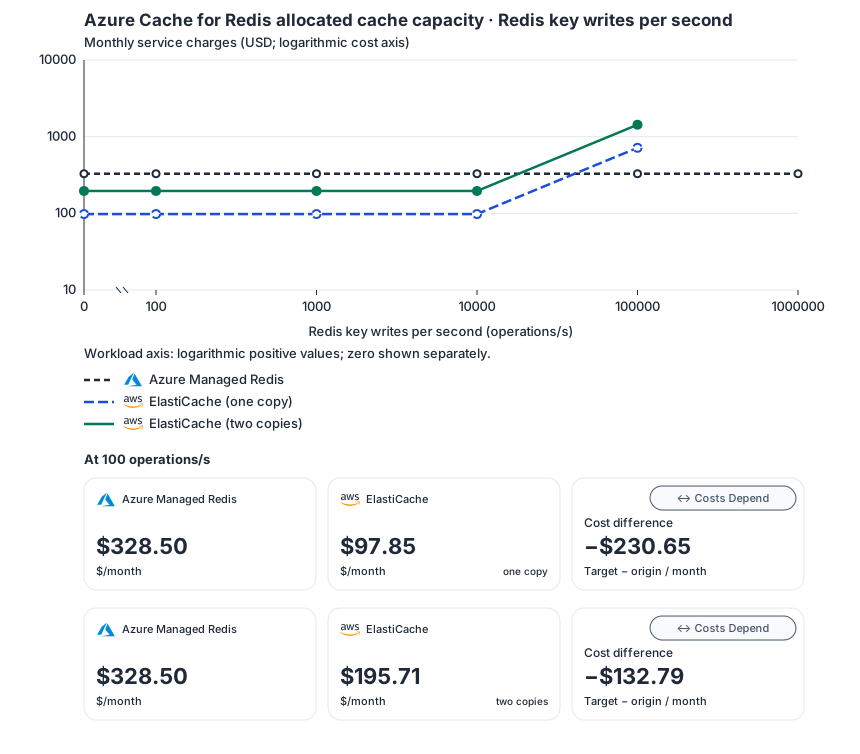
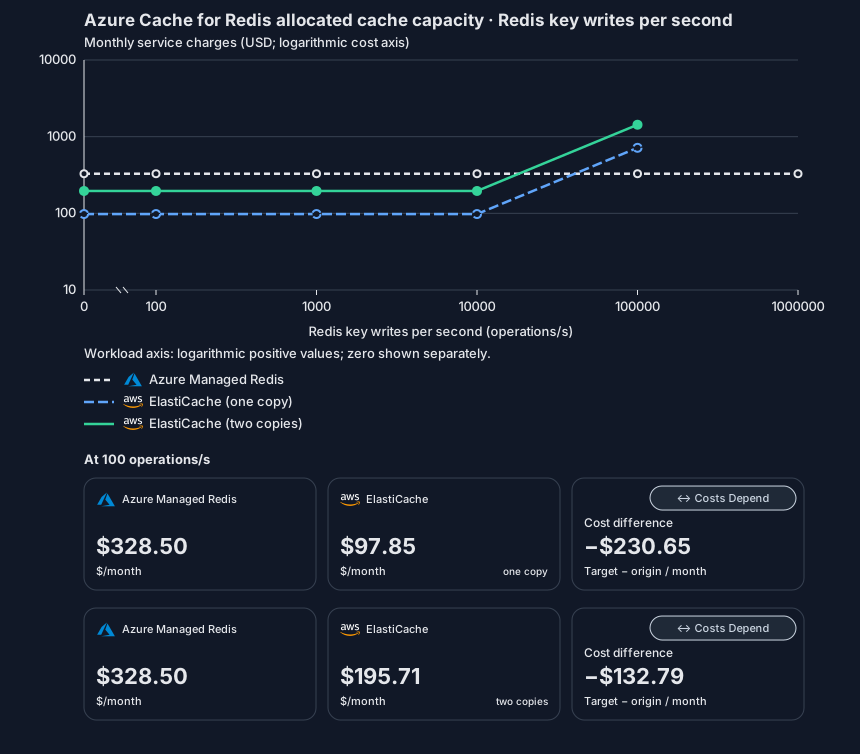
Estimated allocation from planning assumptions; not benchmark calibrated.
The sizing policy grows compute with translated work and peak headroom, memory with compute and working set, and disk with resident working state and reserve. Monthly usage is distinct from resident data; each workload’s assumptions define the translation. HA changes pricing, not this policy’s throughput estimate. Unpriced workloads exceed the policy’s configuration range; no silent vertical cap or automatic sharding is assumed.
- Row-store throughput (capacityOpsPerVcpuSecond, default 1500) is measured-by-tensor9 as a lower bound: the DynamoDB adapter on Cloud SQL db-custom-2-7680 (2 vCPU, PostgreSQL 16, us-west1) served 2,974 ops/s of YCSB-A at 16 threads without recorded saturation (src/main/kotlin/t9/prime/equiv/generated/eval/CloudsqlPostgresqlYcsbAT16GoYcsbV1_0_0.kt). Published CPU-bound pgbench reaches 3,101 read-write transactions and 20,289 point reads per vCPU-second (AWS z1d.2xlarge, PostgreSQL 14.5), so actual capacity is likely higher. Reads and writes share one coefficient: at the same adapter version, read-only YCSB-C was not faster than 50%-update YCSB-A.
- Log-broker throughput (capacityStreamMiBPerVcpuSecond 20 at 0.5 utilization, 4 GiB RAM per vCPU) is provider-documented by Google Managed Service for Apache Kafka sizing (https://docs.cloud.google.com/managed-service-for-apache-kafka/docs/plan-cluster-size): write-equivalent bytes are replicated writes plus a quarter of reads. Producer batches below 10 KB lower per-CPU throughput; that penalty is not modeled.
- Disk utilization 0.8 is provider-documented headroom below Cloud SQL automatic storage increase, which triggers near 91-95% full (https://docs.cloud.google.com/sql/docs/postgres/instance-settings). The 20 GiB reserve exceeds PostgreSQL’s 1 GB default max_wal_size; the remainder of that reserve is unmeasured.
- CPU tiers, 4 GiB per vCPU, at most 6.5 GiB per vCPU, 96 vCPU and 65,536 GiB disk follow Cloud SQL Enterprise custom machine limits (provider-documented, same page); 624 GiB is 96 × 6.5. Targets billed per node, unit or throughput unit are sized by their backend instead.
- No public evidence: peak/mean work (2) and the RAM working-set fraction (0.1). Proposed measurements: the p99 one-minute rate over the monthly mean from customer CloudWatch metrics; the buffer hit ratio while stepping RAM under a fixed YCSB-B load.
- Stored GiB already includes the origin family’s physical footprint assumptions; no second storage amplification is applied.
- The workload family already selected resource-hours; the throughput coefficient is not applied again.
- Copies and allocation fractions change cost only; they do not increase modeled primary capacity.
- Cache resident GiB is RAM provenance. Family-selected RAM-hours cover the working set;
- no SSD allocation is modeled. Persistence, snapshots and backup disks remain excluded.
- Only the selected native meter varies; other usage quantities and assumptions retain their displayed defaults. Editable authored planning guesses, not verified provider tariffs, benchmark measurements or a commercial quote. Other native meters retain their explicitly displayed default quantities.
- Planning estimate · editable authored rates and sizing assumptions dated 2026-10-22; not verified provider prices. eastus → us-east-1, USD/month.
- Source prices are reference charges, not an invoice. Target lines cover selected service usage/configuration only; adapter hosting and Tensor9 fees are excluded.
- Explicit tariff samples are not performance measurements or capacity qualification. No interpolation or break-even guarantee is implied.
- Variant assumptions show the first axis sample; any axis-dependent configuration is described by this curve’s workload note.
- Rates are cited provider list prices, editable for discounts, commitments or another region. Workload translation and capacity coefficients remain editable planning assumptions, not benchmark measurements or a commercial quote.
- Default-zero rates are explicit assumptions, not evidence that the deployed service or resource is free.
- Provisioned-unit minimums use an editable approximate allocation floor. Modeled target service cost is max(usage/allocation, minimum), with billable network, durable staging and dependent sinks added separately; actual RU/TU sizing, scaling increments and throughput remain unqualified.
- Durable staging is priced once: provisioned targets include adapter state in their selected allocation; native targets add a separate staging allocation when required. Adapter hosting is a separate allocation and must exclude resources already priced as staging, workers or target capacity.
- A declared adapter mapping and cost model do not establish implementation availability or service equivalence.
- This exact directed mapping has a design profile. Cost modeling does not establish an implemented or deployable adapter.
- Origin unit prices are cited provider list prices; capacity coefficients are editable authored planning guesses, not measured capacity.
- The origin is the exact registered azure::1.0.0::cache::redis identity. Renamed products and future aliases require explicit mapping updates.
- Source allocated CPU-hours and memory-hours establish independent minimum target allocation. Neither management API requests nor a key-operation count is an instance count.
- Peak weighted key-operation work and resident data can promote the allocation above those minima. CPU rounds to whole cores and RAM to quarter GiB.
- CPU and RAM are aggregate resources over 730 hours. Selected backend tariffs own replica count, availability configuration and actual instance shapes.
- A multi-core estimate assumes the workload can be partitioned. Redis command execution, hot keys, cross-key transactions and clustering can prevent linear scale.
- Zero allocated resources and zero workload do not prove target scale-to-zero; the selected backend may retain a provisioned minimum.
- Azure Cache for Redis bills per cache size; cache-hours times the size’s memory set the RAM minimum and CPU follows the selected memory shape.
- ElastiCache for Redis OSS node-based clusters bill whole nodes per hour; the capacity rate is cache.r7g.large’s price per GiB, and each replica is another full-price node. Valkey nodes list 20% lower (cache.r7g.large 0.1752 per hour, 0.0134047 per GiB-hour); ElastiCache Serverless is not selected. The CPU rate is zero because capacity GiB is the billed quantity, and the billed capacity is the cache family’s selected RAM rather than the generic planning CPU tier’s RAM; key-operation CPU demand raises cost only through the family’s RAM-per-CPU shape, which approximates managed throughput growing with capacity and is not a measured fit. The capacity charge and the minimum compare using their maximum, not their sum.
- Cache storedGiB represents resident RAM footprint, not billable SSD. Persistence, snapshots and backup disks require a separate explicit allocation.
- Row-store throughput (capacityOpsPerVcpuSecond, default 1500) is measured-by-tensor9 as a lower bound: the DynamoDB adapter on Cloud SQL db-custom-2-7680 (2 vCPU, PostgreSQL 16, us-west1) served 2,974 ops/s of YCSB-A at 16 threads without recorded saturation (src/main/kotlin/t9/prime/equiv/generated/eval/CloudsqlPostgresqlYcsbAT16GoYcsbV1_0_0.kt). Published CPU-bound pgbench reaches 3,101 read-write transactions and 20,289 point reads per vCPU-second (AWS z1d.2xlarge, PostgreSQL 14.5), so actual capacity is likely higher. Reads and writes share one coefficient: at the same adapter version, read-only YCSB-C was not faster than 50%-update YCSB-A.
- Log-broker throughput (capacityStreamMiBPerVcpuSecond 20 at 0.5 utilization, 4 GiB RAM per vCPU) is provider-documented by Google Managed Service for Apache Kafka sizing (https://docs.cloud.google.com/managed-service-for-apache-kafka/docs/plan-cluster-size): write-equivalent bytes are replicated writes plus a quarter of reads. Producer batches below 10 KB lower per-CPU throughput; that penalty is not modeled.
- Disk utilization 0.8 is provider-documented headroom below Cloud SQL automatic storage increase, which triggers near 91-95% full (https://docs.cloud.google.com/sql/docs/postgres/instance-settings). The 20 GiB reserve exceeds PostgreSQL’s 1 GB default max_wal_size; the remainder of that reserve is unmeasured.
- CPU tiers, 4 GiB per vCPU, at most 6.5 GiB per vCPU, 96 vCPU and 65,536 GiB disk follow Cloud SQL Enterprise custom machine limits (provider-documented, same page); 624 GiB is 96 × 6.5. Targets billed per node, unit or throughput unit are sized by their backend instead.
- No public evidence: peak/mean work (2) and the RAM working-set fraction (0.1). Proposed measurements: the p99 one-minute rate over the monthly mean from customer CloudWatch metrics; the buffer hit ratio while stepping RAM under a fixed YCSB-B load.
- Stored GiB already includes the origin family’s physical footprint assumptions; no second storage amplification is applied.
- The workload family already selected resource-hours; the throughput coefficient is not applied again.
- Copies and allocation fractions change cost only; they do not increase modeled primary capacity.
- Cache resident GiB is RAM provenance. Family-selected RAM-hours cover the working set;
- no SSD allocation is modeled. Persistence, snapshots and backup disks remain excluded.
- Azure Retail Prices API: https://prices.azure.com/api/retail/prices
- AWS Price List API: https://pricing.us-east-1.amazonaws.com/offers/v1.0/aws/AmazonElastiCache/current/us-east-1/index.json
- AWS Price List API, AWSDataTransfer: https://pricing.us-east-1.amazonaws.com/offers/v1.0/aws/AWSDataTransfer/current/us-east-1/index.json
- Replication traffic, snapshots, persistence write IOPS, network egress, cluster management premiums, licenses and migration.
- Command-specific complexity, Lua/scripts, module behavior, eviction/expiry churn, blocking commands, multi-key locality and benchmark-qualified latency.
- Taxes, discounts, credits and free-tier allowances unless explicitly reflected in edited rates.
- Unmodeled dependent services, task execution and operations outside the selected workload family.
plan-6f38d8e2054ca3166dde937a9c647167e1adeb1e / 2026-10-22.planning.2. Curve: workload-2.
Sources: Azure Retail Prices API, AWS Price List API, AWS Price List API, AWSDataTransfer.
Azure Cache for Redis allocated cache capacity · Resident logical cache data
Estimated monthly service charges by Resident logical cache data. Adapter hosting and Tensor9 fees are excluded. Source: eastus; target: us-east-1; currency: USD.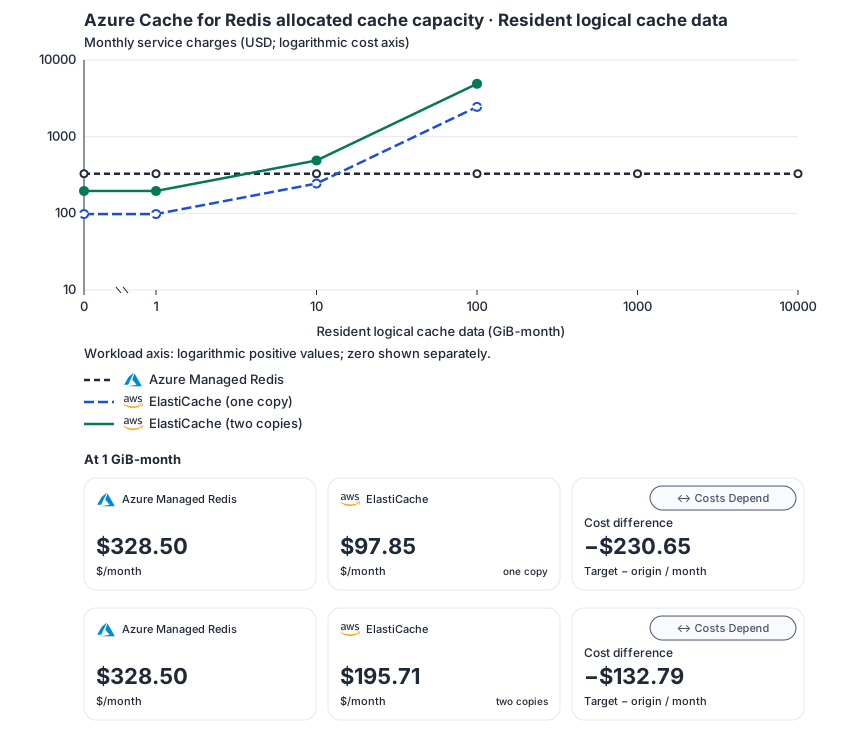
Estimated allocation from planning assumptions; not benchmark calibrated.
The sizing policy grows compute with translated work and peak headroom, memory with compute and working set, and disk with resident working state and reserve. Monthly usage is distinct from resident data; each workload’s assumptions define the translation. HA changes pricing, not this policy’s throughput estimate. Unpriced workloads exceed the policy’s configuration range; no silent vertical cap or automatic sharding is assumed.
- Row-store throughput (capacityOpsPerVcpuSecond, default 1500) is measured-by-tensor9 as a lower bound: the DynamoDB adapter on Cloud SQL db-custom-2-7680 (2 vCPU, PostgreSQL 16, us-west1) served 2,974 ops/s of YCSB-A at 16 threads without recorded saturation (src/main/kotlin/t9/prime/equiv/generated/eval/CloudsqlPostgresqlYcsbAT16GoYcsbV1_0_0.kt). Published CPU-bound pgbench reaches 3,101 read-write transactions and 20,289 point reads per vCPU-second (AWS z1d.2xlarge, PostgreSQL 14.5), so actual capacity is likely higher. Reads and writes share one coefficient: at the same adapter version, read-only YCSB-C was not faster than 50%-update YCSB-A.
- Log-broker throughput (capacityStreamMiBPerVcpuSecond 20 at 0.5 utilization, 4 GiB RAM per vCPU) is provider-documented by Google Managed Service for Apache Kafka sizing (https://docs.cloud.google.com/managed-service-for-apache-kafka/docs/plan-cluster-size): write-equivalent bytes are replicated writes plus a quarter of reads. Producer batches below 10 KB lower per-CPU throughput; that penalty is not modeled.
- Disk utilization 0.8 is provider-documented headroom below Cloud SQL automatic storage increase, which triggers near 91-95% full (https://docs.cloud.google.com/sql/docs/postgres/instance-settings). The 20 GiB reserve exceeds PostgreSQL’s 1 GB default max_wal_size; the remainder of that reserve is unmeasured.
- CPU tiers, 4 GiB per vCPU, at most 6.5 GiB per vCPU, 96 vCPU and 65,536 GiB disk follow Cloud SQL Enterprise custom machine limits (provider-documented, same page); 624 GiB is 96 × 6.5. Targets billed per node, unit or throughput unit are sized by their backend instead.
- No public evidence: peak/mean work (2) and the RAM working-set fraction (0.1). Proposed measurements: the p99 one-minute rate over the monthly mean from customer CloudWatch metrics; the buffer hit ratio while stepping RAM under a fixed YCSB-B load.
- Stored GiB already includes the origin family’s physical footprint assumptions; no second storage amplification is applied.
- The workload family already selected resource-hours; the throughput coefficient is not applied again.
- Copies and allocation fractions change cost only; they do not increase modeled primary capacity.
- Cache resident GiB is RAM provenance. Family-selected RAM-hours cover the working set;
- no SSD allocation is modeled. Persistence, snapshots and backup disks remain excluded.
- Only the selected native meter varies; other usage quantities and assumptions retain their displayed defaults. Editable authored planning guesses, not verified provider tariffs, benchmark measurements or a commercial quote. Other native meters retain their explicitly displayed default quantities.
- Planning estimate · editable authored rates and sizing assumptions dated 2026-10-22; not verified provider prices. eastus → us-east-1, USD/month.
- Source prices are reference charges, not an invoice. Target lines cover selected service usage/configuration only; adapter hosting and Tensor9 fees are excluded.
- Explicit tariff samples are not performance measurements or capacity qualification. No interpolation or break-even guarantee is implied.
- Variant assumptions show the first axis sample; any axis-dependent configuration is described by this curve’s workload note.
- Rates are cited provider list prices, editable for discounts, commitments or another region. Workload translation and capacity coefficients remain editable planning assumptions, not benchmark measurements or a commercial quote.
- Default-zero rates are explicit assumptions, not evidence that the deployed service or resource is free.
- Provisioned-unit minimums use an editable approximate allocation floor. Modeled target service cost is max(usage/allocation, minimum), with billable network, durable staging and dependent sinks added separately; actual RU/TU sizing, scaling increments and throughput remain unqualified.
- Durable staging is priced once: provisioned targets include adapter state in their selected allocation; native targets add a separate staging allocation when required. Adapter hosting is a separate allocation and must exclude resources already priced as staging, workers or target capacity.
- A declared adapter mapping and cost model do not establish implementation availability or service equivalence.
- This exact directed mapping has a design profile. Cost modeling does not establish an implemented or deployable adapter.
- Origin unit prices are cited provider list prices; capacity coefficients are editable authored planning guesses, not measured capacity.
- The origin is the exact registered azure::1.0.0::cache::redis identity. Renamed products and future aliases require explicit mapping updates.
- Source allocated CPU-hours and memory-hours establish independent minimum target allocation. Neither management API requests nor a key-operation count is an instance count.
- Peak weighted key-operation work and resident data can promote the allocation above those minima. CPU rounds to whole cores and RAM to quarter GiB.
- CPU and RAM are aggregate resources over 730 hours. Selected backend tariffs own replica count, availability configuration and actual instance shapes.
- A multi-core estimate assumes the workload can be partitioned. Redis command execution, hot keys, cross-key transactions and clustering can prevent linear scale.
- Zero allocated resources and zero workload do not prove target scale-to-zero; the selected backend may retain a provisioned minimum.
- Azure Cache for Redis bills per cache size; cache-hours times the size’s memory set the RAM minimum and CPU follows the selected memory shape.
- ElastiCache for Redis OSS node-based clusters bill whole nodes per hour; the capacity rate is cache.r7g.large’s price per GiB, and each replica is another full-price node. Valkey nodes list 20% lower (cache.r7g.large 0.1752 per hour, 0.0134047 per GiB-hour); ElastiCache Serverless is not selected. The CPU rate is zero because capacity GiB is the billed quantity, and the billed capacity is the cache family’s selected RAM rather than the generic planning CPU tier’s RAM; key-operation CPU demand raises cost only through the family’s RAM-per-CPU shape, which approximates managed throughput growing with capacity and is not a measured fit. The capacity charge and the minimum compare using their maximum, not their sum.
- Cache storedGiB represents resident RAM footprint, not billable SSD. Persistence, snapshots and backup disks require a separate explicit allocation.
- Row-store throughput (capacityOpsPerVcpuSecond, default 1500) is measured-by-tensor9 as a lower bound: the DynamoDB adapter on Cloud SQL db-custom-2-7680 (2 vCPU, PostgreSQL 16, us-west1) served 2,974 ops/s of YCSB-A at 16 threads without recorded saturation (src/main/kotlin/t9/prime/equiv/generated/eval/CloudsqlPostgresqlYcsbAT16GoYcsbV1_0_0.kt). Published CPU-bound pgbench reaches 3,101 read-write transactions and 20,289 point reads per vCPU-second (AWS z1d.2xlarge, PostgreSQL 14.5), so actual capacity is likely higher. Reads and writes share one coefficient: at the same adapter version, read-only YCSB-C was not faster than 50%-update YCSB-A.
- Log-broker throughput (capacityStreamMiBPerVcpuSecond 20 at 0.5 utilization, 4 GiB RAM per vCPU) is provider-documented by Google Managed Service for Apache Kafka sizing (https://docs.cloud.google.com/managed-service-for-apache-kafka/docs/plan-cluster-size): write-equivalent bytes are replicated writes plus a quarter of reads. Producer batches below 10 KB lower per-CPU throughput; that penalty is not modeled.
- Disk utilization 0.8 is provider-documented headroom below Cloud SQL automatic storage increase, which triggers near 91-95% full (https://docs.cloud.google.com/sql/docs/postgres/instance-settings). The 20 GiB reserve exceeds PostgreSQL’s 1 GB default max_wal_size; the remainder of that reserve is unmeasured.
- CPU tiers, 4 GiB per vCPU, at most 6.5 GiB per vCPU, 96 vCPU and 65,536 GiB disk follow Cloud SQL Enterprise custom machine limits (provider-documented, same page); 624 GiB is 96 × 6.5. Targets billed per node, unit or throughput unit are sized by their backend instead.
- No public evidence: peak/mean work (2) and the RAM working-set fraction (0.1). Proposed measurements: the p99 one-minute rate over the monthly mean from customer CloudWatch metrics; the buffer hit ratio while stepping RAM under a fixed YCSB-B load.
- Stored GiB already includes the origin family’s physical footprint assumptions; no second storage amplification is applied.
- The workload family already selected resource-hours; the throughput coefficient is not applied again.
- Copies and allocation fractions change cost only; they do not increase modeled primary capacity.
- Cache resident GiB is RAM provenance. Family-selected RAM-hours cover the working set;
- no SSD allocation is modeled. Persistence, snapshots and backup disks remain excluded.
- Azure Retail Prices API: https://prices.azure.com/api/retail/prices
- AWS Price List API: https://pricing.us-east-1.amazonaws.com/offers/v1.0/aws/AmazonElastiCache/current/us-east-1/index.json
- AWS Price List API, AWSDataTransfer: https://pricing.us-east-1.amazonaws.com/offers/v1.0/aws/AWSDataTransfer/current/us-east-1/index.json
- Replication traffic, snapshots, persistence write IOPS, network egress, cluster management premiums, licenses and migration.
- Command-specific complexity, Lua/scripts, module behavior, eviction/expiry churn, blocking commands, multi-key locality and benchmark-qualified latency.
- Taxes, discounts, credits and free-tier allowances unless explicitly reflected in edited rates.
- Unmodeled dependent services, task execution and operations outside the selected workload family.
plan-6f38d8e2054ca3166dde937a9c647167e1adeb1e / 2026-10-22.planning.2. Curve: workload-3.
Sources: Azure Retail Prices API, AWS Price List API, AWS Price List API, AWSDataTransfer.
Azure Cache for Redis allocated cache capacity · Allocated source cache-hours
Estimated monthly service charges by Allocated source cache-hours. Adapter hosting and Tensor9 fees are excluded. Source: eastus; target: us-east-1; currency: USD.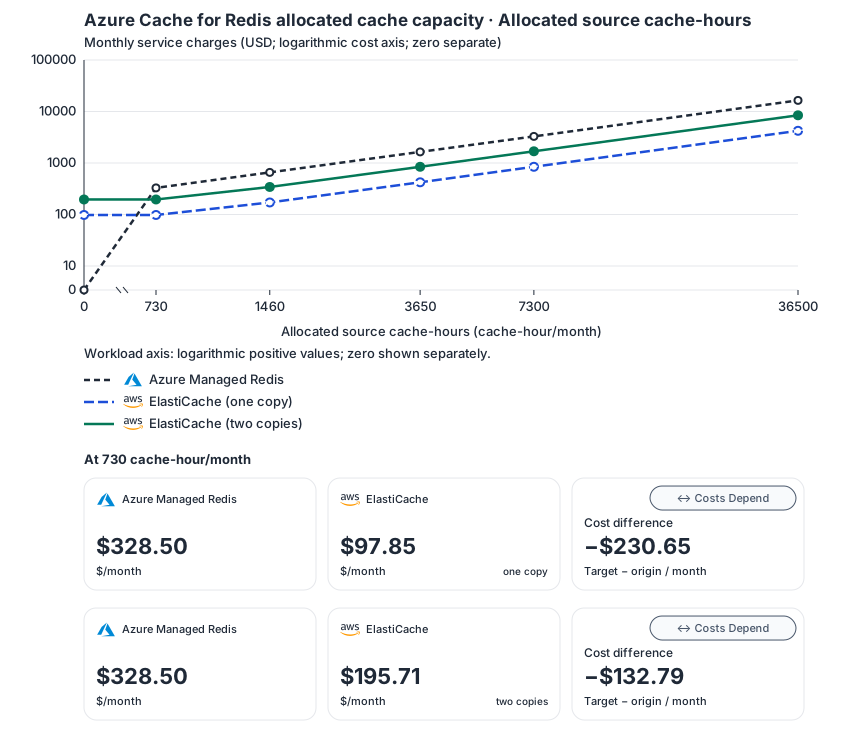
Estimated allocation from planning assumptions; not benchmark calibrated.
The sizing policy grows compute with translated work and peak headroom, memory with compute and working set, and disk with resident working state and reserve. Monthly usage is distinct from resident data; each workload’s assumptions define the translation. HA changes pricing, not this policy’s throughput estimate. Unpriced workloads exceed the policy’s configuration range; no silent vertical cap or automatic sharding is assumed.
- Row-store throughput (capacityOpsPerVcpuSecond, default 1500) is measured-by-tensor9 as a lower bound: the DynamoDB adapter on Cloud SQL db-custom-2-7680 (2 vCPU, PostgreSQL 16, us-west1) served 2,974 ops/s of YCSB-A at 16 threads without recorded saturation (src/main/kotlin/t9/prime/equiv/generated/eval/CloudsqlPostgresqlYcsbAT16GoYcsbV1_0_0.kt). Published CPU-bound pgbench reaches 3,101 read-write transactions and 20,289 point reads per vCPU-second (AWS z1d.2xlarge, PostgreSQL 14.5), so actual capacity is likely higher. Reads and writes share one coefficient: at the same adapter version, read-only YCSB-C was not faster than 50%-update YCSB-A.
- Log-broker throughput (capacityStreamMiBPerVcpuSecond 20 at 0.5 utilization, 4 GiB RAM per vCPU) is provider-documented by Google Managed Service for Apache Kafka sizing (https://docs.cloud.google.com/managed-service-for-apache-kafka/docs/plan-cluster-size): write-equivalent bytes are replicated writes plus a quarter of reads. Producer batches below 10 KB lower per-CPU throughput; that penalty is not modeled.
- Disk utilization 0.8 is provider-documented headroom below Cloud SQL automatic storage increase, which triggers near 91-95% full (https://docs.cloud.google.com/sql/docs/postgres/instance-settings). The 20 GiB reserve exceeds PostgreSQL’s 1 GB default max_wal_size; the remainder of that reserve is unmeasured.
- CPU tiers, 4 GiB per vCPU, at most 6.5 GiB per vCPU, 96 vCPU and 65,536 GiB disk follow Cloud SQL Enterprise custom machine limits (provider-documented, same page); 624 GiB is 96 × 6.5. Targets billed per node, unit or throughput unit are sized by their backend instead.
- No public evidence: peak/mean work (2) and the RAM working-set fraction (0.1). Proposed measurements: the p99 one-minute rate over the monthly mean from customer CloudWatch metrics; the buffer hit ratio while stepping RAM under a fixed YCSB-B load.
- Stored GiB already includes the origin family’s physical footprint assumptions; no second storage amplification is applied.
- The workload family already selected resource-hours; the throughput coefficient is not applied again.
- Copies and allocation fractions change cost only; they do not increase modeled primary capacity.
- Cache resident GiB is RAM provenance. Family-selected RAM-hours cover the working set;
- no SSD allocation is modeled. Persistence, snapshots and backup disks remain excluded.
- Only the selected native meter varies; other usage quantities and assumptions retain their displayed defaults. Editable authored planning guesses, not verified provider tariffs, benchmark measurements or a commercial quote. Other native meters retain their explicitly displayed default quantities.
- Planning estimate · editable authored rates and sizing assumptions dated 2026-10-22; not verified provider prices. eastus → us-east-1, USD/month.
- Source prices are reference charges, not an invoice. Target lines cover selected service usage/configuration only; adapter hosting and Tensor9 fees are excluded.
- Explicit tariff samples are not performance measurements or capacity qualification. No interpolation or break-even guarantee is implied.
- Variant assumptions show the first axis sample; any axis-dependent configuration is described by this curve’s workload note.
- Rates are cited provider list prices, editable for discounts, commitments or another region. Workload translation and capacity coefficients remain editable planning assumptions, not benchmark measurements or a commercial quote.
- Default-zero rates are explicit assumptions, not evidence that the deployed service or resource is free.
- Provisioned-unit minimums use an editable approximate allocation floor. Modeled target service cost is max(usage/allocation, minimum), with billable network, durable staging and dependent sinks added separately; actual RU/TU sizing, scaling increments and throughput remain unqualified.
- Durable staging is priced once: provisioned targets include adapter state in their selected allocation; native targets add a separate staging allocation when required. Adapter hosting is a separate allocation and must exclude resources already priced as staging, workers or target capacity.
- A declared adapter mapping and cost model do not establish implementation availability or service equivalence.
- This exact directed mapping has a design profile. Cost modeling does not establish an implemented or deployable adapter.
- Origin unit prices are cited provider list prices; capacity coefficients are editable authored planning guesses, not measured capacity.
- The origin is the exact registered azure::1.0.0::cache::redis identity. Renamed products and future aliases require explicit mapping updates.
- Source allocated CPU-hours and memory-hours establish independent minimum target allocation. Neither management API requests nor a key-operation count is an instance count.
- Peak weighted key-operation work and resident data can promote the allocation above those minima. CPU rounds to whole cores and RAM to quarter GiB.
- CPU and RAM are aggregate resources over 730 hours. Selected backend tariffs own replica count, availability configuration and actual instance shapes.
- A multi-core estimate assumes the workload can be partitioned. Redis command execution, hot keys, cross-key transactions and clustering can prevent linear scale.
- Zero allocated resources and zero workload do not prove target scale-to-zero; the selected backend may retain a provisioned minimum.
- Azure Cache for Redis bills per cache size; cache-hours times the size’s memory set the RAM minimum and CPU follows the selected memory shape.
- ElastiCache for Redis OSS node-based clusters bill whole nodes per hour; the capacity rate is cache.r7g.large’s price per GiB, and each replica is another full-price node. Valkey nodes list 20% lower (cache.r7g.large 0.1752 per hour, 0.0134047 per GiB-hour); ElastiCache Serverless is not selected. The CPU rate is zero because capacity GiB is the billed quantity, and the billed capacity is the cache family’s selected RAM rather than the generic planning CPU tier’s RAM; key-operation CPU demand raises cost only through the family’s RAM-per-CPU shape, which approximates managed throughput growing with capacity and is not a measured fit. The capacity charge and the minimum compare using their maximum, not their sum.
- Cache storedGiB represents resident RAM footprint, not billable SSD. Persistence, snapshots and backup disks require a separate explicit allocation.
- Row-store throughput (capacityOpsPerVcpuSecond, default 1500) is measured-by-tensor9 as a lower bound: the DynamoDB adapter on Cloud SQL db-custom-2-7680 (2 vCPU, PostgreSQL 16, us-west1) served 2,974 ops/s of YCSB-A at 16 threads without recorded saturation (src/main/kotlin/t9/prime/equiv/generated/eval/CloudsqlPostgresqlYcsbAT16GoYcsbV1_0_0.kt). Published CPU-bound pgbench reaches 3,101 read-write transactions and 20,289 point reads per vCPU-second (AWS z1d.2xlarge, PostgreSQL 14.5), so actual capacity is likely higher. Reads and writes share one coefficient: at the same adapter version, read-only YCSB-C was not faster than 50%-update YCSB-A.
- Log-broker throughput (capacityStreamMiBPerVcpuSecond 20 at 0.5 utilization, 4 GiB RAM per vCPU) is provider-documented by Google Managed Service for Apache Kafka sizing (https://docs.cloud.google.com/managed-service-for-apache-kafka/docs/plan-cluster-size): write-equivalent bytes are replicated writes plus a quarter of reads. Producer batches below 10 KB lower per-CPU throughput; that penalty is not modeled.
- Disk utilization 0.8 is provider-documented headroom below Cloud SQL automatic storage increase, which triggers near 91-95% full (https://docs.cloud.google.com/sql/docs/postgres/instance-settings). The 20 GiB reserve exceeds PostgreSQL’s 1 GB default max_wal_size; the remainder of that reserve is unmeasured.
- CPU tiers, 4 GiB per vCPU, at most 6.5 GiB per vCPU, 96 vCPU and 65,536 GiB disk follow Cloud SQL Enterprise custom machine limits (provider-documented, same page); 624 GiB is 96 × 6.5. Targets billed per node, unit or throughput unit are sized by their backend instead.
- No public evidence: peak/mean work (2) and the RAM working-set fraction (0.1). Proposed measurements: the p99 one-minute rate over the monthly mean from customer CloudWatch metrics; the buffer hit ratio while stepping RAM under a fixed YCSB-B load.
- Stored GiB already includes the origin family’s physical footprint assumptions; no second storage amplification is applied.
- The workload family already selected resource-hours; the throughput coefficient is not applied again.
- Copies and allocation fractions change cost only; they do not increase modeled primary capacity.
- Cache resident GiB is RAM provenance. Family-selected RAM-hours cover the working set;
- no SSD allocation is modeled. Persistence, snapshots and backup disks remain excluded.
- Azure Retail Prices API: https://prices.azure.com/api/retail/prices
- AWS Price List API: https://pricing.us-east-1.amazonaws.com/offers/v1.0/aws/AmazonElastiCache/current/us-east-1/index.json
- AWS Price List API, AWSDataTransfer: https://pricing.us-east-1.amazonaws.com/offers/v1.0/aws/AWSDataTransfer/current/us-east-1/index.json
- Replication traffic, snapshots, persistence write IOPS, network egress, cluster management premiums, licenses and migration.
- Command-specific complexity, Lua/scripts, module behavior, eviction/expiry churn, blocking commands, multi-key locality and benchmark-qualified latency.
- Taxes, discounts, credits and free-tier allowances unless explicitly reflected in edited rates.
- Unmodeled dependent services, task execution and operations outside the selected workload family.
plan-6f38d8e2054ca3166dde937a9c647167e1adeb1e / 2026-10-22.planning.2. Curve: workload-4.
Sources: Azure Retail Prices API, AWS Price List API, AWS Price List API, AWSDataTransfer.
Azure Cache for Redis allocated cache capacity → Memorystore for Redis
Origin API:azure::1.0.0::cache::redis. Target backend: google::1.0.0::memorystore::redis.
Designed mapping. This cost model describes an intended adapter. Its estimated price does not establish a delivered or selectable backend.
Azure Cache for Redis allocated cache capacity · Redis key reads per second
Estimated monthly service charges by Redis key reads per second. Adapter hosting and Tensor9 fees are excluded. Source: eastus; target: us-central1; currency: USD.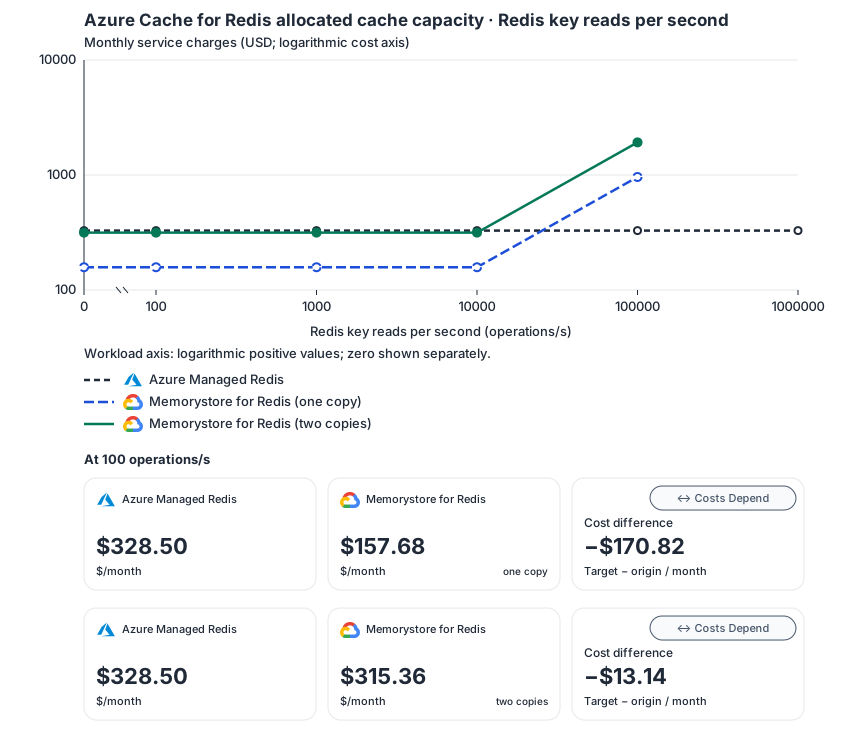
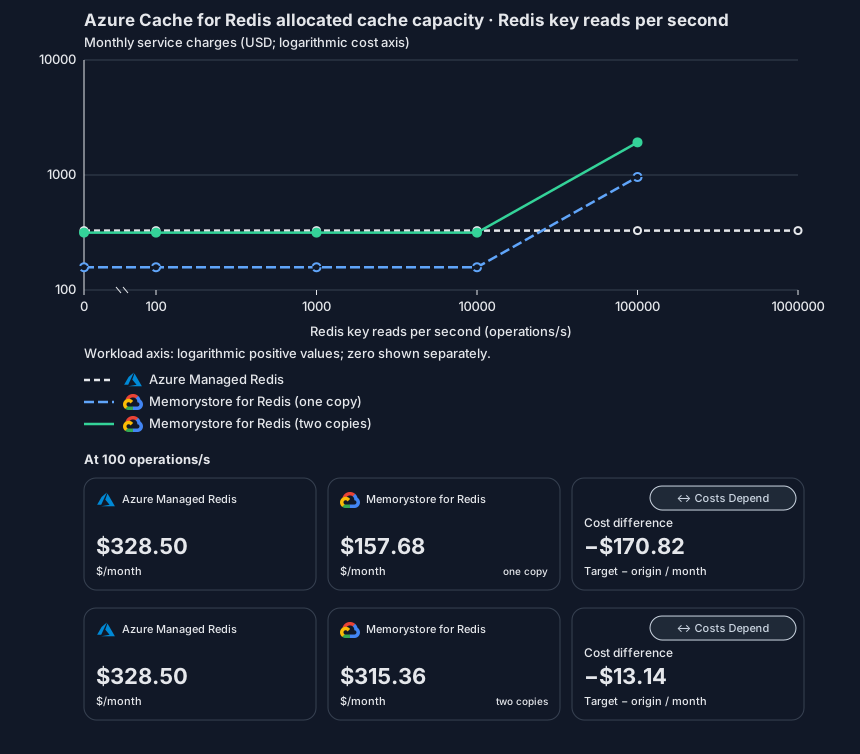
Estimated allocation from planning assumptions; not benchmark calibrated.
The sizing policy grows compute with translated work and peak headroom, memory with compute and working set, and disk with resident working state and reserve. Monthly usage is distinct from resident data; each workload’s assumptions define the translation. HA changes pricing, not this policy’s throughput estimate. Unpriced workloads exceed the policy’s configuration range; no silent vertical cap or automatic sharding is assumed.
- Row-store throughput (capacityOpsPerVcpuSecond, default 1500) is measured-by-tensor9 as a lower bound: the DynamoDB adapter on Cloud SQL db-custom-2-7680 (2 vCPU, PostgreSQL 16, us-west1) served 2,974 ops/s of YCSB-A at 16 threads without recorded saturation (src/main/kotlin/t9/prime/equiv/generated/eval/CloudsqlPostgresqlYcsbAT16GoYcsbV1_0_0.kt). Published CPU-bound pgbench reaches 3,101 read-write transactions and 20,289 point reads per vCPU-second (AWS z1d.2xlarge, PostgreSQL 14.5), so actual capacity is likely higher. Reads and writes share one coefficient: at the same adapter version, read-only YCSB-C was not faster than 50%-update YCSB-A.
- Log-broker throughput (capacityStreamMiBPerVcpuSecond 20 at 0.5 utilization, 4 GiB RAM per vCPU) is provider-documented by Google Managed Service for Apache Kafka sizing (https://docs.cloud.google.com/managed-service-for-apache-kafka/docs/plan-cluster-size): write-equivalent bytes are replicated writes plus a quarter of reads. Producer batches below 10 KB lower per-CPU throughput; that penalty is not modeled.
- Disk utilization 0.8 is provider-documented headroom below Cloud SQL automatic storage increase, which triggers near 91-95% full (https://docs.cloud.google.com/sql/docs/postgres/instance-settings). The 20 GiB reserve exceeds PostgreSQL’s 1 GB default max_wal_size; the remainder of that reserve is unmeasured.
- CPU tiers, 4 GiB per vCPU, at most 6.5 GiB per vCPU, 96 vCPU and 65,536 GiB disk follow Cloud SQL Enterprise custom machine limits (provider-documented, same page); 624 GiB is 96 × 6.5. Targets billed per node, unit or throughput unit are sized by their backend instead.
- No public evidence: peak/mean work (2) and the RAM working-set fraction (0.1). Proposed measurements: the p99 one-minute rate over the monthly mean from customer CloudWatch metrics; the buffer hit ratio while stepping RAM under a fixed YCSB-B load.
- Stored GiB already includes the origin family’s physical footprint assumptions; no second storage amplification is applied.
- The workload family already selected resource-hours; the throughput coefficient is not applied again.
- Copies and allocation fractions change cost only; they do not increase modeled primary capacity.
- Cache resident GiB is RAM provenance. Family-selected RAM-hours cover the working set;
- no SSD allocation is modeled. Persistence, snapshots and backup disks remain excluded.
- Only the selected native meter varies; other usage quantities and assumptions retain their displayed defaults. Editable authored planning guesses, not verified provider tariffs, benchmark measurements or a commercial quote. Other native meters retain their explicitly displayed default quantities.
- Planning estimate · editable authored rates and sizing assumptions dated 2026-10-22; not verified provider prices. eastus → us-central1, USD/month.
- Source prices are reference charges, not an invoice. Target lines cover selected service usage/configuration only; adapter hosting and Tensor9 fees are excluded.
- Explicit tariff samples are not performance measurements or capacity qualification. No interpolation or break-even guarantee is implied.
- Variant assumptions show the first axis sample; any axis-dependent configuration is described by this curve’s workload note.
- Rates are cited provider list prices, editable for discounts, commitments or another region. Workload translation and capacity coefficients remain editable planning assumptions, not benchmark measurements or a commercial quote.
- Default-zero rates are explicit assumptions, not evidence that the deployed service or resource is free.
- Provisioned-unit minimums use an editable approximate allocation floor. Modeled target service cost is max(usage/allocation, minimum), with billable network, durable staging and dependent sinks added separately; actual RU/TU sizing, scaling increments and throughput remain unqualified.
- Durable staging is priced once: provisioned targets include adapter state in their selected allocation; native targets add a separate staging allocation when required. Adapter hosting is a separate allocation and must exclude resources already priced as staging, workers or target capacity.
- A declared adapter mapping and cost model do not establish implementation availability or service equivalence.
- This exact directed mapping has a design profile. Cost modeling does not establish an implemented or deployable adapter.
- Origin unit prices are cited provider list prices; capacity coefficients are editable authored planning guesses, not measured capacity.
- The origin is the exact registered azure::1.0.0::cache::redis identity. Renamed products and future aliases require explicit mapping updates.
- Source allocated CPU-hours and memory-hours establish independent minimum target allocation. Neither management API requests nor a key-operation count is an instance count.
- Peak weighted key-operation work and resident data can promote the allocation above those minima. CPU rounds to whole cores and RAM to quarter GiB.
- CPU and RAM are aggregate resources over 730 hours. Selected backend tariffs own replica count, availability configuration and actual instance shapes.
- A multi-core estimate assumes the workload can be partitioned. Redis command execution, hot keys, cross-key transactions and clustering can prevent linear scale.
- Zero allocated resources and zero workload do not prove target scale-to-zero; the selected backend may retain a provisioned minimum.
- Azure Cache for Redis bills per cache size; cache-hours times the size’s memory set the RAM minimum and CPU follows the selected memory shape.
- Google Cloud bills Memorystore for Redis per provisioned capacity GiB-hour in 1-second increments with no separate CPU charge. In us-central1 Basic tier lists USD 0.049 (M1, 1-4 GiB), 0.027 (M2, 5-10 GiB), 0.023 (M3), 0.019 (M4) and 0.016 (M5) per GiB-hour; Standard tier lists 0.064, 0.054, 0.046, 0.035 and 0.03 (https://cloud.google.com/memorystore/docs/redis/pricing). The rate is Basic M2; the two-copy variant equals Standard M2. Other capacity tiers, read replicas and committed-use discounts change the rate. Memorystore has only private endpoints, so selected network is priced at the listed inter-region egress within North America. The CPU rate is zero because capacity GiB is the billed quantity, and the billed capacity is the cache family’s selected RAM rather than the generic planning CPU tier’s RAM; key-operation CPU demand raises cost only through the family’s RAM-per-CPU shape, which approximates managed throughput growing with capacity and is not a measured fit. The capacity charge and the minimum compare using their maximum, not their sum.
- Cache storedGiB represents resident RAM footprint, not billable SSD. Persistence, snapshots and backup disks require a separate explicit allocation.
- Row-store throughput (capacityOpsPerVcpuSecond, default 1500) is measured-by-tensor9 as a lower bound: the DynamoDB adapter on Cloud SQL db-custom-2-7680 (2 vCPU, PostgreSQL 16, us-west1) served 2,974 ops/s of YCSB-A at 16 threads without recorded saturation (src/main/kotlin/t9/prime/equiv/generated/eval/CloudsqlPostgresqlYcsbAT16GoYcsbV1_0_0.kt). Published CPU-bound pgbench reaches 3,101 read-write transactions and 20,289 point reads per vCPU-second (AWS z1d.2xlarge, PostgreSQL 14.5), so actual capacity is likely higher. Reads and writes share one coefficient: at the same adapter version, read-only YCSB-C was not faster than 50%-update YCSB-A.
- Log-broker throughput (capacityStreamMiBPerVcpuSecond 20 at 0.5 utilization, 4 GiB RAM per vCPU) is provider-documented by Google Managed Service for Apache Kafka sizing (https://docs.cloud.google.com/managed-service-for-apache-kafka/docs/plan-cluster-size): write-equivalent bytes are replicated writes plus a quarter of reads. Producer batches below 10 KB lower per-CPU throughput; that penalty is not modeled.
- Disk utilization 0.8 is provider-documented headroom below Cloud SQL automatic storage increase, which triggers near 91-95% full (https://docs.cloud.google.com/sql/docs/postgres/instance-settings). The 20 GiB reserve exceeds PostgreSQL’s 1 GB default max_wal_size; the remainder of that reserve is unmeasured.
- CPU tiers, 4 GiB per vCPU, at most 6.5 GiB per vCPU, 96 vCPU and 65,536 GiB disk follow Cloud SQL Enterprise custom machine limits (provider-documented, same page); 624 GiB is 96 × 6.5. Targets billed per node, unit or throughput unit are sized by their backend instead.
- No public evidence: peak/mean work (2) and the RAM working-set fraction (0.1). Proposed measurements: the p99 one-minute rate over the monthly mean from customer CloudWatch metrics; the buffer hit ratio while stepping RAM under a fixed YCSB-B load.
- Stored GiB already includes the origin family’s physical footprint assumptions; no second storage amplification is applied.
- The workload family already selected resource-hours; the throughput coefficient is not applied again.
- Copies and allocation fractions change cost only; they do not increase modeled primary capacity.
- Cache resident GiB is RAM provenance. Family-selected RAM-hours cover the working set;
- no SSD allocation is modeled. Persistence, snapshots and backup disks remain excluded.
- Azure Retail Prices API: https://prices.azure.com/api/retail/prices
- Memorystore for Redis pricing: https://cloud.google.com/memorystore/docs/redis/pricing
- Replication traffic, snapshots, persistence write IOPS, network egress, cluster management premiums, licenses and migration.
- Command-specific complexity, Lua/scripts, module behavior, eviction/expiry churn, blocking commands, multi-key locality and benchmark-qualified latency.
- Taxes, discounts, credits and free-tier allowances unless explicitly reflected in edited rates.
- Unmodeled dependent services, task execution and operations outside the selected workload family.
plan-88d38420bfbc627f193029e781b7a9e0c528e6fb / 2026-10-22.planning.2. Curve: workload-1.
Sources: Azure Retail Prices API, Memorystore for Redis pricing.
Azure Cache for Redis allocated cache capacity · Redis key writes per second
Estimated monthly service charges by Redis key writes per second. Adapter hosting and Tensor9 fees are excluded. Source: eastus; target: us-central1; currency: USD.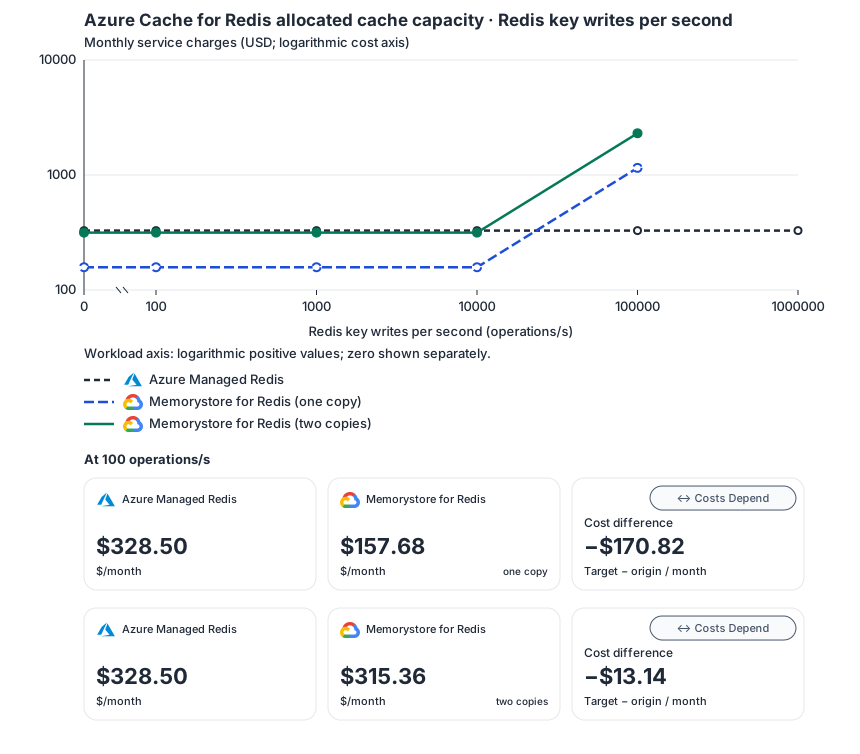
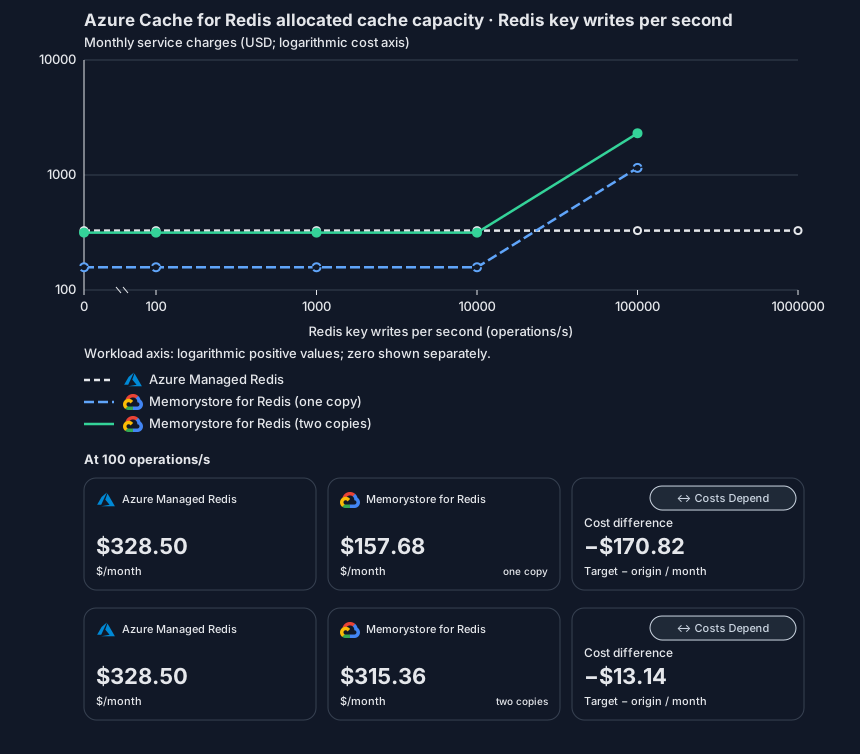
Estimated allocation from planning assumptions; not benchmark calibrated.
The sizing policy grows compute with translated work and peak headroom, memory with compute and working set, and disk with resident working state and reserve. Monthly usage is distinct from resident data; each workload’s assumptions define the translation. HA changes pricing, not this policy’s throughput estimate. Unpriced workloads exceed the policy’s configuration range; no silent vertical cap or automatic sharding is assumed.
- Row-store throughput (capacityOpsPerVcpuSecond, default 1500) is measured-by-tensor9 as a lower bound: the DynamoDB adapter on Cloud SQL db-custom-2-7680 (2 vCPU, PostgreSQL 16, us-west1) served 2,974 ops/s of YCSB-A at 16 threads without recorded saturation (src/main/kotlin/t9/prime/equiv/generated/eval/CloudsqlPostgresqlYcsbAT16GoYcsbV1_0_0.kt). Published CPU-bound pgbench reaches 3,101 read-write transactions and 20,289 point reads per vCPU-second (AWS z1d.2xlarge, PostgreSQL 14.5), so actual capacity is likely higher. Reads and writes share one coefficient: at the same adapter version, read-only YCSB-C was not faster than 50%-update YCSB-A.
- Log-broker throughput (capacityStreamMiBPerVcpuSecond 20 at 0.5 utilization, 4 GiB RAM per vCPU) is provider-documented by Google Managed Service for Apache Kafka sizing (https://docs.cloud.google.com/managed-service-for-apache-kafka/docs/plan-cluster-size): write-equivalent bytes are replicated writes plus a quarter of reads. Producer batches below 10 KB lower per-CPU throughput; that penalty is not modeled.
- Disk utilization 0.8 is provider-documented headroom below Cloud SQL automatic storage increase, which triggers near 91-95% full (https://docs.cloud.google.com/sql/docs/postgres/instance-settings). The 20 GiB reserve exceeds PostgreSQL’s 1 GB default max_wal_size; the remainder of that reserve is unmeasured.
- CPU tiers, 4 GiB per vCPU, at most 6.5 GiB per vCPU, 96 vCPU and 65,536 GiB disk follow Cloud SQL Enterprise custom machine limits (provider-documented, same page); 624 GiB is 96 × 6.5. Targets billed per node, unit or throughput unit are sized by their backend instead.
- No public evidence: peak/mean work (2) and the RAM working-set fraction (0.1). Proposed measurements: the p99 one-minute rate over the monthly mean from customer CloudWatch metrics; the buffer hit ratio while stepping RAM under a fixed YCSB-B load.
- Stored GiB already includes the origin family’s physical footprint assumptions; no second storage amplification is applied.
- The workload family already selected resource-hours; the throughput coefficient is not applied again.
- Copies and allocation fractions change cost only; they do not increase modeled primary capacity.
- Cache resident GiB is RAM provenance. Family-selected RAM-hours cover the working set;
- no SSD allocation is modeled. Persistence, snapshots and backup disks remain excluded.
- Only the selected native meter varies; other usage quantities and assumptions retain their displayed defaults. Editable authored planning guesses, not verified provider tariffs, benchmark measurements or a commercial quote. Other native meters retain their explicitly displayed default quantities.
- Planning estimate · editable authored rates and sizing assumptions dated 2026-10-22; not verified provider prices. eastus → us-central1, USD/month.
- Source prices are reference charges, not an invoice. Target lines cover selected service usage/configuration only; adapter hosting and Tensor9 fees are excluded.
- Explicit tariff samples are not performance measurements or capacity qualification. No interpolation or break-even guarantee is implied.
- Variant assumptions show the first axis sample; any axis-dependent configuration is described by this curve’s workload note.
- Rates are cited provider list prices, editable for discounts, commitments or another region. Workload translation and capacity coefficients remain editable planning assumptions, not benchmark measurements or a commercial quote.
- Default-zero rates are explicit assumptions, not evidence that the deployed service or resource is free.
- Provisioned-unit minimums use an editable approximate allocation floor. Modeled target service cost is max(usage/allocation, minimum), with billable network, durable staging and dependent sinks added separately; actual RU/TU sizing, scaling increments and throughput remain unqualified.
- Durable staging is priced once: provisioned targets include adapter state in their selected allocation; native targets add a separate staging allocation when required. Adapter hosting is a separate allocation and must exclude resources already priced as staging, workers or target capacity.
- A declared adapter mapping and cost model do not establish implementation availability or service equivalence.
- This exact directed mapping has a design profile. Cost modeling does not establish an implemented or deployable adapter.
- Origin unit prices are cited provider list prices; capacity coefficients are editable authored planning guesses, not measured capacity.
- The origin is the exact registered azure::1.0.0::cache::redis identity. Renamed products and future aliases require explicit mapping updates.
- Source allocated CPU-hours and memory-hours establish independent minimum target allocation. Neither management API requests nor a key-operation count is an instance count.
- Peak weighted key-operation work and resident data can promote the allocation above those minima. CPU rounds to whole cores and RAM to quarter GiB.
- CPU and RAM are aggregate resources over 730 hours. Selected backend tariffs own replica count, availability configuration and actual instance shapes.
- A multi-core estimate assumes the workload can be partitioned. Redis command execution, hot keys, cross-key transactions and clustering can prevent linear scale.
- Zero allocated resources and zero workload do not prove target scale-to-zero; the selected backend may retain a provisioned minimum.
- Azure Cache for Redis bills per cache size; cache-hours times the size’s memory set the RAM minimum and CPU follows the selected memory shape.
- Google Cloud bills Memorystore for Redis per provisioned capacity GiB-hour in 1-second increments with no separate CPU charge. In us-central1 Basic tier lists USD 0.049 (M1, 1-4 GiB), 0.027 (M2, 5-10 GiB), 0.023 (M3), 0.019 (M4) and 0.016 (M5) per GiB-hour; Standard tier lists 0.064, 0.054, 0.046, 0.035 and 0.03 (https://cloud.google.com/memorystore/docs/redis/pricing). The rate is Basic M2; the two-copy variant equals Standard M2. Other capacity tiers, read replicas and committed-use discounts change the rate. Memorystore has only private endpoints, so selected network is priced at the listed inter-region egress within North America. The CPU rate is zero because capacity GiB is the billed quantity, and the billed capacity is the cache family’s selected RAM rather than the generic planning CPU tier’s RAM; key-operation CPU demand raises cost only through the family’s RAM-per-CPU shape, which approximates managed throughput growing with capacity and is not a measured fit. The capacity charge and the minimum compare using their maximum, not their sum.
- Cache storedGiB represents resident RAM footprint, not billable SSD. Persistence, snapshots and backup disks require a separate explicit allocation.
- Row-store throughput (capacityOpsPerVcpuSecond, default 1500) is measured-by-tensor9 as a lower bound: the DynamoDB adapter on Cloud SQL db-custom-2-7680 (2 vCPU, PostgreSQL 16, us-west1) served 2,974 ops/s of YCSB-A at 16 threads without recorded saturation (src/main/kotlin/t9/prime/equiv/generated/eval/CloudsqlPostgresqlYcsbAT16GoYcsbV1_0_0.kt). Published CPU-bound pgbench reaches 3,101 read-write transactions and 20,289 point reads per vCPU-second (AWS z1d.2xlarge, PostgreSQL 14.5), so actual capacity is likely higher. Reads and writes share one coefficient: at the same adapter version, read-only YCSB-C was not faster than 50%-update YCSB-A.
- Log-broker throughput (capacityStreamMiBPerVcpuSecond 20 at 0.5 utilization, 4 GiB RAM per vCPU) is provider-documented by Google Managed Service for Apache Kafka sizing (https://docs.cloud.google.com/managed-service-for-apache-kafka/docs/plan-cluster-size): write-equivalent bytes are replicated writes plus a quarter of reads. Producer batches below 10 KB lower per-CPU throughput; that penalty is not modeled.
- Disk utilization 0.8 is provider-documented headroom below Cloud SQL automatic storage increase, which triggers near 91-95% full (https://docs.cloud.google.com/sql/docs/postgres/instance-settings). The 20 GiB reserve exceeds PostgreSQL’s 1 GB default max_wal_size; the remainder of that reserve is unmeasured.
- CPU tiers, 4 GiB per vCPU, at most 6.5 GiB per vCPU, 96 vCPU and 65,536 GiB disk follow Cloud SQL Enterprise custom machine limits (provider-documented, same page); 624 GiB is 96 × 6.5. Targets billed per node, unit or throughput unit are sized by their backend instead.
- No public evidence: peak/mean work (2) and the RAM working-set fraction (0.1). Proposed measurements: the p99 one-minute rate over the monthly mean from customer CloudWatch metrics; the buffer hit ratio while stepping RAM under a fixed YCSB-B load.
- Stored GiB already includes the origin family’s physical footprint assumptions; no second storage amplification is applied.
- The workload family already selected resource-hours; the throughput coefficient is not applied again.
- Copies and allocation fractions change cost only; they do not increase modeled primary capacity.
- Cache resident GiB is RAM provenance. Family-selected RAM-hours cover the working set;
- no SSD allocation is modeled. Persistence, snapshots and backup disks remain excluded.
- Azure Retail Prices API: https://prices.azure.com/api/retail/prices
- Memorystore for Redis pricing: https://cloud.google.com/memorystore/docs/redis/pricing
- Replication traffic, snapshots, persistence write IOPS, network egress, cluster management premiums, licenses and migration.
- Command-specific complexity, Lua/scripts, module behavior, eviction/expiry churn, blocking commands, multi-key locality and benchmark-qualified latency.
- Taxes, discounts, credits and free-tier allowances unless explicitly reflected in edited rates.
- Unmodeled dependent services, task execution and operations outside the selected workload family.
plan-88d38420bfbc627f193029e781b7a9e0c528e6fb / 2026-10-22.planning.2. Curve: workload-2.
Sources: Azure Retail Prices API, Memorystore for Redis pricing.
Azure Cache for Redis allocated cache capacity · Resident logical cache data
Estimated monthly service charges by Resident logical cache data. Adapter hosting and Tensor9 fees are excluded. Source: eastus; target: us-central1; currency: USD.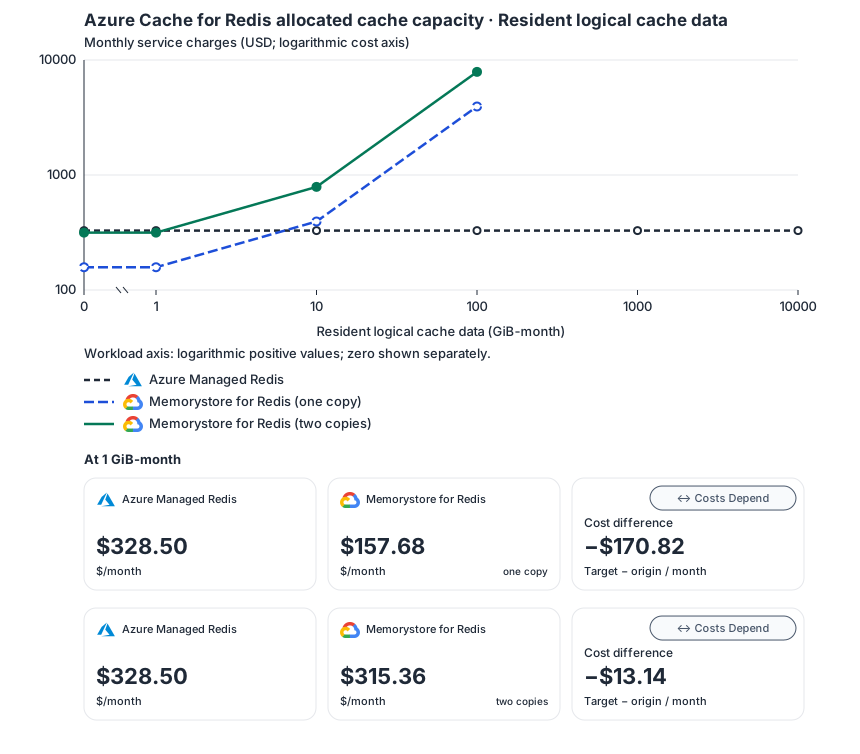
Estimated allocation from planning assumptions; not benchmark calibrated.
The sizing policy grows compute with translated work and peak headroom, memory with compute and working set, and disk with resident working state and reserve. Monthly usage is distinct from resident data; each workload’s assumptions define the translation. HA changes pricing, not this policy’s throughput estimate. Unpriced workloads exceed the policy’s configuration range; no silent vertical cap or automatic sharding is assumed.
- Row-store throughput (capacityOpsPerVcpuSecond, default 1500) is measured-by-tensor9 as a lower bound: the DynamoDB adapter on Cloud SQL db-custom-2-7680 (2 vCPU, PostgreSQL 16, us-west1) served 2,974 ops/s of YCSB-A at 16 threads without recorded saturation (src/main/kotlin/t9/prime/equiv/generated/eval/CloudsqlPostgresqlYcsbAT16GoYcsbV1_0_0.kt). Published CPU-bound pgbench reaches 3,101 read-write transactions and 20,289 point reads per vCPU-second (AWS z1d.2xlarge, PostgreSQL 14.5), so actual capacity is likely higher. Reads and writes share one coefficient: at the same adapter version, read-only YCSB-C was not faster than 50%-update YCSB-A.
- Log-broker throughput (capacityStreamMiBPerVcpuSecond 20 at 0.5 utilization, 4 GiB RAM per vCPU) is provider-documented by Google Managed Service for Apache Kafka sizing (https://docs.cloud.google.com/managed-service-for-apache-kafka/docs/plan-cluster-size): write-equivalent bytes are replicated writes plus a quarter of reads. Producer batches below 10 KB lower per-CPU throughput; that penalty is not modeled.
- Disk utilization 0.8 is provider-documented headroom below Cloud SQL automatic storage increase, which triggers near 91-95% full (https://docs.cloud.google.com/sql/docs/postgres/instance-settings). The 20 GiB reserve exceeds PostgreSQL’s 1 GB default max_wal_size; the remainder of that reserve is unmeasured.
- CPU tiers, 4 GiB per vCPU, at most 6.5 GiB per vCPU, 96 vCPU and 65,536 GiB disk follow Cloud SQL Enterprise custom machine limits (provider-documented, same page); 624 GiB is 96 × 6.5. Targets billed per node, unit or throughput unit are sized by their backend instead.
- No public evidence: peak/mean work (2) and the RAM working-set fraction (0.1). Proposed measurements: the p99 one-minute rate over the monthly mean from customer CloudWatch metrics; the buffer hit ratio while stepping RAM under a fixed YCSB-B load.
- Stored GiB already includes the origin family’s physical footprint assumptions; no second storage amplification is applied.
- The workload family already selected resource-hours; the throughput coefficient is not applied again.
- Copies and allocation fractions change cost only; they do not increase modeled primary capacity.
- Cache resident GiB is RAM provenance. Family-selected RAM-hours cover the working set;
- no SSD allocation is modeled. Persistence, snapshots and backup disks remain excluded.
- Only the selected native meter varies; other usage quantities and assumptions retain their displayed defaults. Editable authored planning guesses, not verified provider tariffs, benchmark measurements or a commercial quote. Other native meters retain their explicitly displayed default quantities.
- Planning estimate · editable authored rates and sizing assumptions dated 2026-10-22; not verified provider prices. eastus → us-central1, USD/month.
- Source prices are reference charges, not an invoice. Target lines cover selected service usage/configuration only; adapter hosting and Tensor9 fees are excluded.
- Explicit tariff samples are not performance measurements or capacity qualification. No interpolation or break-even guarantee is implied.
- Variant assumptions show the first axis sample; any axis-dependent configuration is described by this curve’s workload note.
- Rates are cited provider list prices, editable for discounts, commitments or another region. Workload translation and capacity coefficients remain editable planning assumptions, not benchmark measurements or a commercial quote.
- Default-zero rates are explicit assumptions, not evidence that the deployed service or resource is free.
- Provisioned-unit minimums use an editable approximate allocation floor. Modeled target service cost is max(usage/allocation, minimum), with billable network, durable staging and dependent sinks added separately; actual RU/TU sizing, scaling increments and throughput remain unqualified.
- Durable staging is priced once: provisioned targets include adapter state in their selected allocation; native targets add a separate staging allocation when required. Adapter hosting is a separate allocation and must exclude resources already priced as staging, workers or target capacity.
- A declared adapter mapping and cost model do not establish implementation availability or service equivalence.
- This exact directed mapping has a design profile. Cost modeling does not establish an implemented or deployable adapter.
- Origin unit prices are cited provider list prices; capacity coefficients are editable authored planning guesses, not measured capacity.
- The origin is the exact registered azure::1.0.0::cache::redis identity. Renamed products and future aliases require explicit mapping updates.
- Source allocated CPU-hours and memory-hours establish independent minimum target allocation. Neither management API requests nor a key-operation count is an instance count.
- Peak weighted key-operation work and resident data can promote the allocation above those minima. CPU rounds to whole cores and RAM to quarter GiB.
- CPU and RAM are aggregate resources over 730 hours. Selected backend tariffs own replica count, availability configuration and actual instance shapes.
- A multi-core estimate assumes the workload can be partitioned. Redis command execution, hot keys, cross-key transactions and clustering can prevent linear scale.
- Zero allocated resources and zero workload do not prove target scale-to-zero; the selected backend may retain a provisioned minimum.
- Azure Cache for Redis bills per cache size; cache-hours times the size’s memory set the RAM minimum and CPU follows the selected memory shape.
- Google Cloud bills Memorystore for Redis per provisioned capacity GiB-hour in 1-second increments with no separate CPU charge. In us-central1 Basic tier lists USD 0.049 (M1, 1-4 GiB), 0.027 (M2, 5-10 GiB), 0.023 (M3), 0.019 (M4) and 0.016 (M5) per GiB-hour; Standard tier lists 0.064, 0.054, 0.046, 0.035 and 0.03 (https://cloud.google.com/memorystore/docs/redis/pricing). The rate is Basic M2; the two-copy variant equals Standard M2. Other capacity tiers, read replicas and committed-use discounts change the rate. Memorystore has only private endpoints, so selected network is priced at the listed inter-region egress within North America. The CPU rate is zero because capacity GiB is the billed quantity, and the billed capacity is the cache family’s selected RAM rather than the generic planning CPU tier’s RAM; key-operation CPU demand raises cost only through the family’s RAM-per-CPU shape, which approximates managed throughput growing with capacity and is not a measured fit. The capacity charge and the minimum compare using their maximum, not their sum.
- Cache storedGiB represents resident RAM footprint, not billable SSD. Persistence, snapshots and backup disks require a separate explicit allocation.
- Row-store throughput (capacityOpsPerVcpuSecond, default 1500) is measured-by-tensor9 as a lower bound: the DynamoDB adapter on Cloud SQL db-custom-2-7680 (2 vCPU, PostgreSQL 16, us-west1) served 2,974 ops/s of YCSB-A at 16 threads without recorded saturation (src/main/kotlin/t9/prime/equiv/generated/eval/CloudsqlPostgresqlYcsbAT16GoYcsbV1_0_0.kt). Published CPU-bound pgbench reaches 3,101 read-write transactions and 20,289 point reads per vCPU-second (AWS z1d.2xlarge, PostgreSQL 14.5), so actual capacity is likely higher. Reads and writes share one coefficient: at the same adapter version, read-only YCSB-C was not faster than 50%-update YCSB-A.
- Log-broker throughput (capacityStreamMiBPerVcpuSecond 20 at 0.5 utilization, 4 GiB RAM per vCPU) is provider-documented by Google Managed Service for Apache Kafka sizing (https://docs.cloud.google.com/managed-service-for-apache-kafka/docs/plan-cluster-size): write-equivalent bytes are replicated writes plus a quarter of reads. Producer batches below 10 KB lower per-CPU throughput; that penalty is not modeled.
- Disk utilization 0.8 is provider-documented headroom below Cloud SQL automatic storage increase, which triggers near 91-95% full (https://docs.cloud.google.com/sql/docs/postgres/instance-settings). The 20 GiB reserve exceeds PostgreSQL’s 1 GB default max_wal_size; the remainder of that reserve is unmeasured.
- CPU tiers, 4 GiB per vCPU, at most 6.5 GiB per vCPU, 96 vCPU and 65,536 GiB disk follow Cloud SQL Enterprise custom machine limits (provider-documented, same page); 624 GiB is 96 × 6.5. Targets billed per node, unit or throughput unit are sized by their backend instead.
- No public evidence: peak/mean work (2) and the RAM working-set fraction (0.1). Proposed measurements: the p99 one-minute rate over the monthly mean from customer CloudWatch metrics; the buffer hit ratio while stepping RAM under a fixed YCSB-B load.
- Stored GiB already includes the origin family’s physical footprint assumptions; no second storage amplification is applied.
- The workload family already selected resource-hours; the throughput coefficient is not applied again.
- Copies and allocation fractions change cost only; they do not increase modeled primary capacity.
- Cache resident GiB is RAM provenance. Family-selected RAM-hours cover the working set;
- no SSD allocation is modeled. Persistence, snapshots and backup disks remain excluded.
- Azure Retail Prices API: https://prices.azure.com/api/retail/prices
- Memorystore for Redis pricing: https://cloud.google.com/memorystore/docs/redis/pricing
- Replication traffic, snapshots, persistence write IOPS, network egress, cluster management premiums, licenses and migration.
- Command-specific complexity, Lua/scripts, module behavior, eviction/expiry churn, blocking commands, multi-key locality and benchmark-qualified latency.
- Taxes, discounts, credits and free-tier allowances unless explicitly reflected in edited rates.
- Unmodeled dependent services, task execution and operations outside the selected workload family.
plan-88d38420bfbc627f193029e781b7a9e0c528e6fb / 2026-10-22.planning.2. Curve: workload-3.
Sources: Azure Retail Prices API, Memorystore for Redis pricing.
Azure Cache for Redis allocated cache capacity · Allocated source cache-hours
Estimated monthly service charges by Allocated source cache-hours. Adapter hosting and Tensor9 fees are excluded. Source: eastus; target: us-central1; currency: USD.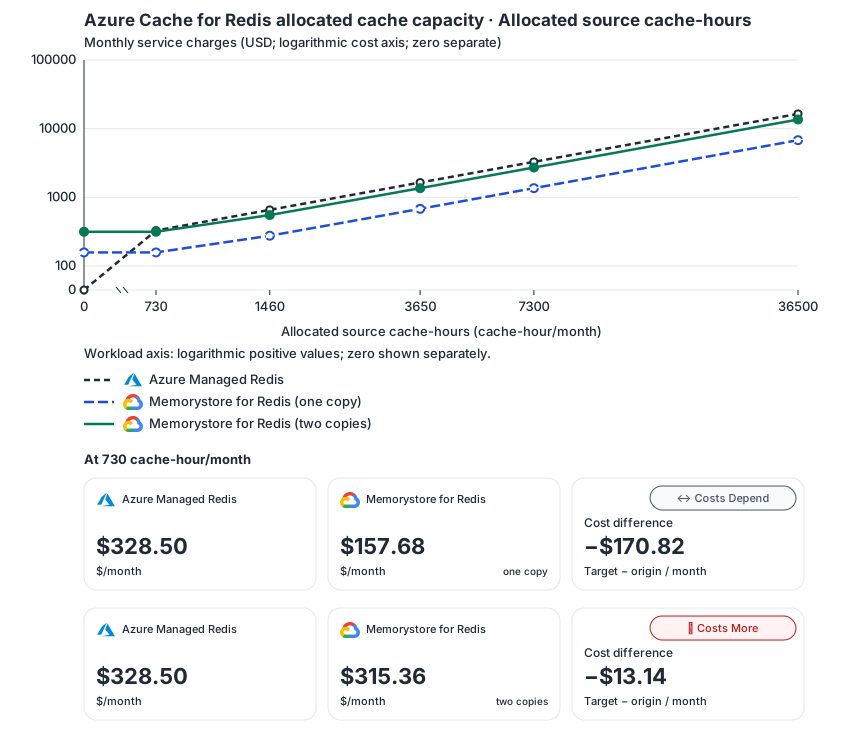
Estimated allocation from planning assumptions; not benchmark calibrated.
The sizing policy grows compute with translated work and peak headroom, memory with compute and working set, and disk with resident working state and reserve. Monthly usage is distinct from resident data; each workload’s assumptions define the translation. HA changes pricing, not this policy’s throughput estimate. Unpriced workloads exceed the policy’s configuration range; no silent vertical cap or automatic sharding is assumed.
- Row-store throughput (capacityOpsPerVcpuSecond, default 1500) is measured-by-tensor9 as a lower bound: the DynamoDB adapter on Cloud SQL db-custom-2-7680 (2 vCPU, PostgreSQL 16, us-west1) served 2,974 ops/s of YCSB-A at 16 threads without recorded saturation (src/main/kotlin/t9/prime/equiv/generated/eval/CloudsqlPostgresqlYcsbAT16GoYcsbV1_0_0.kt). Published CPU-bound pgbench reaches 3,101 read-write transactions and 20,289 point reads per vCPU-second (AWS z1d.2xlarge, PostgreSQL 14.5), so actual capacity is likely higher. Reads and writes share one coefficient: at the same adapter version, read-only YCSB-C was not faster than 50%-update YCSB-A.
- Log-broker throughput (capacityStreamMiBPerVcpuSecond 20 at 0.5 utilization, 4 GiB RAM per vCPU) is provider-documented by Google Managed Service for Apache Kafka sizing (https://docs.cloud.google.com/managed-service-for-apache-kafka/docs/plan-cluster-size): write-equivalent bytes are replicated writes plus a quarter of reads. Producer batches below 10 KB lower per-CPU throughput; that penalty is not modeled.
- Disk utilization 0.8 is provider-documented headroom below Cloud SQL automatic storage increase, which triggers near 91-95% full (https://docs.cloud.google.com/sql/docs/postgres/instance-settings). The 20 GiB reserve exceeds PostgreSQL’s 1 GB default max_wal_size; the remainder of that reserve is unmeasured.
- CPU tiers, 4 GiB per vCPU, at most 6.5 GiB per vCPU, 96 vCPU and 65,536 GiB disk follow Cloud SQL Enterprise custom machine limits (provider-documented, same page); 624 GiB is 96 × 6.5. Targets billed per node, unit or throughput unit are sized by their backend instead.
- No public evidence: peak/mean work (2) and the RAM working-set fraction (0.1). Proposed measurements: the p99 one-minute rate over the monthly mean from customer CloudWatch metrics; the buffer hit ratio while stepping RAM under a fixed YCSB-B load.
- Stored GiB already includes the origin family’s physical footprint assumptions; no second storage amplification is applied.
- The workload family already selected resource-hours; the throughput coefficient is not applied again.
- Copies and allocation fractions change cost only; they do not increase modeled primary capacity.
- Cache resident GiB is RAM provenance. Family-selected RAM-hours cover the working set;
- no SSD allocation is modeled. Persistence, snapshots and backup disks remain excluded.
- Only the selected native meter varies; other usage quantities and assumptions retain their displayed defaults. Editable authored planning guesses, not verified provider tariffs, benchmark measurements or a commercial quote. Other native meters retain their explicitly displayed default quantities.
- Planning estimate · editable authored rates and sizing assumptions dated 2026-10-22; not verified provider prices. eastus → us-central1, USD/month.
- Source prices are reference charges, not an invoice. Target lines cover selected service usage/configuration only; adapter hosting and Tensor9 fees are excluded.
- Explicit tariff samples are not performance measurements or capacity qualification. No interpolation or break-even guarantee is implied.
- Variant assumptions show the first axis sample; any axis-dependent configuration is described by this curve’s workload note.
- Rates are cited provider list prices, editable for discounts, commitments or another region. Workload translation and capacity coefficients remain editable planning assumptions, not benchmark measurements or a commercial quote.
- Default-zero rates are explicit assumptions, not evidence that the deployed service or resource is free.
- Provisioned-unit minimums use an editable approximate allocation floor. Modeled target service cost is max(usage/allocation, minimum), with billable network, durable staging and dependent sinks added separately; actual RU/TU sizing, scaling increments and throughput remain unqualified.
- Durable staging is priced once: provisioned targets include adapter state in their selected allocation; native targets add a separate staging allocation when required. Adapter hosting is a separate allocation and must exclude resources already priced as staging, workers or target capacity.
- A declared adapter mapping and cost model do not establish implementation availability or service equivalence.
- This exact directed mapping has a design profile. Cost modeling does not establish an implemented or deployable adapter.
- Origin unit prices are cited provider list prices; capacity coefficients are editable authored planning guesses, not measured capacity.
- The origin is the exact registered azure::1.0.0::cache::redis identity. Renamed products and future aliases require explicit mapping updates.
- Source allocated CPU-hours and memory-hours establish independent minimum target allocation. Neither management API requests nor a key-operation count is an instance count.
- Peak weighted key-operation work and resident data can promote the allocation above those minima. CPU rounds to whole cores and RAM to quarter GiB.
- CPU and RAM are aggregate resources over 730 hours. Selected backend tariffs own replica count, availability configuration and actual instance shapes.
- A multi-core estimate assumes the workload can be partitioned. Redis command execution, hot keys, cross-key transactions and clustering can prevent linear scale.
- Zero allocated resources and zero workload do not prove target scale-to-zero; the selected backend may retain a provisioned minimum.
- Azure Cache for Redis bills per cache size; cache-hours times the size’s memory set the RAM minimum and CPU follows the selected memory shape.
- Google Cloud bills Memorystore for Redis per provisioned capacity GiB-hour in 1-second increments with no separate CPU charge. In us-central1 Basic tier lists USD 0.049 (M1, 1-4 GiB), 0.027 (M2, 5-10 GiB), 0.023 (M3), 0.019 (M4) and 0.016 (M5) per GiB-hour; Standard tier lists 0.064, 0.054, 0.046, 0.035 and 0.03 (https://cloud.google.com/memorystore/docs/redis/pricing). The rate is Basic M2; the two-copy variant equals Standard M2. Other capacity tiers, read replicas and committed-use discounts change the rate. Memorystore has only private endpoints, so selected network is priced at the listed inter-region egress within North America. The CPU rate is zero because capacity GiB is the billed quantity, and the billed capacity is the cache family’s selected RAM rather than the generic planning CPU tier’s RAM; key-operation CPU demand raises cost only through the family’s RAM-per-CPU shape, which approximates managed throughput growing with capacity and is not a measured fit. The capacity charge and the minimum compare using their maximum, not their sum.
- Cache storedGiB represents resident RAM footprint, not billable SSD. Persistence, snapshots and backup disks require a separate explicit allocation.
- Row-store throughput (capacityOpsPerVcpuSecond, default 1500) is measured-by-tensor9 as a lower bound: the DynamoDB adapter on Cloud SQL db-custom-2-7680 (2 vCPU, PostgreSQL 16, us-west1) served 2,974 ops/s of YCSB-A at 16 threads without recorded saturation (src/main/kotlin/t9/prime/equiv/generated/eval/CloudsqlPostgresqlYcsbAT16GoYcsbV1_0_0.kt). Published CPU-bound pgbench reaches 3,101 read-write transactions and 20,289 point reads per vCPU-second (AWS z1d.2xlarge, PostgreSQL 14.5), so actual capacity is likely higher. Reads and writes share one coefficient: at the same adapter version, read-only YCSB-C was not faster than 50%-update YCSB-A.
- Log-broker throughput (capacityStreamMiBPerVcpuSecond 20 at 0.5 utilization, 4 GiB RAM per vCPU) is provider-documented by Google Managed Service for Apache Kafka sizing (https://docs.cloud.google.com/managed-service-for-apache-kafka/docs/plan-cluster-size): write-equivalent bytes are replicated writes plus a quarter of reads. Producer batches below 10 KB lower per-CPU throughput; that penalty is not modeled.
- Disk utilization 0.8 is provider-documented headroom below Cloud SQL automatic storage increase, which triggers near 91-95% full (https://docs.cloud.google.com/sql/docs/postgres/instance-settings). The 20 GiB reserve exceeds PostgreSQL’s 1 GB default max_wal_size; the remainder of that reserve is unmeasured.
- CPU tiers, 4 GiB per vCPU, at most 6.5 GiB per vCPU, 96 vCPU and 65,536 GiB disk follow Cloud SQL Enterprise custom machine limits (provider-documented, same page); 624 GiB is 96 × 6.5. Targets billed per node, unit or throughput unit are sized by their backend instead.
- No public evidence: peak/mean work (2) and the RAM working-set fraction (0.1). Proposed measurements: the p99 one-minute rate over the monthly mean from customer CloudWatch metrics; the buffer hit ratio while stepping RAM under a fixed YCSB-B load.
- Stored GiB already includes the origin family’s physical footprint assumptions; no second storage amplification is applied.
- The workload family already selected resource-hours; the throughput coefficient is not applied again.
- Copies and allocation fractions change cost only; they do not increase modeled primary capacity.
- Cache resident GiB is RAM provenance. Family-selected RAM-hours cover the working set;
- no SSD allocation is modeled. Persistence, snapshots and backup disks remain excluded.
- Azure Retail Prices API: https://prices.azure.com/api/retail/prices
- Memorystore for Redis pricing: https://cloud.google.com/memorystore/docs/redis/pricing
- Replication traffic, snapshots, persistence write IOPS, network egress, cluster management premiums, licenses and migration.
- Command-specific complexity, Lua/scripts, module behavior, eviction/expiry churn, blocking commands, multi-key locality and benchmark-qualified latency.
- Taxes, discounts, credits and free-tier allowances unless explicitly reflected in edited rates.
- Unmodeled dependent services, task execution and operations outside the selected workload family.
plan-88d38420bfbc627f193029e781b7a9e0c528e6fb / 2026-10-22.planning.2. Curve: workload-4.
Sources: Azure Retail Prices API, Memorystore for Redis pricing.
See the service catalog for operation coverage, supported directions and backend limitations.