

- Coverage by target cloud
- How the backends compare
- On Google Cloud
- On Azure, OCI, and Private Kubernetes
- On Azure
- On OCI
- Costs
- Service level agreements
- SQS to Cosmos DB
- SQS (Simple Queue Service, Classic) to PostgreSQL Flexible Server
- SQS (Simple Queue Service, Classic) to Azure Queue Storage
- SQS (Simple Queue Service, Classic) to Azure Service Bus
- SQS to Cloud SQL for PostgreSQL
- SQS (Simple Queue Service, Classic) to Pub/Sub
- SQS (Simple Queue Service, Classic) to OCI Queue
- SQS (Simple Queue Service, Classic) to PostgreSQL
- SQS (Simple Queue Service, Classic) to Scaleway Queues (SQS-compatible)
- SQS (Simple Queue Service, Classic) to Scaleway Managed Database for PostgreSQL
- Debug this service
Coverage by target cloud
How the backends compare
Each row compares a capability of SQS (Simple Queue Service, Classic) with its adaptation on each backend. A dash means this row is not stated for that backend.Max adaptation
On Google Cloud
Via Pub/Sub
How it works
Tensor9 adds an adapter, a proxy process, to your application pod in your Google Cloud environment and setsAWS_ENDPOINT_URL_SQS to its local address. Your application keeps its SQS SDK and its SendMessage and ReceiveMessage calls. The adapter translates them to Pub/Sub and returns SQS responses, including error codes and recomputed MD5 checksums for the body and attributes.
Each standard SQS queue maps to a Pub/Sub topic for sending and a subscription for receiving: queue q becomes topic q and subscription q-sub. The message body becomes the Pub/Sub message data. Message attributes keep their type and their string or binary values in Pub/Sub attributes, and come back as SQS attributes on receive. Only standard queues are supported; FIFO ordering and deduplication need another backend.


An SQS queue q becomes a Pub/Sub topic q and subscription q-sub . The application calls the adapter through its existing SQS SDK.
Architecture
The adapter signs in to Pub/Sub with your Workload Identity, with no static credentials. Pub/Sub stores the messages, and Tensor9 stores the queue settings you declare. Receive buffers and acknowledgement IDs live in each adapter process and do not survive a restart. Google operates Pub/Sub’s durability, delivery and availability; Tensor9 operates the adapter. For each queue the adapter keeps two long-lived connections. A publisher per topic, opened on the first send, batches concurrent sends to that topic into one Pub/SubPublish request instead of one request per SendMessage. A StreamingPull receiver per subscription keeps the message stream open and puts each message into a small, bounded buffer that ReceiveMessage reads, instead of making a blocking pull on every call. DeleteQueue closes both. Messages still in the buffer are released, so Pub/Sub delivers them again promptly rather than after the full deadline.
- Messages stay in Pub/Sub. They remain in Pub/Sub when an adapter restarts; local buffers and acknowledgement IDs do not, and unacknowledged messages can be delivered again.
- Two limits control buffering. Pub/Sub limits how many delivered messages can wait for acknowledgement. The adapter also limits its local buffer, so idle consumers do not hold an unbounded number of messages whose acknowledgement deadlines are running.


Pub/Sub stores the messages. The adapter keeps a small receive buffer and the acknowledgement IDs for its open stream.
Receiving messages
A backgroundStreamingPull receiver reads the subscription continuously into a bounded buffer, and ReceiveMessage reads from that buffer. A message that arrives while a call is waiting is returned straight away, without another poll.
WaitTimeSeconds sets how long to wait for the first message, at most 20 seconds. Zero checks once without waiting, and an empty result is valid. Once the first message is there, the adapter fills the rest of the batch from buffered messages without waiting again. MaxNumberOfMessages is kept between 1 and 10. The buffer rides out short gaps in receiving while limiting how many messages it holds when consumers are idle. Use Google Cloud monitoring to size the buffer and to find publish or delivery bottlenecks.


ReceiveMessage reads the buffer and waits up to WaitTimeSeconds, at most 20 seconds, for the first message. A message that arrives during the wait is returned at once.
Visibility & receipt handles
VisibilityTimeout maps to the subscription’s acknowledgement deadline. A queue default must be 10–600 seconds. A ReceiveMessage override or ChangeMessageVisibility also accepts zero, which makes the message available at once. Other values are rejected, not adjusted. A per-call ReceiveMessage override changes the returned messages only when it differs from the queue default. Deadlines are not extended automatically, so a message left in the buffer past its deadline can be delivered again; consumers must handle duplicates.
The receipt handle is the Pub/Sub acknowledgement ID. It works only while the StreamingPull receiver that got it is running. DeleteQueue, PurgeQueue or a stream error closes that receiver, and the next receive opens a new one; older handles then stop working. Unacknowledged messages that Pub/Sub still keeps can come back with new handles; deleted, purged or expired messages are not promised to return. Receive such messages again before deleting or extending them. DeleteMessage acknowledges one ID, and a batch delete acknowledges the IDs together.


Queue visibility defaults must be 10-600 seconds; per-message visibility also accepts 0. Receipt handles are Pub/Sub acknowledgement IDs and do not survive a restart.
Dead-letter & delivery
Pub/Sub handles dead-letter delivery. An SQSRedrivePolicy sets the subscription’s delivery-attempt limit from maxReceiveCount. The adapter turns deadLetterTargetArn, given as an SQS-style ARN or a bare name, into the topic projects/<id>/topics/<name>. Pub/Sub forwards on a best-effort basis, so a message can move before or after that count. Counting attempts needs the dead-letter policy and the required IAM permissions. The destination is a Pub/Sub topic, not another queue as on SQS.
Delivery is at least once. ApproximateReceiveCount is Pub/Sub’s delivery-attempt count, available only when the subscription has a dead-letter policy; otherwise every receive reports 1. SendMessage uses the topic’s batching and returns the message ID and MD5 checksums. SendMessageBatch sends one Pub/Sub request and matches the returned message IDs to entries by position. An entry that fails validation is reported on its own without failing the whole batch.


Pub/Sub forwards messages to a dead-letter topic on a best-effort basis. Delivery-attempt counts need a dead-letter policy and IAM permissions.
Limitations
Where SQS and Pub/Sub differ- Messages are limited to 256 KiB by default. The adapter checks the declared
MaximumMessageSizebefore publishing, including each batch entry. The default is 262144 bytes (256 KiB), below native SQS’s 1 MiB limit. Pub/Sub’s own 10 MB limit does not raise the declared limit. - Retention shorter than ten minutes is not supported. Queue creation and
SetQueueAttributesapplyMessageRetentionPeriodto the subscription’s retention. Pub/Sub needs at least ten minutes, so shorter values are rejected; anything up to 14 days works. Reading the settings returns your declared value, not Pub/Sub’s default. - Approximate message counts are not supported.
ApproximateNumberOfMessages,ApproximateNumberOfMessagesNotVisibleandApproximateNumberOfMessagesDelayedcome back empty, because Pub/Sub does not report queue depth cheaply. Use Google Cloud monitoring for depth. - Acknowledgement deadlines behave differently: they are not extended automatically. The receiver does not renew a delivered message’s deadline, and the queue default must be 10-600 seconds. A message buffered past its deadline can be delivered again, so consumers must handle duplicates.
- Receipt handles behave differently: they do not survive a restart. The handle is the Pub/Sub acknowledgement ID, and it stops working after
DeleteQueue,PurgeQueueor a stream error. Unacknowledged messages that Pub/Sub still keeps can come back with a new handle. - Dead-letter limits behave differently:
maxReceiveCountmust be 5-100. Pub/Sub’s delivery-attempt limit accepts only 5 to 100, so aRedrivePolicyoutside that range is rejected, although SQS accepts 1 to 1000. ApproximateReceiveCountbehaves differently: it needs a dead-letter policy. It is Pub/Sub’s delivery-attempt count, which Pub/Sub provides only with a correctly configured policy and IAM permissions, and the count can reset. A queue without one reports1on every receive.- Delayed delivery is not supported. Pub/Sub cannot hold individual messages for later delivery. Queue- and message-level
DelaySecondsmust be zero; other values are rejected.


The adapter checks message size against the declared limit and sets the subscription’s retention from the queue’s retention period.
Other considerations
- Moving from AWS. The Pub/Sub topic
qand subscriptionq-substart empty, and existing SQS messages are not migrated. Drain the source queue, or write to both queues, during the transition. Your SQS calls and checksum checks stay the same. - Who operates what. Google operates Pub/Sub’s durability, delivery and availability. Tensor9 operates the SQS adapter.
- If the adapter stops. Published messages stay in Pub/Sub; only the small receive buffer is in the adapter’s memory. On an orderly shutdown it releases buffered messages for redelivery. After a crash, unacknowledged messages are delivered again when their deadlines expire.
- Cost. Pub/Sub bills by the volume of data sent through it. The adapter adds no metered usage of its own.
- What to monitor. Approximate message counts come back empty, so read depth, latency, throughput and cost from Pub/Sub’s metrics in Google Cloud monitoring, not from SQS CloudWatch metrics.
Example monthly charges
This Tensor9 BYOC scenario estimates service charges for the named origin and target services. Adapter hosting and commercial Tensor9 fees need separate allocations. How Tensor9 estimates costs explains the method and what the estimates include.Monthly cost by SQS request rate
Reference monthly service charges by API requests/s. Adapter hosting and Tensor9 fees are excluded. Source: us-east-1; target: us-central1; currency: USD.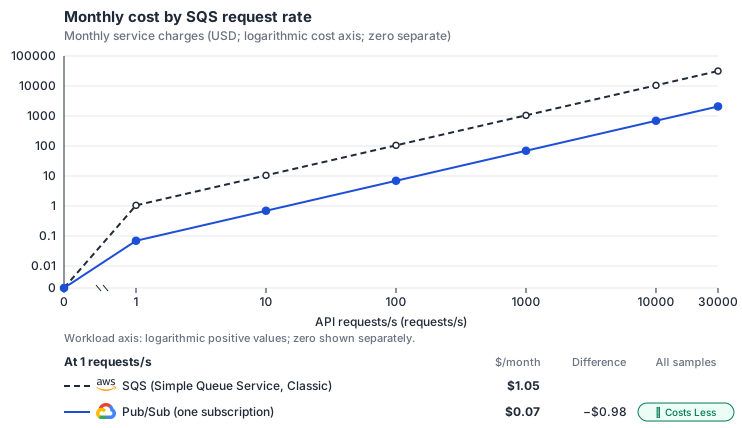
- 1 KiB messages; unbatched send, receive and delete requests in a 1:1:1 mix, with no empty receives or redeliveries. 730 hours/month; one SQS billing unit per API request. Pub/Sub uses one subscription and 64 bytes of assumed overhead.
- Monthly AWS source usage in us-east-1, priced at the 2026-10-18 reference list rates before free allowances, discounts, credits and tax; not the uploaded invoice total. Rates as of 2026-10-18: us-east-1 → us-central1, USD/month.
- Source prices are reference charges, not an invoice. Target lines cover selected service usage/configuration only; adapter hosting and Tensor9 fees are excluded.
- Samples of explicit prices are not performance measurements or capacity qualification. No interpolation or break-even guarantee is implied.
- Variant assumptions show the first axis sample; any axis-dependent configuration is described by this curve’s workload note.
- One pull subscription, Standard SQS semantics compatible with this mapping, representative message size and batching.
- Pub/Sub publish and delivery each cost USD 40/TiB, with a 1,000-byte minimum per request. Metadata overhead is an explicit assumption.
- Source usage is priced at reference rates; source lines are not actual invoice charges. Free or discounted usage still consumes target resources.
- AWS Standard SQS pricing: https://aws.amazon.com/sqs/pricing/
- Pub/Sub pricing: https://cloud.google.com/pubsub/pricing/
- Free allowances, negotiated discounts, credits, tax and one-time migration charges.
- Charges not listed in the breakdown, including additional network transfer, backups and encryption/KMS.
- Application compute changes, operational labor and portfolio-wide sharing or deduplication of infrastructure.
- Pub/Sub retained-message storage, snapshots, extra subscriptions and transformations; SQS delay/FIFO features and visibility-extension traffic.
sqs-pubsub / 2026-10-18.4. Curve: request-rate.
Sources: AWS Standard SQS pricing, Pub/Sub pricing.
SQS → Google Cloud Pub/Sub: Reference monthly workload. Monthly AWS usage charges at the 2026-10-18 reference list rates in us-east-1, before free allowances, discounts, credits and tax.
Scenario source region: us-east-1. Scenario target region: us-central1. Currency: USD.
- Free allowances, negotiated discounts, credits, tax and one-time migration charges.
- Charges not listed in the breakdown, including additional network transfer, backups and encryption/KMS.
- Application compute changes, operational labor and portfolio-wide sharing or deduplication of infrastructure.
- Pub/Sub retained-message storage, snapshots, extra subscriptions and transformations; SQS delay/FIFO features and visibility-extension traffic.
- Inferred original messages: 100,000,000 messages/month.
- One pull subscription, Standard SQS semantics compatible with this mapping, representative message size and batching.
- Pub/Sub publish and delivery each cost USD 40/TiB, with a 1,000-byte minimum per request. Metadata overhead is an explicit assumption.
sqs-pubsub / 2026-10-18.4. Scenario: sqs-pubsub-reference.
Sources: AWS Standard SQS pricing, Pub/Sub pricing.
Via Cloud SQL for PostgreSQL
PostgreSQL hosting
Google operates Cloud SQL for PostgreSQL, including database backups and HA. The adapter uses short-lived Cloud SQL IAM tokens as database passwords, without an Auth Proxy or static password. Queue data stays outside the customer’s Kubernetes cluster and survives its rebuild. Tensor9 operates the queue schema and adapter. Queues start empty; existing SQS messages are not migrated. Drain the source or coordinate dual writes before cutover.PostgreSQL queue behavior
Tensor9 adds an adapter, a proxy process, to your application pod and setsAWS_ENDPOINT_URL_SQS to its local address. Your application keeps its SQS SDK and its SendMessage and ReceiveMessage calls. The adapter performs them in PostgreSQL and returns SQS responses, error codes and MD5 checksums.
Each queue is a PostgreSQL table with one row per message. Sending, receiving, deleting, delays, visibility, dead-letter delivery and message counts all work on those rows. Standard queues provide at-least-once delivery with best-effort ordering.


The application keeps its SQS SDK. The adapter stores each queue in a PostgreSQL table.
Architecture
The adapter keeps all queue state in PostgreSQL, including messages and receipt handles, so adapter instances can restart or scale out without losing track of in-flight messages. On Cloud SQL and Azure Flexible Server it signs in with short-lived Cloud SQL IAM or Microsoft Entra tokens used as database passwords, so no static secret is stored. When the stack is deployed, Tensor9 creates one database per appliance and one table per declared queue. Each row holds the message body and attributes, its message group, its visibility time, its receipt handle, its receive count and the time it was sent. A Standard queue hands out messages in arrival order, with best-effort ordering under concurrent traffic. A dead-letter queue is another queue table, and a background task deletes messages older than the queue’s retention period. CloudNativePG, Cloud SQL for PostgreSQL, Azure Flexible Server and Scaleway use the same adapter code and tables. They differ in where the data lives: the managed servers run outside your Kubernetes cluster, while CloudNativePG runs inside it. See the rebuild limitation below.

Each queue, including each dead-letter queue, is a PostgreSQL table. The same adapter runs on every supported PostgreSQL host.
Receiving messages
One database step selects messages whose visibility timeout has passed, oldest first, up to the requested batch size. In the same step it gives each a new receipt handle, hides it for the visibility timeout, adds one to its receive count and returns it. Messages another receiver is taking at that moment are skipped. Standard queues provide best-effort ordering. When the visibility timeout passes, the message can be delivered again; that does not stop a worker still processing the earlier copy.ApproximateReceiveCount is the actual number of receives, not an estimate. The MD5 checksums of the body and attributes are recomputed, so your SDK’s checks pass. DelaySeconds sets when a message first becomes visible. Long polling waits up to WaitTimeSeconds (at most 20 seconds) and returns as soon as a message is available. SendMessageBatch inserts all entries at once and reports a result for each entry. Message bodies are stored in the queue table.


Two receivers never get the same message at the same time. ApproximateReceiveCount is the actual receive count.
Receipt handles & visibility
Each receive saves a new receipt handle with the message.DeleteMessage and ChangeMessageVisibility find the message by that handle, including after an adapter restart or through another adapter instance.
A delete or visibility change whose handle matches no message returns ReceiptHandleIsInvalid. That includes a message already deleted, or received again under a newer handle. The visibility timeout defaults to 30 seconds. ChangeMessageVisibility can extend it with no lock-duration maximum, and zero makes the message available again immediately. Retention can delete a message while it is in flight.


Receipt handles are saved with messages, so they still work after an adapter restart. Visibility has no lock-duration limit.
Dead-letter & retention
During a receive, one database transaction moves messages that have reachedmaxReceiveCount to the dead-letter queue and hands out the rest. Both happen or neither does, so an interrupted receive cannot remove a message from the source without its copy in the DLQ. The DLQ supports the same operations and retention cleanup. A moved message keeps its MessageId and SentTimestamp, gains DeadLetterQueueSourceArn, and its ApproximateReceiveCount keeps counting receives on both queues. A redrive policy on the DLQ itself counts only receives on the DLQ, and the DLQ’s retention runs from the original send time.
A background task deletes messages sent longer ago than the queue’s retention period, including messages in flight; receiving does not reset that time. The retention period defaults to four days and is kept between 60 seconds and 14 days, so a missing or too-short value cannot delete new messages straight away. One worker per database removes expired messages in batches, pauses during database maintenance, and continues if one queue fails. Limits on rows per pass and time per batch cap the load.


One transaction moves failed messages to the DLQ and hands out the rest. A background task removes messages older than their retention period, kept between 60 seconds and 14 days.
FIFO queues
For strict per-message-group ordering and five-minute duplicate-send suppression, use SQS FIFO. Standard queues provide at-least-once delivery with best-effort ordering.Limitations
Where SQS and the PostgreSQL adapter differ- Throughput behaves differently: one PostgreSQL server serves every queue. All of an appliance’s queues share one server, so its capacity bounds peak throughput and a heavy queue can affect the others. In Tensor9’s round-trip test of a moderate-rate Standard queue, the adapter matched SQS throughput (about 300 vs 286 ops/s) with a lower p99 (140 ms vs 172 ms) but a slower median (p50 24 ms vs 15 ms). That is not a measured ceiling, and it does not cover FIFO queues or every host.
- Queue data on CloudNativePG does not survive a cluster rebuild. CloudNativePG keeps queue data inside the appliance cluster, so a full rebuild loses it. The managed hosts keep it on a provider-operated server outside the cluster, where it survives a rebuild. All hosts use the same queue implementation.
- Messages are limited to 256 KiB by default. The adapter’s default limit is 262144 bytes, while native SQS now accepts up to 1 MiB. Sends are checked against the queue’s declared limit.
- Stale receipt handles behave differently: they return an error.
DeleteMessageandChangeMessageVisibilityreturnReceiptHandleIsInvalidwhen no message matches the handle. - Retention behaves differently: expired messages are removed periodically. An expired message can remain until the next cleanup pass. Retention is kept between 60 seconds and 14 days; a too-short value is raised to 60 seconds so that new messages are not deleted.
- Approximate counts behave differently: they are exact at query time.
ApproximateNumberOfMessagesandApproximateNumberOfMessagesNotVisiblecount the visible and hidden messages in the queue’s table, though they can still change under concurrent traffic.ApproximateNumberOfMessagesDelayedis always zero. - Queue creation behaves differently: queues are created when the stack is deployed. Tensor9 creates the database and each queue’s table, and its dead-letter table, at deploy time.
CreateQueue,DeleteQueueandSetQueueAttributesact on those tables. Switching a queue between Standard and FIFO is rejected, because it would replace the queue.
Other considerations
- Moving from AWS. The database and queue tables start empty, and existing SQS messages are not migrated. Drain the source queue, or write to both queues during the transition.
- Removing queues. Each queue is created in one step, so a crash never leaves a half-created queue. When a queue is removed from the stack, Tensor9 deletes only queues it created; any other queue is detached and left in place. A queue that still holds messages is not deleted unless deletion is forced.
- Who operates what. On the managed hosts, the provider operates the database’s durability, backups and high availability, and Tensor9 operates the adapter. On CloudNativePG, Tensor9 operates the database inside your cluster.
Example monthly charges
This Tensor9 BYOC scenario estimates service charges for the named origin and target services. Adapter hosting and commercial Tensor9 fees need separate allocations. How Tensor9 estimates costs explains the method and what the estimates include.Monthly cost by SQS request rate
Reference monthly service charges by Average API requests/s. Adapter hosting and Tensor9 fees are excluded. Source: us-east-1; target: us-central1; currency: USD.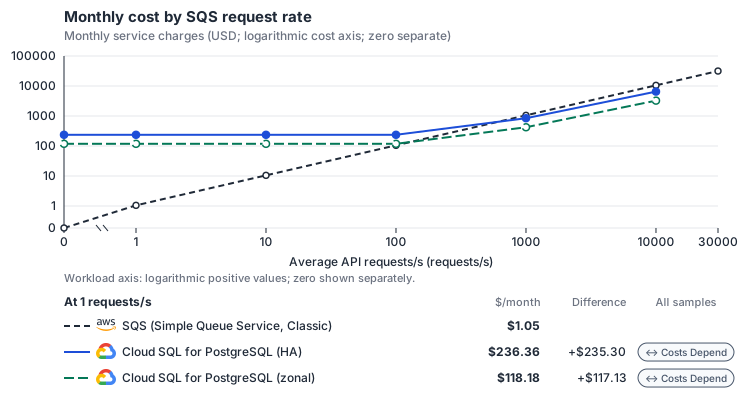
- 1 KiB messages; unbatched send, receive and delete requests in a 1:1:1 mix, with no empty receives or redeliveries. 730 hours/month; one billing unit per API request. Requested minima are 2 vCPU, 8 GiB memory and 100 GiB SSD, fully allocated. A versioned planning policy grows CPU, RAM and disk using 2x peak load, 70% utilization and explicit resident-data assumptions; it is not benchmark calibrated. Above the modeled configuration range, target price and savings are unavailable.
- Monthly AWS source usage in us-east-1, priced at the 2026-10-18 reference list rates before free allowances, discounts, credits and tax; not the uploaded invoice total. Rates as of 2026-10-18: us-east-1 → us-central1, USD/month.
- Source prices are reference charges, not an invoice. Target lines cover selected service usage/configuration only; adapter hosting and Tensor9 fees are excluded.
- Samples of explicit prices are not performance measurements or capacity qualification. No interpolation or break-even guarantee is implied.
- Variant assumptions show the first axis sample; any axis-dependent configuration is described by this curve’s workload note.
- 730 running hours per modeled month. Dedicated database compute and disk cost money even with zero origin traffic.
- Shared database allocation is a caller assumption. Do not sum a full database charge for every adapter sharing that database.
- Estimated allocation from planning assumptions; not benchmark calibrated. CPU, RAM and provisioned disk grow with the inferred workload and explicit peak/backlog assumptions.
- Average API requests, 64-KiB billing units, original messages and complete lifecycle work are distinct. One unbatched send/receive/delete cycle is one lifecycle, not three TPS.
- CPU tiers stop at 96 primary vCPUs; unsupported demand retains source cost but has no target cost, adapted total or savings. No sharding is inferred.
- Actual throughput, latency, connection limits, disk IOPS, claim contention, WAL and vacuum remain unqualified until comparable sustained benchmark samples exist.
- 150 full lifecycle equivalents per primary vCPU-second for a 1 KiB reference message (send, receive/claim and delete). Default 150 is a measured-by-tensor9 lower bound, not benchmark calibrated capacity: k6 offered 300 lifecycles/s to the SQS adapter on Cloud SQL db-custom-2-7680 (2 vCPU, PostgreSQL 16, us-west1) with short timestamp bodies and 299.93/s completed (src/main/kotlin/t9/prime/equiv/generated/eval/CloudsqlK6RoundtripR300T8K6V1_0_0.kt); database CPU was not recorded. These are modeled work units, not measured SQL transactions/s.
- Mean work uses original message arrivals × (2 + deliveries/message + 0.1 × empty receives/message) / 3, then scales by max(1, message bytes / 1024). Source batch fill was already used to infer original messages and is not applied again.
- Peak work is mean work × 2. Required primary CPU divides peak work by 150 lifecycle equivalents/vCPU-second × 0.7 target utilization.
- Resident data uses peak original arrivals × 60 residence seconds × 1024 message bytes × 3 physical storage multiplier. One binary GiB is 1073741824 bytes.
- Provisioned disk rounds (resident GiB + 20 GiB reserve) / 0.7 target disk utilization upward to whole GiB, retaining the caller minimum. Memory is the maximum of caller minimum, CPU × 4 GiB/vCPU and 0.1 of resident data, with a 0.9 GiB/vCPU floor and quarter-GiB upward rounding.
- CPU choices are 2, 4, 8, 16, 32, 64 and 96 primary vCPUs. CPU and memory promote jointly, with at most 6.5 GiB/vCPU, 624 GiB RAM and 65536 GiB disk.
- HA changes standby pricing and does not double primary throughput. Shared allocation changes the assigned cost and does not reduce required capacity.
- No benchmark sample calibrates this policy. Latency, IOPS, polling contention, WAL, vacuum and actual throughput require qualification. Demand beyond the listed configuration bounds is unpriced; this policy does not clamp, automatically shard or extrapolate capacity.
- Source usage is priced at reference rates; source lines are not actual invoice charges. Free or discounted usage still consumes target resources.
- AWS Standard SQS pricing: https://aws.amazon.com/sqs/pricing/
- Cloud SQL Enterprise PostgreSQL pricing: https://cloud.google.com/sql/pricing/
- Cloud SQL for PostgreSQL instance resource settings: https://docs.cloud.google.com/sql/docs/postgres/instance-settings
- Free allowances, negotiated discounts, credits, tax and one-time migration charges.
- Charges not listed in the breakdown, including additional network transfer, backups and encryption/KMS.
- Application compute changes, operational labor and portfolio-wide sharing or deduplication of infrastructure.
- SQS FIFO and fair queues; actual throughput/latency and resident-data behavior beyond the explicit planning assumptions.
sqs-cloudsql / 2026-10-18.4. Curve: request-rate.
Sources: AWS Standard SQS pricing, Cloud SQL Enterprise PostgreSQL pricing, Cloud SQL for PostgreSQL instance resource settings.
SQS → Cloud SQL planned scale-point benchmark
This is a benchmark plan, with historical reference observations retained separately. Planned cases are not completed measurements. The observations below do not calibrate the estimated allocation policy. Plan:sqs-cloudsql-scale-v1. Model: sqs-cloudsql. Workload: 1 KiB unbatched SQS send/receive/delete message cycles (sqs-1kib-unbatched-cycle).
dbEngineVersion, adapterVcpus, adapterMemoryGiB, adapterReplicas, loadGeneratorVcpus, loadGeneratorMemoryGiB, connectionPoolSize.
- cloudsql-zonal-2vcpu unresolved:
adapterVcpus,adapterMemoryGiB,adapterReplicas,loadGeneratorVcpus,loadGeneratorMemoryGiB,connectionPoolSize. - cloudsql-zonal-4vcpu unresolved:
adapterVcpus,adapterMemoryGiB,adapterReplicas,loadGeneratorVcpus,loadGeneratorMemoryGiB,connectionPoolSize. - cloudsql-zonal-8vcpu unresolved:
adapterVcpus,adapterMemoryGiB,adapterReplicas,loadGeneratorVcpus,loadGeneratorMemoryGiB,connectionPoolSize. - cloudsql-zonal-16vcpu unresolved:
adapterVcpus,adapterMemoryGiB,adapterReplicas,loadGeneratorVcpus,loadGeneratorMemoryGiB,connectionPoolSize.
-
historical-k6-roundtrip-r300-t8-1-0-0: source
src/main/kotlin/t9/prime/equiv/generated/eval/CloudsqlK6RoundtripR300T8K6V1_0_0.kt; case unmatched historical observation. Payload unknown bytes; batch fill send/receive/delete unknown/unknown/unknown; queues unknown; concurrency unknown. Operation mix: unknown. Latency scope: historical e2e metric; full send-through-delete timing is not established. Completed cycles unknown; error rate unknown; backlog start/end unknown/unknown; CPU/memory utilization unknown/unknown; p50/p99 24/140 ms; coordinated-omission correction true. The original generated EvalMeasurement is authoritative; metrics are projected from it without independently restating measured values. Tool-reported throughput does not identify offered, produced and sustained completed-message-cycle rates separately. Payload size, batch mix, queue count, concurrency, duration, completed count, errors, backlog, CPU/memory observations and HA are not established by this record. k6/Locust scripts used timestamp-string bodies rather than an exact 1 KiB payload; the OMB payload is also not established here. The source records storage as GB PD_SSD; tier memory is derived from db-custom MiB. Raw tuning is retained alongside the normalized allocation. -
historical-locust-roundtrip-t8-1-0-0: source
src/main/kotlin/t9/prime/equiv/generated/eval/CloudsqlLocustRoundtripT8LocustV1_0_0.kt; case unmatched historical observation. Payload unknown bytes; batch fill send/receive/delete unknown/unknown/unknown; queues unknown; concurrency unknown. Operation mix: unknown. Latency scope: historical e2e metric; full send-through-delete timing is not established. Completed cycles unknown; error rate unknown; backlog start/end unknown/unknown; CPU/memory utilization unknown/unknown; p50/p99 24/35 ms; coordinated-omission correction false. The original generated EvalMeasurement is authoritative; metrics are projected from it without independently restating measured values. Tool-reported throughput does not identify offered, produced and sustained completed-message-cycle rates separately. Payload size, batch mix, queue count, concurrency, duration, completed count, errors, backlog, CPU/memory observations and HA are not established by this record. k6/Locust scripts used timestamp-string bodies rather than an exact 1 KiB payload; the OMB payload is also not established here. The source records storage as GB PD_SSD; tier memory is derived from db-custom MiB. Raw tuning is retained alongside the normalized allocation. -
historical-omb-roundtrip-t2-1-0-0: source
src/main/kotlin/t9/prime/equiv/generated/eval/CloudsqlOmbRoundtripT2OmbV1_0_0.kt; case unmatched historical observation. Payload unknown bytes; batch fill send/receive/delete unknown/unknown/unknown; queues unknown; concurrency unknown. Operation mix: unknown. Latency scope: historical e2e metric; full send-through-delete timing is not established. Completed cycles unknown; error rate unknown; backlog start/end unknown/unknown; CPU/memory utilization unknown/unknown; p50/p99 13/83 ms; coordinated-omission correction true. The original generated EvalMeasurement is authoritative; metrics are projected from it without independently restating measured values. Tool-reported throughput does not identify offered, produced and sustained completed-message-cycle rates separately. Payload size, batch mix, queue count, concurrency, duration, completed count, errors, backlog, CPU/memory observations and HA are not established by this record. k6/Locust scripts used timestamp-string bodies rather than an exact 1 KiB payload; the OMB payload is also not established here. The source records storage as GB PD_SSD; tier memory is derived from db-custom MiB. Raw tuning is retained alongside the normalized allocation. - The 16 cases are planned experiments, each requiring three independent repetitions. No planned case has measured samples yet.
- Pin an adapter version before running a case. Completed-message-cycle throughput, p99 cycle latency, errors and backlog must be measured over 300 seconds after 60 seconds of warmup.
- Acceptance is authored: sustained completed cycles meet the offered rate, p99 ≤ 200 ms, error rate ≤ 0.001 and no backlog growth. This is not measured capacity evidence.
- Tail-latency qualification requires coordinated-omission-corrected measurements under the offered-load workload; correction alone never establishes completion or capacity.
- Historical k6, Locust and OMB observations are different workloads/tools at the same 2-vCPU allocation in us-west1. They are not hardware scaling points and are not averaged.
- Historical observations lack exact payload, HA, duration, completed-cycle counts, error/backlog and resource observations; none qualifies the sizing policy.
- The k6 observation completed its offered 300 cycles/s on 2 vCPU, so the sizing default of 150 lifecycles per vCPU-second is a lower bound. The planned cases must also record database CPU before a measured capacity can replace it.
- Adapter, load-generator and connection-pool allocations must be recorded before a case can qualify. Empty planned environment values are unresolved requirements, not defaults.
- Free allowances, negotiated discounts, credits, tax and one-time migration charges.
- Charges not listed in the breakdown, including additional network transfer, backups and encryption/KMS.
- Application compute changes, operational labor and portfolio-wide sharing or deduplication of infrastructure.
- SQS FIFO and fair queues; actual throughput/latency and resident-data behavior beyond the explicit planning assumptions.
- Inferred original messages: 100,000,000 messages/month.
- Estimated mean lifecycle-equivalent work: 38.05 1-KiB lifecycles/second.
- Estimated peak lifecycle-equivalent work: 76.1 1-KiB lifecycles/second.
- Estimated resident physical queue data: 0.0131 GiB.
- 730 running hours per modeled month. Dedicated database compute and disk cost money even with zero origin traffic.
- Shared database allocation is a caller assumption. Do not sum a full database charge for every adapter sharing that database.
- Estimated allocation from planning assumptions; not benchmark calibrated. CPU, RAM and provisioned disk grow with the inferred workload and explicit peak/backlog assumptions.
- Average API requests, 64-KiB billing units, original messages and complete lifecycle work are distinct. One unbatched send/receive/delete cycle is one lifecycle, not three TPS.
- CPU tiers stop at 96 primary vCPUs; unsupported demand retains source cost but has no target cost, adapted total or savings. No sharding is inferred.
- Actual throughput, latency, connection limits, disk IOPS, claim contention, WAL and vacuum remain unqualified until comparable sustained benchmark samples exist.
- 150 full lifecycle equivalents per primary vCPU-second for a 1 KiB reference message (send, receive/claim and delete). Default 150 is a measured-by-tensor9 lower bound, not benchmark calibrated capacity: k6 offered 300 lifecycles/s to the SQS adapter on Cloud SQL db-custom-2-7680 (2 vCPU, PostgreSQL 16, us-west1) with short timestamp bodies and 299.93/s completed (src/main/kotlin/t9/prime/equiv/generated/eval/CloudsqlK6RoundtripR300T8K6V1_0_0.kt); database CPU was not recorded. These are modeled work units, not measured SQL transactions/s.
- Mean work uses original message arrivals × (2 + deliveries/message + 0.1 × empty receives/message) / 3, then scales by max(1, message bytes / 1024). Source batch fill was already used to infer original messages and is not applied again.
- Peak work is mean work × 2. Required primary CPU divides peak work by 150 lifecycle equivalents/vCPU-second × 0.7 target utilization.
- Resident data uses peak original arrivals × 60 residence seconds × 1024 message bytes × 3 physical storage multiplier. One binary GiB is 1073741824 bytes.
- Provisioned disk rounds (resident GiB + 20 GiB reserve) / 0.7 target disk utilization upward to whole GiB, retaining the caller minimum. Memory is the maximum of caller minimum, CPU × 4 GiB/vCPU and 0.1 of resident data, with a 0.9 GiB/vCPU floor and quarter-GiB upward rounding.
- CPU choices are 2, 4, 8, 16, 32, 64 and 96 primary vCPUs. CPU and memory promote jointly, with at most 6.5 GiB/vCPU, 624 GiB RAM and 65536 GiB disk.
- HA changes standby pricing and does not double primary throughput. Shared allocation changes the assigned cost and does not reduce required capacity.
- No benchmark sample calibrates this policy. Latency, IOPS, polling contention, WAL, vacuum and actual throughput require qualification. Demand beyond the listed configuration bounds is unpriced; this policy does not clamp, automatically shard or extrapolate capacity.
sqs-cloudsql / 2026-10-18.4. Scenario: sqs-cloudsql-reference.
Sources: AWS Standard SQS pricing, Cloud SQL Enterprise PostgreSQL pricing, Cloud SQL for PostgreSQL instance resource settings.
On Azure, OCI, and Private Kubernetes
Via PostgreSQL
PostgreSQL hosting
Tensor9 operates CloudNativePG inside the customer’s Kubernetes cluster. Queue data is stored on that cluster’s volumes and does not survive a full cluster rebuild. Plan recovery and message cutover before replacing the cluster. Tensor9 operates the queue schema and adapter. Queues start empty; existing SQS messages are not migrated. Drain the source or coordinate dual writes before cutover.Queue behavior
Queues use the same PostgreSQL tables, receive steps, stored receipt handles and single-transaction dead-letter moves described in PostgreSQL queue behavior. Receipt handles survive adapter restarts; stale receipt handles return an error. Retention still removes messages in flight. All queues share database capacity, so a busy queue can affect others. The documented Standard-queue benchmark does not establish this host’s capacity or FIFO throughput. Delivery is at least once with best-effort ordering. SQS FIFO queues, with group ordering and deduplication, are not available today.Example monthly charges
This Tensor9 BYOC scenario estimates service charges for the named origin and target services. Adapter hosting and commercial Tensor9 fees need separate allocations. How Tensor9 estimates costs explains the method and what the estimates include.SQS Standard · SQS request billing units
Feature: SQS Standard. Estimated monthly service charges by SQS request billing units. Adapter hosting and Tensor9 fees are excluded. Source: us-east-1; target: us-central1; currency: USD.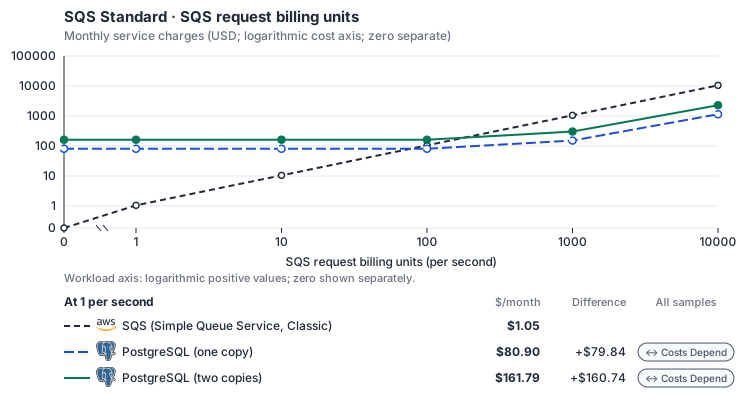
- 1-KiB messages, unbatched send/receive/delete; actual batch and delivery assumptions stay visible. Other native meters and workload assumptions retain their explicitly displayed default quantities. Workload translation and capacity assumptions are not benchmark measurements.
- Native monthly usage priced at the cited provider list prices; listed target allowances apply where present, excluding invoice credits, taxes and negotiated discounts. Rates as of 2026-10-22: us-east-1 → us-central1, USD/month.
- Source prices are reference charges, not an invoice. Target lines cover selected service usage/configuration only; adapter hosting and Tensor9 fees are excluded.
- Samples of explicit prices are not performance measurements or capacity qualification. No interpolation or break-even guarantee is implied.
- Variant assumptions show the first axis sample; any axis-dependent configuration is described by this curve’s workload note.
- Rates are cited provider list prices, editable for discounts, commitments or another region. Workload translation and capacity coefficients remain editable planning assumptions, not benchmark measurements or a commercial quote.
- Default-zero rates are explicit assumptions, not evidence that the deployed service or resource is free.
- Provisioned-unit minimums use an editable approximate allocation floor. Modeled target service cost is max(usage/allocation, minimum), with billable network, durable staging and dependent sinks added separately; actual RU/TU sizing, scaling increments and throughput remain unqualified.
- Durable staging is priced once: provisioned targets include adapter state in their selected allocation; native targets add a separate staging allocation when required. Adapter hosting is a separate allocation and must exclude resources already priced as staging, workers or target capacity.
- A declared adapter mapping and cost model do not establish implementation availability or service equivalence.
- This is a declared directed mapping; a planning estimate does not establish deployment or request-serving support.
- Authored planning assumptions, not measured adapter capacity. Origin rates are cited first-tier list prices, before free allowances and discounts.
- A cost scenario does not establish backend availability, protocol fidelity or production readiness. Registry serving status remains independent.
- Storage follows resident original messages, not every monthly message. Broker delivery bytes include redeliveries.
- FIFO estimates do not qualify dedup support, group throughput or single-group latency; backend limitations remain applicable.
- Self-hosted target: PostgreSQL (PostgreSQL License, https://www.postgresql.org/about/licence/). Selected CPU, RAM and physical disk allocation grow with workload; no per-operation price is assumed. No vendor charge: the target runs on the customer’s Kubernetes nodes, so CPU, RAM and disk bill at the Kubernetes node reference rates, Compute Engine N2 in us-central1 (USD 0.031611/vCPU-hour, 0.004237/GiB-hour) with pd-balanced disk (0.10/GiB-month) and Premium Tier egress. The cost-optimized E2 series lists 0.02181159/vCPU-hour and 0.00292353/GiB-hour; AWS m6i/r6i and Azure D2s v5/E2s v5 both decompose to 0.033/vCPU-hour and 0.00375/GiB-hour. Requested CPU and RAM are billed; node bin-packing waste, system reservations and the cluster control-plane fee are not.
- Row-store throughput (capacityOpsPerVcpuSecond, default 1500) is measured-by-tensor9 as a lower bound: the DynamoDB adapter on Cloud SQL db-custom-2-7680 (2 vCPU, PostgreSQL 16, us-west1) served 2,974 ops/s of YCSB-A at 16 threads without recorded saturation (src/main/kotlin/t9/prime/equiv/generated/eval/CloudsqlPostgresqlYcsbAT16GoYcsbV1_0_0.kt). Published CPU-bound pgbench reaches 3,101 read-write transactions and 20,289 point reads per vCPU-second (AWS z1d.2xlarge, PostgreSQL 14.5), so actual capacity is likely higher. Reads and writes share one coefficient: at the same adapter version, read-only YCSB-C was not faster than 50%-update YCSB-A.
- Log-broker throughput (capacityStreamMiBPerVcpuSecond 20 at 0.5 utilization, 4 GiB RAM per vCPU) is provider-documented by Google Managed Service for Apache Kafka sizing (https://docs.cloud.google.com/managed-service-for-apache-kafka/docs/plan-cluster-size): write-equivalent bytes are replicated writes plus a quarter of reads. Producer batches below 10 KB lower per-CPU throughput; that penalty is not modeled.
- Disk utilization 0.8 is provider-documented headroom below Cloud SQL automatic storage increase, which triggers near 91-95% full (https://docs.cloud.google.com/sql/docs/postgres/instance-settings). The 20 GiB reserve exceeds PostgreSQL’s 1 GB default max_wal_size; the remainder of that reserve is unmeasured.
- CPU tiers double from 2 vCPUs to the target’s largest node at 4 GiB per vCPU; each target’s documented largest node bounds CPU, RAM, RAM per vCPU and disk, and the durable staging database uses Cloud SQL Enterprise (96 vCPU, 6.5 GiB per vCPU, 624 GiB, 64 TiB). Targets billed per capacity unit or throughput unit are sized by their backend instead.
- No public evidence: peak/mean work (2) and the RAM working-set fraction (0.1). Proposed measurements: the p99 one-minute rate over the monthly mean from customer CloudWatch metrics; the buffer hit ratio while stepping RAM under a fixed YCSB-B load.
- Node bounds: Compute Engine n2-highmem-128 has 128 vCPUs and 864 GB (https://docs.cloud.google.com/compute/docs/general-purpose-machines); a Persistent Disk volume holds up to 64 TiB (https://docs.cloud.google.com/compute/docs/disks/persistent-disks).
- Stored GiB already includes the origin family’s physical footprint assumptions; no second storage amplification is applied.
- The operations/vCPU coefficient supplies the compute requirement alongside explicit resource-hour minima.
- Copies and allocation fractions change cost only; they do not increase modeled primary capacity.
- AWS Price List API, AWSQueueService offer: https://pricing.us-east-1.amazonaws.com/offers/v1.0/aws/AWSQueueService/current/us-east-1/index.json
- Compute Engine general-purpose machine pricing: https://cloud.google.com/products/compute/pricing/general-purpose
- Disk and image pricing: https://cloud.google.com/compute/disks-image-pricing
- Network pricing: https://cloud.google.com/vpc/network-pricing
- Additional network transfer, backups, KMS, one-time migration and operational labor unless an explicit meter includes them.
- Destination application execution and separately billed downstream services; supply those allocations separately.
- Taxes, discounts, credits and free-tier allowances not explicitly listed by this model.
- Unmodeled dependent services, task execution and operations outside the selected workload family.
plan-a5003d6d1b075ed4d7688651bd5e72c32088cf9c / 2026-10-22.planning.2. Curve: workload-1.
Sources: AWS Price List API, AWSQueueService offer, Compute Engine general-purpose machine pricing, Disk and image pricing, Network pricing.
SQS Standard → PostgreSQL: Authored native-usage planning example. Native monthly usage priced at the cited provider list prices; listed target allowances apply where present, excluding invoice credits, taxes and negotiated discounts.
Scenario source region: us-east-1. Scenario target region: us-central1. Currency: USD.
- Additional network transfer, backups, KMS, one-time migration and operational labor unless an explicit meter includes them.
- Destination application execution and separately billed downstream services; supply those allocations separately.
- Taxes, discounts, credits and free-tier allowances not explicitly listed by this model.
- Unmodeled dependent services, task execution and operations outside the selected workload family.
- Translated reads: 0 operations.
- Translated writes: 0 operations.
- Translated resident physical data: 0 GiB-month.
- Native provider operations: 0 operations.
- Published payload: 0 GiB.
- Delivered payload: 0 GiB.
- Allocated execution CPU: 0 vCPU-hour.
- Allocated execution RAM: 0 GiB-hour.
- Independent resource allocation: 0 resource-hour.
- Independent inventory: 0 resource-month.
- Input tokens: 0 tokens.
- Output tokens: 0 tokens.
- Billable network: 0 GiB.
- Dependent object sink retained data: 0 GiB-month.
- Dependent object sink writes: 0 writes.
- Rates are cited provider list prices, editable for discounts, commitments or another region. Workload translation and capacity coefficients remain editable planning assumptions, not benchmark measurements or a commercial quote.
- Default-zero rates are explicit assumptions, not evidence that the deployed service or resource is free.
- Provisioned-unit minimums use an editable approximate allocation floor. Modeled target service cost is max(usage/allocation, minimum), with billable network, durable staging and dependent sinks added separately; actual RU/TU sizing, scaling increments and throughput remain unqualified.
- Durable staging is priced once: provisioned targets include adapter state in their selected allocation; native targets add a separate staging allocation when required. Adapter hosting is a separate allocation and must exclude resources already priced as staging, workers or target capacity.
- A declared adapter mapping and cost model do not establish implementation availability or service equivalence.
- This is a declared directed mapping; a planning estimate does not establish deployment or request-serving support.
- Authored planning assumptions, not measured adapter capacity. Origin rates are cited first-tier list prices, before free allowances and discounts.
- A cost scenario does not establish backend availability, protocol fidelity or production readiness. Registry serving status remains independent.
- Storage follows resident original messages, not every monthly message. Broker delivery bytes include redeliveries.
- FIFO estimates do not qualify dedup support, group throughput or single-group latency; backend limitations remain applicable.
- Self-hosted target: PostgreSQL (PostgreSQL License, https://www.postgresql.org/about/licence/). Selected CPU, RAM and physical disk allocation grow with workload; no per-operation price is assumed. No vendor charge: the target runs on the customer’s Kubernetes nodes, so CPU, RAM and disk bill at the Kubernetes node reference rates, Compute Engine N2 in us-central1 (USD 0.031611/vCPU-hour, 0.004237/GiB-hour) with pd-balanced disk (0.10/GiB-month) and Premium Tier egress. The cost-optimized E2 series lists 0.02181159/vCPU-hour and 0.00292353/GiB-hour; AWS m6i/r6i and Azure D2s v5/E2s v5 both decompose to 0.033/vCPU-hour and 0.00375/GiB-hour. Requested CPU and RAM are billed; node bin-packing waste, system reservations and the cluster control-plane fee are not.
- Row-store throughput (capacityOpsPerVcpuSecond, default 1500) is measured-by-tensor9 as a lower bound: the DynamoDB adapter on Cloud SQL db-custom-2-7680 (2 vCPU, PostgreSQL 16, us-west1) served 2,974 ops/s of YCSB-A at 16 threads without recorded saturation (src/main/kotlin/t9/prime/equiv/generated/eval/CloudsqlPostgresqlYcsbAT16GoYcsbV1_0_0.kt). Published CPU-bound pgbench reaches 3,101 read-write transactions and 20,289 point reads per vCPU-second (AWS z1d.2xlarge, PostgreSQL 14.5), so actual capacity is likely higher. Reads and writes share one coefficient: at the same adapter version, read-only YCSB-C was not faster than 50%-update YCSB-A.
- Log-broker throughput (capacityStreamMiBPerVcpuSecond 20 at 0.5 utilization, 4 GiB RAM per vCPU) is provider-documented by Google Managed Service for Apache Kafka sizing (https://docs.cloud.google.com/managed-service-for-apache-kafka/docs/plan-cluster-size): write-equivalent bytes are replicated writes plus a quarter of reads. Producer batches below 10 KB lower per-CPU throughput; that penalty is not modeled.
- Disk utilization 0.8 is provider-documented headroom below Cloud SQL automatic storage increase, which triggers near 91-95% full (https://docs.cloud.google.com/sql/docs/postgres/instance-settings). The 20 GiB reserve exceeds PostgreSQL’s 1 GB default max_wal_size; the remainder of that reserve is unmeasured.
- CPU tiers double from 2 vCPUs to the target’s largest node at 4 GiB per vCPU; each target’s documented largest node bounds CPU, RAM, RAM per vCPU and disk, and the durable staging database uses Cloud SQL Enterprise (96 vCPU, 6.5 GiB per vCPU, 624 GiB, 64 TiB). Targets billed per capacity unit or throughput unit are sized by their backend instead.
- No public evidence: peak/mean work (2) and the RAM working-set fraction (0.1). Proposed measurements: the p99 one-minute rate over the monthly mean from customer CloudWatch metrics; the buffer hit ratio while stepping RAM under a fixed YCSB-B load.
- Node bounds: Compute Engine n2-highmem-128 has 128 vCPUs and 864 GB (https://docs.cloud.google.com/compute/docs/general-purpose-machines); a Persistent Disk volume holds up to 64 TiB (https://docs.cloud.google.com/compute/docs/disks/persistent-disks).
- Stored GiB already includes the origin family’s physical footprint assumptions; no second storage amplification is applied.
- The operations/vCPU coefficient supplies the compute requirement alongside explicit resource-hour minima.
- Copies and allocation fractions change cost only; they do not increase modeled primary capacity.
plan-a5003d6d1b075ed4d7688651bd5e72c32088cf9c / 2026-10-22.planning.2. Scenario: planning-example.
Sources: AWS Price List API, AWSQueueService offer, Compute Engine general-purpose machine pricing, Disk and image pricing, Network pricing.
On Azure
Via Azure Queue Storage
How it works
Tensor9 adds an adapter process to your application pod and setsAWS_ENDPOINT_URL_SQS to its local address. Your application keeps its SendMessage and ReceiveMessage calls. The adapter turns them into Queue Storage operations and returns SQS responses, error codes and MD5 checksums.
Each declared standard SQS queue becomes a Queue Storage queue in one storage account. Receipt handles and receive counts come from Queue Storage’s pop receipt (pop_receipt) and dequeue count. Each message body is base64-encoded, with its attributes in a small JSON wrapper when present. Queue Storage’s size limit leaves roughly 48 KiB for the payload, and your application must handle dead-letter delivery itself. FIFO queues are mapped to Service Bus instead.


Your application keeps its SQS SDK. The adapter turns its calls into Azure Queue Storage operations.
Architecture
The adapter deletes messages and changes their visibility with Queue Storage’spop_receipt, which stays valid across calls. A receipt handle still works after an adapter restart, and you can run more adapter instances without any shared coordination between them. The adapter signs in with the customer’s AKS Workload Identity, which supplies a token through the cluster webhook, so no account key is stored. Microsoft operates Queue Storage’s durability, backups and high availability; Tensor9 operates the adapter.
Terraform creates one storage account and one queue per declared SQS queue. Azure queue names must be lowercase, so the Azure name is derived from the SQS name: characters outside a-z, 0-9 and hyphen become hyphens, and names over 63 characters are shortened with a hash suffix. A name shorter than three characters after that change is rejected. Each queue message holds the base64-encoded body and, when supplied, a JSON wrapper with MessageAttributes.
- Queue Storage keeps message state. Receipt handles stay valid across adapter restarts, with no extra worker to renew locks or enforce retention.
- One storage account, one queue per declared SQS queue, no keys. Access uses the customer’s AKS Workload Identity.


Queue Storage keeps the messages, receipt tokens, receive counts and visibility times. The adapter keeps no message data of its own.
Receiving messages
AReceiveMessage is a long poll of at most 20 seconds, the SQS maximum for WaitTimeSeconds. Queue Storage has no long polling of its own, so the adapter checks the queue once straight away and then about every 300 ms while it is empty, until the wait time runs out. The 300 ms is a fixed check interval, not a latency figure. Each check takes up to 10 messages: Queue Storage would return up to 32, but the SQS limit of 10 applies.
The visibility timeout you pass on a receive is used as given, except that zero becomes one second. SQS’s 12-hour maximum is well under Queue Storage’s 7-day ceiling, so no value is cut short.
The adapter builds the SQS receipt handle from each message’s pop_receipt and sets ApproximateReceiveCount from its dequeue count, which starts at 1 and goes up on each redelivery. It decodes the body and attributes and recomputes their MD5 checksums. Delivery is at least once, with best-effort ordering. DelaySeconds keeps a new message hidden for that long. Use Azure monitoring for measured receive latency and throughput.


A receive is a long poll that returns Queue Storage’s own pop_receipt ; there is no lock to renew. ApproximateReceiveCount is Queue Storage’s dequeue count, starting at 1.
Receipt handles & visibility
A receipt handle holds the queue name, the message ID and thepop_receipt, encoded with a qs1: prefix. Queue Storage accepts the pop receipt from any connection or process, so deletes and visibility changes still work after an adapter restart. An outdated receipt handle, from a message already deleted or received again, makes delete or visibility change succeed without doing anything, as on SQS. A malformed handle, or one for another queue, returns ReceiptHandleIsInvalid.
Native Queue Storage sets visibility per message and has no queue-level default. At the Max tier, the adapter stores the SQS queue’s default visibility timeout and applies it when ReceiveMessage does not set one. ChangeMessageVisibility sets the message’s next visible time; zero makes it visible to other consumers at once. The full SQS range up to 12 hours fits under Queue Storage’s 7-day ceiling, so no value is cut short. If another consumer has received the message again in the meantime, the earlier receipt handle is outdated and the change does nothing, so it cannot disturb the other consumer.


Queue Storage accepts its pop_receipt across adapter restarts. SQS’s 12-hour visibility fits within Queue Storage’s 7-day ceiling.
Payload size and dead-letter delivery
Queue Storage message text must be safe for XML and UTF-8, so the adapter base64-encodes each body. That makes it about a third larger, so Queue Storage’s 64 KiB limit leaves roughly 48 KiB for the payload, less when attributes are included. The adapter checks the encoded size, and a send that is too large returnsInvalidParameterValue with the size and the limit. For larger messages, use another backend, or store the body in Blob Storage and send its location.
Queue Storage does not move messages to a dead-letter queue. The adapter returns the dequeue count as ApproximateReceiveCount, and your application uses it to decide when to move a message to a separately provisioned <queue>-poison queue. Copying the message there and deleting the original are two separate operations, so plan for an interruption between them. The Cosmos DB and Service Bus backends do dead-letter delivery for you.


Base64 encoding leaves roughly 48 KiB for the payload. Queue Storage has no automatic dead-letter delivery; your application moves failed messages to a queue you provision.
Limitations
Where SQS and Queue Storage differ- FIFO queues are not supported. Queue Storage has no ordering, message groups or deduplication, so a
.fifoqueue is mapped to Service Bus when the stack is built. FIFO traffic that still reaches this backend, through a pre-declared queue or a hand-written URL, is rejected on send, receive, create and purge. - Message size behaves differently: roughly 48 KiB. Base64 encoding makes the body about a third larger, and attributes also count toward Queue Storage’s 64 KiB limit. A send that is too large returns
InvalidParameterValue. - You must move failed messages yourself. Use
ApproximateReceiveCountto decide when to copy a message to<queue>-poisonand delete the original. These are separate operations, so handle retries if one is interrupted. - Batch calls behave differently: one request per entry.
SendMessageBatch,DeleteMessageBatchandChangeMessageVisibilityBatchsend one request per entry and report each entry’s success or failure. - Queue-level delay and dead-letter routes are not supported. At Max, the adapter stores the queue’s visibility and retention defaults and applies them to each message. A nonzero queue-level delay or a dead-letter route is rejected, because this backend cannot apply them to a queue. Per-message delay still works.
- Retention behaves differently: it is set on each message. At Max, the adapter reads the queue’s declared
MessageRetentionPeriodand sends it as each message’smessage_time_to_live, within SQS’s range of 60 seconds to 14 days. Queue Storage’s own shorter lifetimes and-1(never expire) are not SQS retention values. Without it, Queue Storage keeps messages for 7 days. ADelaySecondsat or above the retention period would never become visible, so it is rejected. ApproximateFirstReceiveTimestampis not supported. Queue Storage does not record when a message was first received, so the attribute is left out rather than given a wrong value.SentTimestampcomes from Queue Storage’s insertion time, andApproximateReceiveCountfrom its dequeue count.- Message counts come from Queue Storage.
ApproximateNumberOfMessagesis Queue Storage’s own approximate message count. Use Azure monitoring for request volume and latency. - Queue management behaves differently at Max. Terraform creates the storage account and the initial queues. The Max queue catalog handles queue listings, tags and supported edits, and each change must pass the backend’s policy and message-size checks.
- You get one storage account. The adapter reaches a single storage account through AKS Workload Identity, with no keys.
Other considerations
- Moving from AWS. Your application, SQS SDK and queue declarations stay the same, but existing messages are not moved. New queues start empty, so drain the SQS queues or write to both during the transition.
- Who runs what. Microsoft operates Queue Storage’s durability, backup, replication and availability; Tensor9 operates the adapter. Your application moves failed messages to
<queue>-poisonusingApproximateReceiveCount. - Before going live. Durability is set on the storage account, not on each queue: every queue inherits the account’s redundancy (LRS, ZRS, GRS or GZRS). Pick the level your workload needs before you provision.
- Include idle polls in cost estimates. Queue Storage bills for transactions and stored capacity. A
ReceiveMessagelong poll checks for messages about every 300 ms, so an idle long poll makes several billable requests.
Example monthly charges
This Tensor9 BYOC scenario estimates service charges for the named origin and target services. Adapter hosting and commercial Tensor9 fees need separate allocations. How Tensor9 estimates costs explains the method and what the estimates include.SQS Standard · SQS request billing units
Feature: SQS Standard. Estimated monthly service charges by SQS request billing units. Adapter hosting and Tensor9 fees are excluded. Source: us-east-1; target: East US; currency: USD.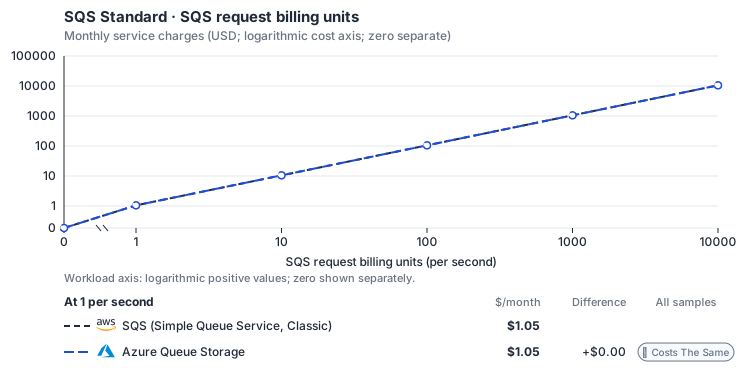
- 1-KiB messages, unbatched send/receive/delete; actual batch and delivery assumptions stay visible. Other native meters and workload assumptions retain their explicitly displayed default quantities. Workload translation and capacity assumptions are not benchmark measurements.
- Native monthly usage priced at the cited provider list prices; listed target allowances apply where present, excluding invoice credits, taxes and negotiated discounts. Rates as of 2026-10-22: us-east-1 → East US, USD/month.
- Source prices are reference charges, not an invoice. Target lines cover selected service usage/configuration only; adapter hosting and Tensor9 fees are excluded.
- Samples of explicit prices are not performance measurements or capacity qualification. No interpolation or break-even guarantee is implied.
- Variant assumptions show the first axis sample; any axis-dependent configuration is described by this curve’s workload note.
- Rates are cited provider list prices, editable for discounts, commitments or another region. Workload translation and capacity coefficients remain editable planning assumptions, not benchmark measurements or a commercial quote.
- Default-zero rates are explicit assumptions, not evidence that the deployed service or resource is free.
- Provisioned-unit minimums use an editable approximate allocation floor. Modeled target service cost is max(usage/allocation, minimum), with billable network, durable staging and dependent sinks added separately; actual RU/TU sizing, scaling increments and throughput remain unqualified.
- Durable staging is priced once: provisioned targets include adapter state in their selected allocation; native targets add a separate staging allocation when required. Adapter hosting is a separate allocation and must exclude resources already priced as staging, workers or target capacity.
- A declared adapter mapping and cost model do not establish implementation availability or service equivalence.
- This is a declared directed mapping; a planning estimate does not establish deployment or request-serving support.
- Authored planning assumptions, not measured adapter capacity. Origin rates are cited first-tier list prices, before free allowances and discounts.
- A cost scenario does not establish backend availability, protocol fidelity or production readiness. Registry serving status remains independent.
- Storage follows resident original messages, not every monthly message. Broker delivery bytes include redeliveries.
- FIFO estimates do not qualify dedup support, group throughput or single-group latency; backend limitations remain applicable.
- Azure Queue Storage (general-purpose v2, Standard LRS) bills every REST operation and stored GB-months. Each managed operation is one queue call; a queue message is at most 64 KiB, so no size multiplier applies. GRS, ZRS and the legacy general-purpose v1 account price differently. Internet egress is billed by Azure networking, not the queue, and the mapped families select none.
- AWS Price List API, AWSQueueService offer: https://pricing.us-east-1.amazonaws.com/offers/v1.0/aws/AWSQueueService/current/us-east-1/index.json
- Azure Retail Prices API: https://prices.azure.com/api/retail/prices
- Additional network transfer, backups, KMS, one-time migration and operational labor unless an explicit meter includes them.
- Destination application execution and separately billed downstream services; supply those allocations separately.
- Taxes, discounts, credits and free-tier allowances not explicitly listed by this model.
- Unmodeled dependent services, task execution and operations outside the selected workload family.
plan-d5bf5eea867ef509a6394c8ab16664bacb37eb07 / 2026-10-22.planning.2. Curve: workload-1.
Sources: AWS Price List API, AWSQueueService offer, Azure Retail Prices API.
SQS Standard → Azure Queue Storage: Authored native-usage planning example. Native monthly usage priced at the cited provider list prices; listed target allowances apply where present, excluding invoice credits, taxes and negotiated discounts.
Scenario source region: us-east-1. Scenario target region: East US. Currency: USD.
- Additional network transfer, backups, KMS, one-time migration and operational labor unless an explicit meter includes them.
- Destination application execution and separately billed downstream services; supply those allocations separately.
- Taxes, discounts, credits and free-tier allowances not explicitly listed by this model.
- Unmodeled dependent services, task execution and operations outside the selected workload family.
- Translated reads: 0 operations.
- Translated writes: 0 operations.
- Translated resident physical data: 0 GiB-month.
- Native provider operations: 0 operations.
- Published payload: 0 GiB.
- Delivered payload: 0 GiB.
- Allocated execution CPU: 0 vCPU-hour.
- Allocated execution RAM: 0 GiB-hour.
- Independent resource allocation: 0 resource-hour.
- Independent inventory: 0 resource-month.
- Input tokens: 0 tokens.
- Output tokens: 0 tokens.
- Billable network: 0 GiB.
- Dependent object sink retained data: 0 GiB-month.
- Dependent object sink writes: 0 writes.
- Rates are cited provider list prices, editable for discounts, commitments or another region. Workload translation and capacity coefficients remain editable planning assumptions, not benchmark measurements or a commercial quote.
- Default-zero rates are explicit assumptions, not evidence that the deployed service or resource is free.
- Provisioned-unit minimums use an editable approximate allocation floor. Modeled target service cost is max(usage/allocation, minimum), with billable network, durable staging and dependent sinks added separately; actual RU/TU sizing, scaling increments and throughput remain unqualified.
- Durable staging is priced once: provisioned targets include adapter state in their selected allocation; native targets add a separate staging allocation when required. Adapter hosting is a separate allocation and must exclude resources already priced as staging, workers or target capacity.
- A declared adapter mapping and cost model do not establish implementation availability or service equivalence.
- This is a declared directed mapping; a planning estimate does not establish deployment or request-serving support.
- Authored planning assumptions, not measured adapter capacity. Origin rates are cited first-tier list prices, before free allowances and discounts.
- A cost scenario does not establish backend availability, protocol fidelity or production readiness. Registry serving status remains independent.
- Storage follows resident original messages, not every monthly message. Broker delivery bytes include redeliveries.
- FIFO estimates do not qualify dedup support, group throughput or single-group latency; backend limitations remain applicable.
- Azure Queue Storage (general-purpose v2, Standard LRS) bills every REST operation and stored GB-months. Each managed operation is one queue call; a queue message is at most 64 KiB, so no size multiplier applies. GRS, ZRS and the legacy general-purpose v1 account price differently. Internet egress is billed by Azure networking, not the queue, and the mapped families select none.
plan-d5bf5eea867ef509a6394c8ab16664bacb37eb07 / 2026-10-22.planning.2. Scenario: planning-example.
Sources: AWS Price List API, AWSQueueService offer, Azure Retail Prices API.
Via Azure Service Bus
How it works
Tensor9 adds an adapter process to your application pod and setsAWS_ENDPOINT_URL_SQS to its local address. Your application keeps its SendMessage and ReceiveMessage calls. The adapter performs them on Azure Service Bus and returns SQS responses, error codes and MD5 checksums.
Each standard queue maps to a Service Bus queue, reached over AMQP 1.0. SendMessage sends to that queue; SQS message attributes become application_properties, and DelaySeconds sets a scheduled delivery time. Receiving locks a message with PeekLock. Deleting completes the message, and changing visibility renews or abandons its lock. Delivery is at least once, with best-effort ordering and no deduplication, as on an SQS standard queue. FIFO queues use a separate mapping built on Service Bus sessions.


Your application keeps its SQS SDK; the adapter turns each call into Azure Service Bus operations.
Architecture
The adapter talks to Service Bus Standard over AMQP 1.0. It signs in with the customer’s AKS Workload Identity and theAzure Service Bus Data Owner role, so no secret is stored. That role allows sending and receiving messages, not creating or configuring queues.
In SQS, ReceiveMessage and DeleteMessage are separate calls linked by the receipt handle. In Service Bus, a message’s lock belongs to the receiver connection that took it, and only that receiver can complete, abandon or renew it. So the adapter keeps one long-lived PeekLock receiver per queue and remembers which receiver holds each receipt handle’s lock. Prefetch is off, so a message’s lock starts only when a consumer asks for it. While you hold a message, the adapter renews its lock for the visibility timeout you asked for, up to Service Bus’s 5-minute lock limit.
Creating a queue and setting its lock duration, dead-letter queue and retention are Azure Resource Manager operations, which the messaging role cannot perform. Tensor9 therefore creates the namespace and queue at deployment, with a 5-minute lock, a redelivery limit taken from your redrive policy, and automatic forwarding to your dead-letter queue. CreateQueue only checks that the queue is reachable, by opening a sender. The adapter never holds a credential that can change queue settings. Microsoft operates Service Bus durability, backup and availability; Tensor9 operates the adapter.


The adapter keeps each message’s lock on the receiver that took it until the message is deleted or the lock expires. The queue’s settings are fixed when it is created.
Receiving messages
ReceiveMessage receives and locks messages with PeekLock. MaxNumberOfMessages is clamped to 1–10 and WaitTimeSeconds to 20 seconds, which becomes Service Bus’s maximum wait. A standard queue has no session to accept first, so an empty queue returns within that wait. For each message, the adapter returns a receipt handle and remembers which receiver holds the lock; deletes and visibility changes go through that same receiver.
Standard queues allow duplicates and provide best-effort ordering. ApproximateReceiveCount uses Service Bus’s delivery_count, starting at 1 and increasing on each redelivery; this count also determines when a failing message is dead-lettered. The adapter recomputes MD5 checksums and reads SentTimestamp from the enqueue time. DelaySeconds schedules delivery up to 900 seconds; larger values return InvalidParameterValue. Batch sends process entries individually and return each entry’s result, including separately scheduled delays.


A receive locks up to ten messages within your long-poll wait. ApproximateReceiveCount is Service Bus’s real delivery_count .
Receipt handles & visibility
A receipt handle has the formsb1 | queue | lock-token. The adapter keeps it paired with the Service Bus receiver that holds the lock, in memory, between ReceiveMessage and the later delete or visibility change.
Receipt handles become invalid when the adapter restarts. A restart drops the receivers and that pairing. A later delete or visibility change with an old handle returns ReceiptHandleIsInvalid. The message stays in Service Bus and becomes available again when its lock expires, within 5 minutes.
A visibility timeout cannot exceed 5 minutes. Service Bus locks last at most 5 minutes, so a longer value on ReceiveMessage or ChangeMessageVisibility returns AWS.SimpleQueueService.UnsupportedOperation (HTTP 501) instead of being shortened, and a queue declared with a longer VisibilityTimeout is rejected. A positive ChangeMessageVisibility renews the lock; zero abandons the message for immediate redelivery. The adapter keeps renewing the lock for the window you asked for.


Receipt handles become invalid after an adapter restart. A visibility timeout above 5 minutes returns an error.
Dead-letter & retention
Service Bus dead-letters a message when its delivery count reaches the queue’s limit, set frommaxReceiveCount. The adapter cannot receive from Service Bus’s built-in dead-letter subqueue, so the queue is created with automatic forwarding to your declared dead-letter queue (DLQ). Expired messages are dead-lettered too, and stay there for inspection or recovery.
Retention, lock duration and dead-letter forwarding are set through Azure Resource Manager when the queue is created, and the messaging role cannot read them. Tensor9 keeps a record of each queue’s declared settings and answers attribute reads from it; live message counts are not available over this connection. Messages in Service Bus are durable. Receivers, active locks and receipt-handle pairings live in the adapter process.


Service Bus forwards a message to your dead-letter queue after maxReceiveCount deliveries.
Limitations
Where SQS standard queues and Service Bus differ- Visibility timeouts longer than 5 minutes are not supported. A longer value returns
AWS.SimpleQueueService.UnsupportedOperationrather than being shortened, which could cause double processing. For long work, extend the timeout with repeatedChangeMessageVisibilitycalls. - Receipt handles behave differently: they become invalid when the adapter restarts. A later delete or visibility change returns
ReceiptHandleIsInvalid, and the message is delivered again after its lock expires, within 5 minutes. Cosmos DB and PostgreSQL handles stay valid across a restart. - Deduplication and strict ordering are not supported on standard queues. Delivery is at least once with best-effort order, as on SQS standard queues. For strict per-group order and duplicate detection, declare a
.fifoqueue, which uses Service Bus sessions (see the FIFO explainer). - Live message counts are not supported.
ApproximateNumberOfMessagesis omitted; attribute reads return the declared retention, visibility and dead-letter settings. Use Azure monitoring for live counts and request rates. - Queue management behaves differently. Tensor9 handles queue listings, tags and supported attribute changes.
CreateQueueonly checks that the queue created at deployment is reachable, andDeleteQueuedoes not delete it. Changing retention, a nonzero queue delay or a new dead-letter target needs a deployment change and is rejected. PurgeQueuebehaves differently. It receives and completes the currently visible messages in a bounded loop; locked and scheduled messages are left, and messages sent during the purge may or may not be removed. SQSPurgeQueuealso removes in-flight messages.
Other considerations
- Moving from AWS. The Service Bus queues start empty; messages still in SQS on AWS are not moved. Switch over once the SQS queue is drained, or send to both until it is.
- Who operates what. Microsoft operates Service Bus durability, replication and availability; Tensor9 operates the adapter. Include the adapter in your application’s monitoring.
- Before going live. Make sure consumers fit within the 5-minute visibility limit and handle
ReceiptHandleIsInvalidafter an adapter restart. Messages not completed stay in Service Bus and are delivered again after their locks expire; retention and dead-letter settings still apply. - Cost. Standard bills per messaging operation; Premium bills per provisioned messaging unit. Count receives, lock renewals and deletes.
Example monthly charges
This Tensor9 BYOC scenario estimates service charges for the named origin and target services. Adapter hosting and commercial Tensor9 fees need separate allocations. How Tensor9 estimates costs explains the method and what the estimates include.SQS Standard · SQS request billing units
Feature: SQS Standard. Estimated monthly service charges by SQS request billing units. Adapter hosting and Tensor9 fees are excluded. Source: us-east-1; target: East US; currency: USD.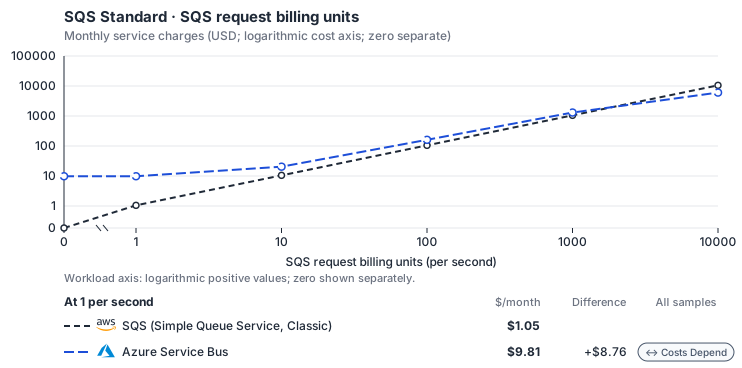
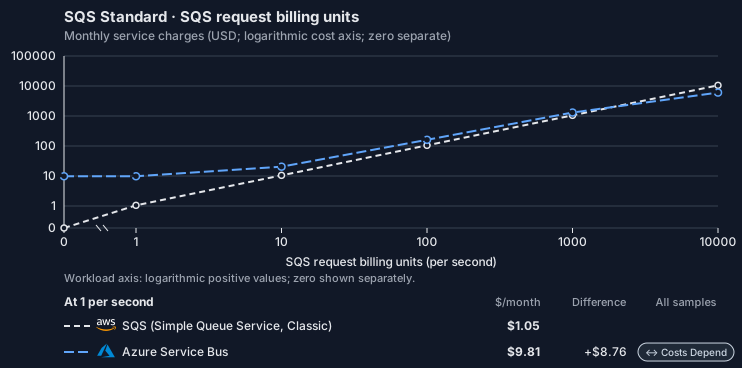
- 1-KiB messages, unbatched send/receive/delete; actual batch and delivery assumptions stay visible. Other native meters and workload assumptions retain their explicitly displayed default quantities. Workload translation and capacity assumptions are not benchmark measurements.
- Native monthly usage priced at the cited provider list prices; listed target allowances apply where present, excluding invoice credits, taxes and negotiated discounts. Rates as of 2026-10-22: us-east-1 → East US, USD/month.
- Source prices are reference charges, not an invoice. Target lines cover selected service usage/configuration only; adapter hosting and Tensor9 fees are excluded.
- Samples of explicit prices are not performance measurements or capacity qualification. No interpolation or break-even guarantee is implied.
- Variant assumptions show the first axis sample; any axis-dependent configuration is described by this curve’s workload note.
- Rates are cited provider list prices, editable for discounts, commitments or another region. Workload translation and capacity coefficients remain editable planning assumptions, not benchmark measurements or a commercial quote.
- Default-zero rates are explicit assumptions, not evidence that the deployed service or resource is free.
- Provisioned-unit minimums use an editable approximate allocation floor. Modeled target service cost is max(usage/allocation, minimum), with billable network, durable staging and dependent sinks added separately; actual RU/TU sizing, scaling increments and throughput remain unqualified.
- Durable staging is priced once: provisioned targets include adapter state in their selected allocation; native targets add a separate staging allocation when required. Adapter hosting is a separate allocation and must exclude resources already priced as staging, workers or target capacity.
- A declared adapter mapping and cost model do not establish implementation availability or service equivalence.
- This is a declared directed mapping; a planning estimate does not establish deployment or request-serving support.
- Authored planning assumptions, not measured adapter capacity. Origin rates are cited first-tier list prices, before free allowances and discounts.
- A cost scenario does not establish backend availability, protocol fidelity or production readiness. Registry serving status remains independent.
- Storage follows resident original messages, not every monthly message. Broker delivery bytes include redeliveries.
- FIFO estimates do not qualify dedup support, group throughput or single-group latency; backend limitations remain applicable.
- Azure Service Bus Standard bills a namespace base charge that includes 13 million operations a month, then graduated per-operation prices: USD 0.80 per million to 100 million, 0.50 to 2,500 million and 0.20 beyond. An operation is any API call (send, receive, complete) per 64 KB of message; the family’s managed operations count calls, not 64 KB units. Standard has no storage charge (queue size quota up to 5 GB is included). More than 1,000 brokered connections bill USD 0.03 per connection-month, which this profile does not model.
- AWS Price List API, AWSQueueService offer: https://pricing.us-east-1.amazonaws.com/offers/v1.0/aws/AWSQueueService/current/us-east-1/index.json
- Azure Retail Prices API: https://prices.azure.com/api/retail/prices
- Additional network transfer, backups, KMS, one-time migration and operational labor unless an explicit meter includes them.
- Destination application execution and separately billed downstream services; supply those allocations separately.
- Taxes, discounts, credits and free-tier allowances not explicitly listed by this model.
- Unmodeled dependent services, task execution and operations outside the selected workload family.
plan-ca45f8cb19ce07ffe770050ff2faf4e2ac2dad0b / 2026-10-22.planning.2. Curve: workload-1.
Sources: AWS Price List API, AWSQueueService offer, Azure Retail Prices API.
SQS Standard → Azure Service Bus: Authored native-usage planning example. Native monthly usage priced at the cited provider list prices; listed target allowances apply where present, excluding invoice credits, taxes and negotiated discounts.
Scenario source region: us-east-1. Scenario target region: East US. Currency: USD.
- Additional network transfer, backups, KMS, one-time migration and operational labor unless an explicit meter includes them.
- Destination application execution and separately billed downstream services; supply those allocations separately.
- Taxes, discounts, credits and free-tier allowances not explicitly listed by this model.
- Unmodeled dependent services, task execution and operations outside the selected workload family.
- Translated reads: 0 operations.
- Translated writes: 0 operations.
- Translated resident physical data: 0 GiB-month.
- Native provider operations: 0 operations.
- Published payload: 0 GiB.
- Delivered payload: 0 GiB.
- Allocated execution CPU: 0 vCPU-hour.
- Allocated execution RAM: 0 GiB-hour.
- Independent resource allocation: 0 resource-hour.
- Independent inventory: 0 resource-month.
- Input tokens: 0 tokens.
- Output tokens: 0 tokens.
- Billable network: 0 GiB.
- Dependent object sink retained data: 0 GiB-month.
- Dependent object sink writes: 0 writes.
- Rates are cited provider list prices, editable for discounts, commitments or another region. Workload translation and capacity coefficients remain editable planning assumptions, not benchmark measurements or a commercial quote.
- Default-zero rates are explicit assumptions, not evidence that the deployed service or resource is free.
- Provisioned-unit minimums use an editable approximate allocation floor. Modeled target service cost is max(usage/allocation, minimum), with billable network, durable staging and dependent sinks added separately; actual RU/TU sizing, scaling increments and throughput remain unqualified.
- Durable staging is priced once: provisioned targets include adapter state in their selected allocation; native targets add a separate staging allocation when required. Adapter hosting is a separate allocation and must exclude resources already priced as staging, workers or target capacity.
- A declared adapter mapping and cost model do not establish implementation availability or service equivalence.
- This is a declared directed mapping; a planning estimate does not establish deployment or request-serving support.
- Authored planning assumptions, not measured adapter capacity. Origin rates are cited first-tier list prices, before free allowances and discounts.
- A cost scenario does not establish backend availability, protocol fidelity or production readiness. Registry serving status remains independent.
- Storage follows resident original messages, not every monthly message. Broker delivery bytes include redeliveries.
- FIFO estimates do not qualify dedup support, group throughput or single-group latency; backend limitations remain applicable.
- Azure Service Bus Standard bills a namespace base charge that includes 13 million operations a month, then graduated per-operation prices: USD 0.80 per million to 100 million, 0.50 to 2,500 million and 0.20 beyond. An operation is any API call (send, receive, complete) per 64 KB of message; the family’s managed operations count calls, not 64 KB units. Standard has no storage charge (queue size quota up to 5 GB is included). More than 1,000 brokered connections bill USD 0.03 per connection-month, which this profile does not model.
plan-ca45f8cb19ce07ffe770050ff2faf4e2ac2dad0b / 2026-10-22.planning.2. Scenario: planning-example.
Sources: AWS Price List API, AWSQueueService offer, Azure Retail Prices API.
Via Azure Cosmos DB (queue)
How it works
Tensor9 adds an adapter, a proxy process, to your application pod and setsAWS_ENDPOINT_URL_SQS to its local address. Your application keeps its SQS SDK and its SendMessage and ReceiveMessage calls. The adapter performs them in Cosmos DB and returns SQS responses, error codes and MD5 checksums.
Each queue is a Cosmos DB container with one document per message. Sending, receiving, deleting, delays, visibility, dead-letter delivery and message counts all work on those documents. Standard queues hand out messages in arrival order, with best-effort ordering under concurrent traffic.


The application keeps its SQS SDK. The adapter stores and reads messages in Azure Cosmos DB.
Architecture
The adapter keeps all queue state in Cosmos DB, including which receiver has each message, so adapter instances can restart or scale out without losing it. It signs in through your AKS Workload Identity, with no static secret. Microsoft operates Cosmos DB’s durability, backups and high availability; Tensor9 operates the adapter. When the stack is deployed, Tensor9 creates one serverless Cosmos DB account and one database per appliance, and one container per declared queue, named after the queue. Each message document holds the body, attributes, receive count and visibility time. A Standard queue hands out messages in arrival order. Concurrent receivers get no fairness or no-starvation guarantee. Retention uses Cosmos DB’s own per-item time to live (TTL), so Cosmos DB deletes expired messages itself.

Each queue is one Cosmos DB container and each message a document; a Standard queue hands out messages with best-effort ordering.
Receiving messages
A receive takes the oldest visible message in one conditional write, hides it from other receivers and adds one to its receive count. If another receiver takes it first, the adapter moves on to the next message, so each message goes to one receiver at a time. When the visibility timeout passes, it can be delivered again. Standard queues use at-least-once delivery with best-effort ordering.ApproximateReceiveCount is the actual number of receives, not an estimate, and the MD5 checksums of the body and attributes are recomputed, so your SDK’s checks pass. Standard queues keep a delayed message hidden for its requested DelaySeconds, up to a maximum of 900 seconds. An omitted value means zero; larger values return InvalidParameterValue. SendMessageBatch writes each entry separately and reports a result for each entry.


A receive delivers the oldest visible message to exactly one consumer; if another consumer takes it first, the receive tries the next one. ApproximateReceiveCount is the actual receive count.
Receipt handles & visibility
Your consumer uses the receipt handle to delete a message or change its visibility. Here the handle refers to receive state stored in Cosmos DB, not to anything in the adapter’s memory, so a current handle works the same before and after a restart:DeleteMessage and ChangeMessageVisibility keep working.
A stale handle, for a message already deleted or received again under a newer handle, is accepted and has no effect, both on delete (as on SQS) and on a visibility change. The consumer cannot tell from the response that it no longer has the message. A handle from another queue, or one that cannot be read, is rejected with ReceiptHandleIsInvalid.
ChangeMessageVisibility updates the stored visibility time with no lock-duration maximum, and zero makes the message available again immediately. Retention can expire a message while it is in flight; extending visibility does not extend its lifetime. A visibility timeout does not stop a worker that is still processing an earlier receive.


Receipt handles still work after an adapter restart. Visibility is stored in Cosmos DB and has no lock-duration limit.
FIFO queues
For strict per-message-group ordering and five-minute duplicate-send suppression, use SQS FIFO. Standard queues provide at-least-once delivery with best-effort ordering.Dead-letter queues
A message received more thanmaxReceiveCount times is moved to the declared dead-letter queue. The copy reaches the DLQ before the message is removed from the source, and if the adapter crashes during the move, a retry finishes it. That retry can put a duplicate in the DLQ, so consumers of the DLQ must handle at-least-once delivery.


The adapter finishes interrupted dead-letter moves. Delivery to the DLQ is at least once, so a crash can cause a duplicate.
Limitations
Where SQS and Cosmos DB differ- Approximate counts behave differently: they can lag by about 5 seconds. The adapter caches counts briefly, so recent sends, deletes and expirations may not show at once. Use Azure monitoring to watch counts after deployment.
- Dead-letter delivery behaves differently: it can produce duplicates. A move interrupted by an adapter crash is finished without losing the message, but the DLQ can receive it more than once.
- Each appliance supports about 499 queues. All of an appliance’s queues share one serverless Cosmos DB account, which allows about 500 containers, one per queue. Beyond that, the build stops with a clear error instead of creating some of the queues. The account is serverless by design, which suits fleets of mostly idle queues.
- Geo-replication is not supported. The account is in a single region, the appliance’s region, with no geo-replica.
- Expiry behaves differently: Cosmos DB removes expired messages in the background. Per-item TTL is enforced by Cosmos DB’s background cleanup, and a message can expire while a consumer is processing it.
- Per-message delay is limited to a maximum of 900 seconds. Standard queues honor
DelaySecondsup to 900 seconds; larger values returnInvalidParameterValue. - You must manage the Cosmos DB account, database and containers in Terraform. Separate logical queue management from container provisioning: with Max adaptation, queue API calls manage logical queues on the provisioned containers, listings, tags and supported defaults, including retention. Terraform owns the account, database and containers; deleting a logical queue does not delete its container. Nonzero queue-level delay and new dead-letter routes are rejected.
Other considerations
- Moving from AWS. The Cosmos DB account, database and queue containers start empty, and messages in SQS are not migrated. Drain the source queue, or write to both queues, before cutover.
- Who operates what. Tensor9 creates the account, database and one container per declared queue from your queue declarations, and runs the adapter next to your application. Microsoft operates Cosmos DB’s durability, backups and high availability. You operate the Azure subscription, cluster patching and monitoring.
- What to monitor. Use Azure monitoring to track Cosmos DB request units and latency.
- Retention uses whole seconds. Each message’s TTL is set to its remaining retention in whole seconds, at least one second, so Cosmos DB never deletes a message before its retention ends. The adapter runs no cleanup of its own.
Example monthly charges
This Tensor9 BYOC scenario estimates service charges for the named origin and target services. Adapter hosting and commercial Tensor9 fees need separate allocations. How Tensor9 estimates costs explains the method and what the estimates include.SQS Standard · SQS request billing units
Feature: SQS Standard. Estimated monthly service charges by SQS request billing units. Adapter hosting and Tensor9 fees are excluded. Source: us-east-1; target: East US; currency: USD.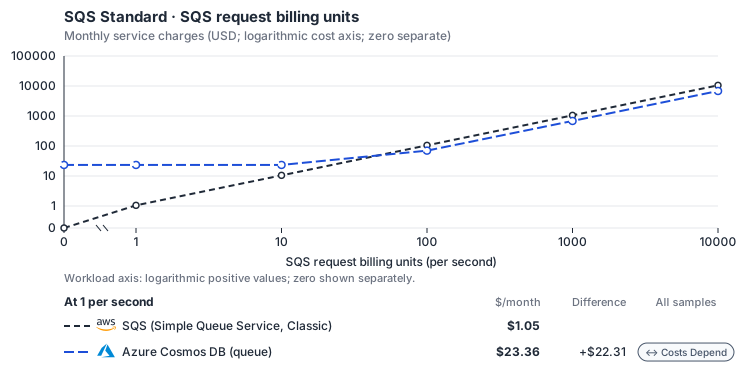
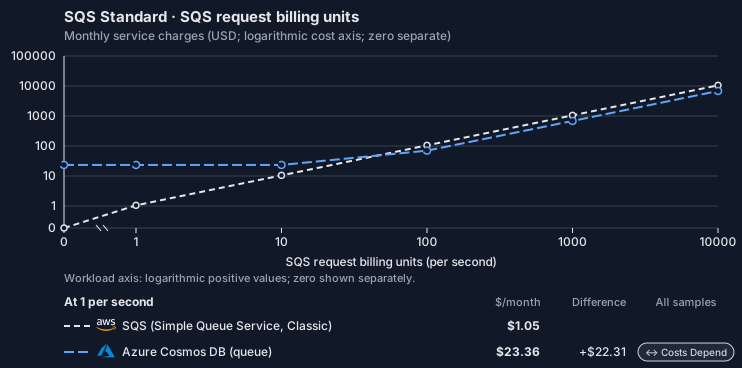
- 1-KiB messages, unbatched send/receive/delete; actual batch and delivery assumptions stay visible. Other native meters and workload assumptions retain their explicitly displayed default quantities. Workload translation and capacity assumptions are not benchmark measurements.
- Native monthly usage priced at the cited provider list prices; listed target allowances apply where present, excluding invoice credits, taxes and negotiated discounts. Rates as of 2026-10-22: us-east-1 → East US, USD/month.
- Source prices are reference charges, not an invoice. Target lines cover selected service usage/configuration only; adapter hosting and Tensor9 fees are excluded.
- Samples of explicit prices are not performance measurements or capacity qualification. No interpolation or break-even guarantee is implied.
- Variant assumptions show the first axis sample; any axis-dependent configuration is described by this curve’s workload note.
- Rates are cited provider list prices, editable for discounts, commitments or another region. Workload translation and capacity coefficients remain editable planning assumptions, not benchmark measurements or a commercial quote.
- Default-zero rates are explicit assumptions, not evidence that the deployed service or resource is free.
- Provisioned-unit minimums use an editable approximate allocation floor. Modeled target service cost is max(usage/allocation, minimum), with billable network, durable staging and dependent sinks added separately; actual RU/TU sizing, scaling increments and throughput remain unqualified.
- Durable staging is priced once: provisioned targets include adapter state in their selected allocation; native targets add a separate staging allocation when required. Adapter hosting is a separate allocation and must exclude resources already priced as staging, workers or target capacity.
- A declared adapter mapping and cost model do not establish implementation availability or service equivalence.
- This is a declared directed mapping; a planning estimate does not establish deployment or request-serving support.
- Authored planning assumptions, not measured adapter capacity. Origin rates are cited first-tier list prices, before free allowances and discounts.
- A cost scenario does not establish backend availability, protocol fidelity or production readiness. Registry serving status remains independent.
- Storage follows resident original messages, not every monthly message. Broker delivery bytes include redeliveries.
- FIFO estimates do not qualify dedup support, group throughput or single-group latency; backend limitations remain applicable.
- Azure Cosmos DB provisioned throughput bills 100-RU/s blocks per hour and stored GB-months; operations within the provisioned RU/s have no separate charge. Blocks are sized from the family’s reads at 1 RU and writes at 5.5 RU (1 KB items, no extra indexing) at full utilization after the planning peak factor, with the 400 RU/s smallest manual allocation as the floor (USD 23.36/month). Larger messages, indexing and query-based receives raise the RU charge; autoscale (USD 0.012 per 100 RU/s-hour) and serverless (USD 0.25 per million RUs) are not selected.
- AWS Price List API, AWSQueueService offer: https://pricing.us-east-1.amazonaws.com/offers/v1.0/aws/AWSQueueService/current/us-east-1/index.json
- Azure Retail Prices API: https://prices.azure.com/api/retail/prices
- Additional network transfer, backups, KMS, one-time migration and operational labor unless an explicit meter includes them.
- Destination application execution and separately billed downstream services; supply those allocations separately.
- Taxes, discounts, credits and free-tier allowances not explicitly listed by this model.
- Unmodeled dependent services, task execution and operations outside the selected workload family.
plan-dad0c8f973de92af6643c3cb9f65340d91c718a5 / 2026-10-22.planning.2. Curve: workload-1.
Sources: AWS Price List API, AWSQueueService offer, Azure Retail Prices API.
SQS Standard → Azure Cosmos DB (queue): Authored native-usage planning example. Native monthly usage priced at the cited provider list prices; listed target allowances apply where present, excluding invoice credits, taxes and negotiated discounts.
Scenario source region: us-east-1. Scenario target region: East US. Currency: USD.
- Additional network transfer, backups, KMS, one-time migration and operational labor unless an explicit meter includes them.
- Destination application execution and separately billed downstream services; supply those allocations separately.
- Taxes, discounts, credits and free-tier allowances not explicitly listed by this model.
- Unmodeled dependent services, task execution and operations outside the selected workload family.
- Translated reads: 0 operations.
- Translated writes: 0 operations.
- Translated resident physical data: 0 GiB-month.
- Native provider operations: 0 operations.
- Published payload: 0 GiB.
- Delivered payload: 0 GiB.
- Allocated execution CPU: 0 vCPU-hour.
- Allocated execution RAM: 0 GiB-hour.
- Independent resource allocation: 0 resource-hour.
- Independent inventory: 0 resource-month.
- Input tokens: 0 tokens.
- Output tokens: 0 tokens.
- Billable network: 0 GiB.
- Dependent object sink retained data: 0 GiB-month.
- Dependent object sink writes: 0 writes.
- Rates are cited provider list prices, editable for discounts, commitments or another region. Workload translation and capacity coefficients remain editable planning assumptions, not benchmark measurements or a commercial quote.
- Default-zero rates are explicit assumptions, not evidence that the deployed service or resource is free.
- Provisioned-unit minimums use an editable approximate allocation floor. Modeled target service cost is max(usage/allocation, minimum), with billable network, durable staging and dependent sinks added separately; actual RU/TU sizing, scaling increments and throughput remain unqualified.
- Durable staging is priced once: provisioned targets include adapter state in their selected allocation; native targets add a separate staging allocation when required. Adapter hosting is a separate allocation and must exclude resources already priced as staging, workers or target capacity.
- A declared adapter mapping and cost model do not establish implementation availability or service equivalence.
- This is a declared directed mapping; a planning estimate does not establish deployment or request-serving support.
- Authored planning assumptions, not measured adapter capacity. Origin rates are cited first-tier list prices, before free allowances and discounts.
- A cost scenario does not establish backend availability, protocol fidelity or production readiness. Registry serving status remains independent.
- Storage follows resident original messages, not every monthly message. Broker delivery bytes include redeliveries.
- FIFO estimates do not qualify dedup support, group throughput or single-group latency; backend limitations remain applicable.
- Azure Cosmos DB provisioned throughput bills 100-RU/s blocks per hour and stored GB-months; operations within the provisioned RU/s have no separate charge. Blocks are sized from the family’s reads at 1 RU and writes at 5.5 RU (1 KB items, no extra indexing) at full utilization after the planning peak factor, with the 400 RU/s smallest manual allocation as the floor (USD 23.36/month). Larger messages, indexing and query-based receives raise the RU charge; autoscale (USD 0.012 per 100 RU/s-hour) and serverless (USD 0.25 per million RUs) are not selected.
plan-dad0c8f973de92af6643c3cb9f65340d91c718a5 / 2026-10-22.planning.2. Scenario: planning-example.
Sources: AWS Price List API, AWSQueueService offer, Azure Retail Prices API.
Via PostgreSQL Flexible Server
PostgreSQL hosting
Microsoft operates PostgreSQL Flexible Server, including zone-redundant HA and point-in-time recovery backups. The adapter uses short-lived Microsoft Entra tokens as database passwords. Queue data stays outside the customer’s Kubernetes cluster and survives its rebuild. One server and database hold all queues for the deployment, sharing capacity and maintenance; the default server size is fixed because SQS supplies no source instance size. Tensor9 operates the queue schema and adapter. Queues start empty; existing SQS messages are not migrated. Drain the source or coordinate dual writes before cutover.Queue behavior
Queues use the same PostgreSQL tables, receive steps, stored receipt handles and single-transaction dead-letter moves described in PostgreSQL queue behavior. Receipt handles survive adapter restarts; stale receipt handles return an error. Retention still removes messages in flight. All queues share database capacity, so a busy queue can affect others. The documented Standard-queue benchmark does not establish this host’s capacity or FIFO throughput. Delivery is at least once with best-effort ordering. SQS FIFO queues, with group ordering and deduplication, are not available today.Example monthly charges
This Tensor9 BYOC scenario estimates service charges for the named origin and target services. Adapter hosting and commercial Tensor9 fees need separate allocations. How Tensor9 estimates costs explains the method and what the estimates include.SQS Standard · SQS request billing units
Feature: SQS Standard. Estimated monthly service charges by SQS request billing units. Adapter hosting and Tensor9 fees are excluded. Source: us-east-1; target: eastus; currency: USD.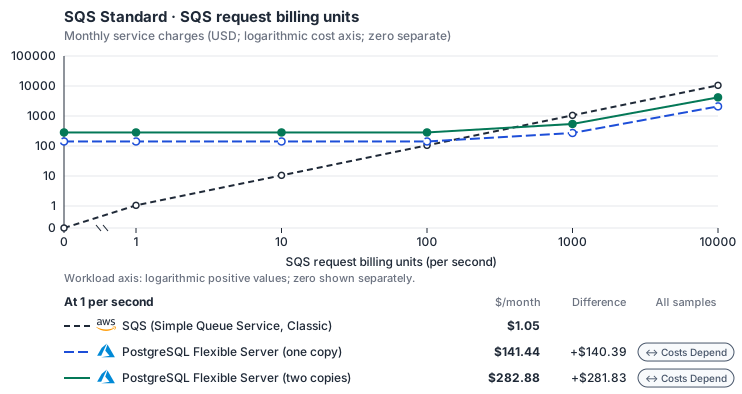
- 1-KiB messages, unbatched send/receive/delete; actual batch and delivery assumptions stay visible. Other native meters and workload assumptions retain their explicitly displayed default quantities. Workload translation and capacity assumptions are not benchmark measurements.
- Native monthly usage priced at the cited provider list prices; listed target allowances apply where present, excluding invoice credits, taxes and negotiated discounts. Rates as of 2026-10-22: us-east-1 → eastus, USD/month.
- Source prices are reference charges, not an invoice. Target lines cover selected service usage/configuration only; adapter hosting and Tensor9 fees are excluded.
- Samples of explicit prices are not performance measurements or capacity qualification. No interpolation or break-even guarantee is implied.
- Variant assumptions show the first axis sample; any axis-dependent configuration is described by this curve’s workload note.
- Rates are cited provider list prices, editable for discounts, commitments or another region. Workload translation and capacity coefficients remain editable planning assumptions, not benchmark measurements or a commercial quote.
- Default-zero rates are explicit assumptions, not evidence that the deployed service or resource is free.
- Provisioned-unit minimums use an editable approximate allocation floor. Modeled target service cost is max(usage/allocation, minimum), with billable network, durable staging and dependent sinks added separately; actual RU/TU sizing, scaling increments and throughput remain unqualified.
- Durable staging is priced once: provisioned targets include adapter state in their selected allocation; native targets add a separate staging allocation when required. Adapter hosting is a separate allocation and must exclude resources already priced as staging, workers or target capacity.
- A declared adapter mapping and cost model do not establish implementation availability or service equivalence.
- This is a declared directed mapping; a planning estimate does not establish deployment or request-serving support.
- Authored planning assumptions, not measured adapter capacity. Origin rates are cited first-tier list prices, before free allowances and discounts.
- A cost scenario does not establish backend availability, protocol fidelity or production readiness. Registry serving status remains independent.
- Storage follows resident original messages, not every monthly message. Broker delivery bytes include redeliveries.
- FIFO estimates do not qualify dedup support, group throughput or single-group latency; backend limitations remain applicable.
- Azure Database for PostgreSQL Flexible Server bills vCores with a fixed memory ratio per series; the vCPU and memory rates decompose the General Purpose and Memory Optimized v5 prices. High availability bills the standby’s compute and storage as a second copy. The minimum is the smallest Burstable server, which does not support high availability; the smallest General Purpose server (2 vCores) costs USD 133.62 per month. Additional IOPS, backup storage and reserved capacity are not selected.
- Row-store throughput (capacityOpsPerVcpuSecond, default 1500) is measured-by-tensor9 as a lower bound: the DynamoDB adapter on Cloud SQL db-custom-2-7680 (2 vCPU, PostgreSQL 16, us-west1) served 2,974 ops/s of YCSB-A at 16 threads without recorded saturation (src/main/kotlin/t9/prime/equiv/generated/eval/CloudsqlPostgresqlYcsbAT16GoYcsbV1_0_0.kt). Published CPU-bound pgbench reaches 3,101 read-write transactions and 20,289 point reads per vCPU-second (AWS z1d.2xlarge, PostgreSQL 14.5), so actual capacity is likely higher. Reads and writes share one coefficient: at the same adapter version, read-only YCSB-C was not faster than 50%-update YCSB-A.
- Log-broker throughput (capacityStreamMiBPerVcpuSecond 20 at 0.5 utilization, 4 GiB RAM per vCPU) is provider-documented by Google Managed Service for Apache Kafka sizing (https://docs.cloud.google.com/managed-service-for-apache-kafka/docs/plan-cluster-size): write-equivalent bytes are replicated writes plus a quarter of reads. Producer batches below 10 KB lower per-CPU throughput; that penalty is not modeled.
- Disk utilization 0.8 is provider-documented headroom below Cloud SQL automatic storage increase, which triggers near 91-95% full (https://docs.cloud.google.com/sql/docs/postgres/instance-settings). The 20 GiB reserve exceeds PostgreSQL’s 1 GB default max_wal_size; the remainder of that reserve is unmeasured.
- CPU tiers double from 2 vCPUs to the target’s largest node at 4 GiB per vCPU; each target’s documented largest node bounds CPU, RAM, RAM per vCPU and disk, and the durable staging database uses Cloud SQL Enterprise (96 vCPU, 6.5 GiB per vCPU, 624 GiB, 64 TiB). Targets billed per capacity unit or throughput unit are sized by their backend instead.
- No public evidence: peak/mean work (2) and the RAM working-set fraction (0.1). Proposed measurements: the p99 one-minute rate over the monthly mean from customer CloudWatch metrics; the buffer hit ratio while stepping RAM under a fixed YCSB-B load.
- Node bounds: E96ds_v5 has 96 vCores and 672 GiB (https://learn.microsoft.com/en-us/azure/postgresql/compute-storage/concepts-compute); Premium SSD storage holds up to 32,767 GiB (https://learn.microsoft.com/en-us/azure/postgresql/compute-storage/concepts-storage).
- Stored GiB already includes the origin family’s physical footprint assumptions; no second storage amplification is applied.
- The operations/vCPU coefficient supplies the compute requirement alongside explicit resource-hour minima.
- Copies and allocation fractions change cost only; they do not increase modeled primary capacity.
- AWS Price List API, AWSQueueService offer: https://pricing.us-east-1.amazonaws.com/offers/v1.0/aws/AWSQueueService/current/us-east-1/index.json
- Azure Retail Prices API: https://prices.azure.com/api/retail/prices
- Additional network transfer, backups, KMS, one-time migration and operational labor unless an explicit meter includes them.
- Destination application execution and separately billed downstream services; supply those allocations separately.
- Taxes, discounts, credits and free-tier allowances not explicitly listed by this model.
- Unmodeled dependent services, task execution and operations outside the selected workload family.
plan-89783f4d5bd47a02bac1ee1d677521ebf845f89c / 2026-10-22.planning.2. Curve: workload-1.
Sources: AWS Price List API, AWSQueueService offer, Azure Retail Prices API.
SQS Standard → PostgreSQL Flexible Server: Authored native-usage planning example. Native monthly usage priced at the cited provider list prices; listed target allowances apply where present, excluding invoice credits, taxes and negotiated discounts.
Scenario source region: us-east-1. Scenario target region: eastus. Currency: USD.
- Additional network transfer, backups, KMS, one-time migration and operational labor unless an explicit meter includes them.
- Destination application execution and separately billed downstream services; supply those allocations separately.
- Taxes, discounts, credits and free-tier allowances not explicitly listed by this model.
- Unmodeled dependent services, task execution and operations outside the selected workload family.
- Translated reads: 0 operations.
- Translated writes: 0 operations.
- Translated resident physical data: 0 GiB-month.
- Native provider operations: 0 operations.
- Published payload: 0 GiB.
- Delivered payload: 0 GiB.
- Allocated execution CPU: 0 vCPU-hour.
- Allocated execution RAM: 0 GiB-hour.
- Independent resource allocation: 0 resource-hour.
- Independent inventory: 0 resource-month.
- Input tokens: 0 tokens.
- Output tokens: 0 tokens.
- Billable network: 0 GiB.
- Dependent object sink retained data: 0 GiB-month.
- Dependent object sink writes: 0 writes.
- Rates are cited provider list prices, editable for discounts, commitments or another region. Workload translation and capacity coefficients remain editable planning assumptions, not benchmark measurements or a commercial quote.
- Default-zero rates are explicit assumptions, not evidence that the deployed service or resource is free.
- Provisioned-unit minimums use an editable approximate allocation floor. Modeled target service cost is max(usage/allocation, minimum), with billable network, durable staging and dependent sinks added separately; actual RU/TU sizing, scaling increments and throughput remain unqualified.
- Durable staging is priced once: provisioned targets include adapter state in their selected allocation; native targets add a separate staging allocation when required. Adapter hosting is a separate allocation and must exclude resources already priced as staging, workers or target capacity.
- A declared adapter mapping and cost model do not establish implementation availability or service equivalence.
- This is a declared directed mapping; a planning estimate does not establish deployment or request-serving support.
- Authored planning assumptions, not measured adapter capacity. Origin rates are cited first-tier list prices, before free allowances and discounts.
- A cost scenario does not establish backend availability, protocol fidelity or production readiness. Registry serving status remains independent.
- Storage follows resident original messages, not every monthly message. Broker delivery bytes include redeliveries.
- FIFO estimates do not qualify dedup support, group throughput or single-group latency; backend limitations remain applicable.
- Azure Database for PostgreSQL Flexible Server bills vCores with a fixed memory ratio per series; the vCPU and memory rates decompose the General Purpose and Memory Optimized v5 prices. High availability bills the standby’s compute and storage as a second copy. The minimum is the smallest Burstable server, which does not support high availability; the smallest General Purpose server (2 vCores) costs USD 133.62 per month. Additional IOPS, backup storage and reserved capacity are not selected.
- Row-store throughput (capacityOpsPerVcpuSecond, default 1500) is measured-by-tensor9 as a lower bound: the DynamoDB adapter on Cloud SQL db-custom-2-7680 (2 vCPU, PostgreSQL 16, us-west1) served 2,974 ops/s of YCSB-A at 16 threads without recorded saturation (src/main/kotlin/t9/prime/equiv/generated/eval/CloudsqlPostgresqlYcsbAT16GoYcsbV1_0_0.kt). Published CPU-bound pgbench reaches 3,101 read-write transactions and 20,289 point reads per vCPU-second (AWS z1d.2xlarge, PostgreSQL 14.5), so actual capacity is likely higher. Reads and writes share one coefficient: at the same adapter version, read-only YCSB-C was not faster than 50%-update YCSB-A.
- Log-broker throughput (capacityStreamMiBPerVcpuSecond 20 at 0.5 utilization, 4 GiB RAM per vCPU) is provider-documented by Google Managed Service for Apache Kafka sizing (https://docs.cloud.google.com/managed-service-for-apache-kafka/docs/plan-cluster-size): write-equivalent bytes are replicated writes plus a quarter of reads. Producer batches below 10 KB lower per-CPU throughput; that penalty is not modeled.
- Disk utilization 0.8 is provider-documented headroom below Cloud SQL automatic storage increase, which triggers near 91-95% full (https://docs.cloud.google.com/sql/docs/postgres/instance-settings). The 20 GiB reserve exceeds PostgreSQL’s 1 GB default max_wal_size; the remainder of that reserve is unmeasured.
- CPU tiers double from 2 vCPUs to the target’s largest node at 4 GiB per vCPU; each target’s documented largest node bounds CPU, RAM, RAM per vCPU and disk, and the durable staging database uses Cloud SQL Enterprise (96 vCPU, 6.5 GiB per vCPU, 624 GiB, 64 TiB). Targets billed per capacity unit or throughput unit are sized by their backend instead.
- No public evidence: peak/mean work (2) and the RAM working-set fraction (0.1). Proposed measurements: the p99 one-minute rate over the monthly mean from customer CloudWatch metrics; the buffer hit ratio while stepping RAM under a fixed YCSB-B load.
- Node bounds: E96ds_v5 has 96 vCores and 672 GiB (https://learn.microsoft.com/en-us/azure/postgresql/compute-storage/concepts-compute); Premium SSD storage holds up to 32,767 GiB (https://learn.microsoft.com/en-us/azure/postgresql/compute-storage/concepts-storage).
- Stored GiB already includes the origin family’s physical footprint assumptions; no second storage amplification is applied.
- The operations/vCPU coefficient supplies the compute requirement alongside explicit resource-hour minima.
- Copies and allocation fractions change cost only; they do not increase modeled primary capacity.
plan-89783f4d5bd47a02bac1ee1d677521ebf845f89c / 2026-10-22.planning.2. Scenario: planning-example.
Sources: AWS Price List API, AWSQueueService offer, Azure Retail Prices API.
On OCI
Via OCI Queue
How it works
Tensor9 adds an adapter process to your application pod in OCI and setsAWS_ENDPOINT_URL_SQS to its local address. Your application keeps its SendMessage and ReceiveMessage calls. The adapter performs them on OCI Queue and returns SQS responses, error codes and MD5 checksums.
Each declared standard SQS queue becomes an OCI queue in the customer’s compartment. SendMessage puts a message, ReceiveMessage gets one with a receipt, and DeleteMessage deletes it using that receipt. OCI Queue keeps the messages, receipts, delivery counts and visibility deadlines, so the adapter keeps nothing that must survive a restart. FIFO queues need a different backend, because OCI Queue has no group ordering or deduplication.


Your application keeps its SQS SDK; the adapter turns each call into OCI Queue operations.
Architecture
Because receipts live in OCI Queue, receipt handles stay usable across calls, adapter processes and restarts, and you can run several adapter instances without them sharing state. The adapter signs in with the customer’s OCI workload identity, with no stored credential. Oracle operates queue durability, backups, replication and availability; Tensor9 operates the adapter. At deployment, Tensor9 creates one OCI queue per declared SQS queue in the customer’s compartment, named after it. The queue’s visibility timeout is the declared SQS default; both services default to 30 seconds. Retention is kept up to OCI Queue’s 7-day maximum, andmaxReceiveCount sets the dead-letter delivery-count threshold. OCI Queue applies these settings and tracks queued and in-flight messages.


Each SQS queue is one OCI queue in the customer’s compartment; OCI Queue keeps receipts, receive counts and visibility deadlines.
Receiving messages
ReceiveMessage long-polls. WaitTimeSeconds, at most 20 as in SQS, becomes OCI Queue’s long-poll timeout, which allows up to 30 seconds, so every SQS wait value works unchanged. Each receive gets up to 10 messages, the SQS limit, although OCI Queue itself allows 20. A per-receive VisibilityTimeout is passed to OCI Queue, which applies it when it hands the message out.
The OCI receipt becomes the SQS receipt handle. ApproximateReceiveCount is OCI Queue’s delivery count, starting at 1 and increasing on each redelivery. The adapter rebuilds the body and attributes and recomputes MD5 checksums so your SDK can verify them. Delivery is at least once with best-effort ordering. Single sends use one put; batch sends use a multi-message put with a result for each entry. Deletion uses the receipt. Use OCI monitoring to measure latency and throughput.


A receive returns OCI Queue’s own receipt and delivery count; there is no lock to renew. ApproximateReceiveCount counts from 1.
Receipt handles & visibility
The receipt handle contains OCI Queue’s receipt token. Deletes and visibility updates use it across calls, connections and adapter restarts. A receipt replaced by a later receive, or belonging to a message already deleted, succeeds without doing anything. Malformed handles and handles for another queue returnReceiptHandleIsInvalid.
The visibility timeout is OCI Queue’s per-message visibility. The queue’s default is set on the OCI queue, and OCI Queue’s 30-second default equals SQS’s, so a queue with no setting behaves the same. A per-receive VisibilityTimeout travels with the receive, and ChangeMessageVisibility becomes an OCI update of the message’s visibility. A zero-second change makes the message available to receive again immediately. SQS’s 12-hour maximum equals OCI Queue’s, so every SQS value works. If a consumer’s message was delivered again to someone else, its old receipt is outdated and its update does nothing, rather than affecting the other consumer’s delivery.


Receipt handles keep working across adapter restarts. The 30-second visibility default and 12-hour maximum match SQS.
Dead-letter & retention
maxReceiveCount sets the queue’s delivery-count threshold. When a message’s count exceeds it, OCI Queue moves the message to the queue’s built-in dead-letter queue; the adapter does not copy or delete anything. The threshold is kept, but the destination is always that built-in queue: the dead-letter target named in your redrive policy is dropped. If the build cannot read maxReceiveCount as a literal, no threshold is set and the build reports it.
When Tensor9 provisions the queue, it sets the four-day retention default (345600 seconds) explicitly if none is declared. A declared value above OCI’s seven-day maximum (604800 seconds) is capped at seven days, with a warning, so a queue declared with SQS’s 14-day retention expires messages a week earlier. This applies when the queue is provisioned, not to a later SetQueueAttributes request.


OCI Queue moves a message to its built-in dead-letter queue after maxReceiveCount deliveries. Retention above 7 days is capped, with a warning.
Limitations
Where SQS and OCI Queue differ- FIFO queues are not supported. OCI Queue has no ordering, sessions or deduplication, so a
.fifoqueue is placed on a backend that supports ordering when the deployment is built. Any.fiforequest that still reaches this backend (a pre-declared queue or a URL from elsewhere) is rejected on send, receive, create and purge. - Messages larger than 128 KB are not supported. OCI Queue caps a message at
131072bytes, against SQS’s 1 MiB. An oversize send is rejected withInvalidParameterValuenaming the size and the limit, never truncated. Shrink large payloads, or store the body in OCI Object Storage and send a reference to it. - Retention longer than 7 days is not supported. Retention is kept exactly up to OCI Queue’s 7-day maximum (
604800); a longer value is capped, so a 14-day SQS queue’s messages expire up to a week earlier. The 4-day default (345600) is set explicitly. - Dead-lettering behaves differently.
maxReceiveCountis kept exactly, but OCI Queue always moves the message to the queue’s own built-in dead-letter queue, not to the queue or ARN your redrive policy names. - Queue-level delay is not supported. A positive
delay_secondsis dropped with a warning when the queue is created, because OCI Queue has no such setting. Review delayed-delivery needs before choosing this backend. - Queue policies and customer-managed encryption keys are not kept. An SQS queue policy is removed, with a warning; access is controlled by IAM policies at compartment scope. A
kms_master_key_idis not applied, also with a warning. - You must give each queue a literal name. The OCI queue is named from the SQS queue name, so a computed name or a
name_prefixstops the build with an error. - Queue changes behave differently.
ListQueuesreturns the declared set, and requests that would reconfigure a queue away from its declared settings return an error.SendMessageBatchandDeleteMessageBatchuse OCI multi-message operations with a result per entry, andApproximateNumberOfMessagesandApproximateNumberOfMessagesNotVisiblecome from OCI Queue’s visible and in-flight counts.
Other considerations
- Moving from AWS. The OCI queue starts empty, so messages still in SQS stay on AWS. Switch over once the SQS queue is drained, or send to both until it is.
- Before going live. Queue names, visibility and dead-letter thresholds are kept. Review queues that use SQS’s 14-day retention or messages above 128 KB, which OCI Queue cannot hold.
- Who operates what. Oracle operates OCI Queue durability, backup, replication and availability; Tensor9 operates the adapter, which reaches OCI Queue with the customer’s workload identity.
- Cost. Estimate from your send, receive and delete rates and message volume.
Example monthly charges
This Tensor9 BYOC scenario estimates service charges for the named origin and target services. Adapter hosting and commercial Tensor9 fees need separate allocations. How Tensor9 estimates costs explains the method and what the estimates include.SQS Standard · SQS request billing units
Feature: SQS Standard. Estimated monthly service charges by SQS request billing units. Adapter hosting and Tensor9 fees are excluded. Source: us-east-1; target: us-ashburn-1 (OCI global price list); currency: USD.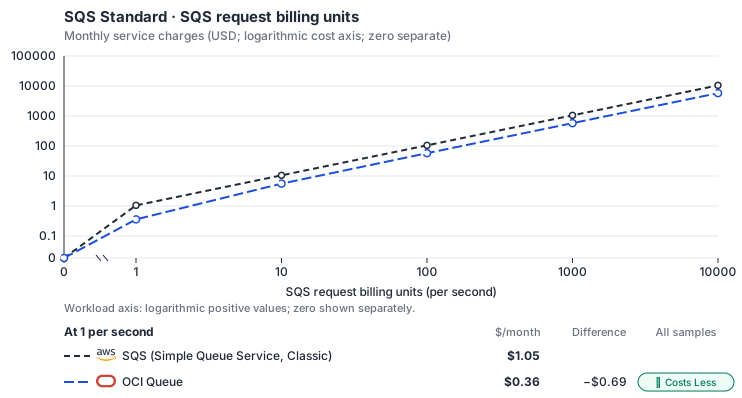
- 1-KiB messages, unbatched send/receive/delete; actual batch and delivery assumptions stay visible. Other native meters and workload assumptions retain their explicitly displayed default quantities. Workload translation and capacity assumptions are not benchmark measurements.
- Native monthly usage priced at the cited provider list prices; listed target allowances apply where present, excluding invoice credits, taxes and negotiated discounts. Rates as of 2026-10-22: us-east-1 → us-ashburn-1 (OCI global price list), USD/month.
- Source prices are reference charges, not an invoice. Target lines cover selected service usage/configuration only; adapter hosting and Tensor9 fees are excluded.
- Samples of explicit prices are not performance measurements or capacity qualification. No interpolation or break-even guarantee is implied.
- Variant assumptions show the first axis sample; any axis-dependent configuration is described by this curve’s workload note.
- Rates are cited provider list prices, editable for discounts, commitments or another region. Workload translation and capacity coefficients remain editable planning assumptions, not benchmark measurements or a commercial quote.
- Default-zero rates are explicit assumptions, not evidence that the deployed service or resource is free.
- Provisioned-unit minimums use an editable approximate allocation floor. Modeled target service cost is max(usage/allocation, minimum), with billable network, durable staging and dependent sinks added separately; actual RU/TU sizing, scaling increments and throughput remain unqualified.
- Durable staging is priced once: provisioned targets include adapter state in their selected allocation; native targets add a separate staging allocation when required. Adapter hosting is a separate allocation and must exclude resources already priced as staging, workers or target capacity.
- A declared adapter mapping and cost model do not establish implementation availability or service equivalence.
- This is a declared directed mapping; a planning estimate does not establish deployment or request-serving support.
- Authored planning assumptions, not measured adapter capacity. Origin rates are cited first-tier list prices, before free allowances and discounts.
- A cost scenario does not establish backend availability, protocol fidelity or production readiness. Registry serving status remains independent.
- Storage follows resident original messages, not every monthly message. Broker delivery bytes include redeliveries.
- FIFO estimates do not qualify dedup support, group throughput or single-group latency; backend limitations remain applicable.
- OCI Queue bills requests after the first million each month; the price list counts each request as 64 KB, so larger messages or batches count as several requests, which the family’s call counts do not multiply. Queue has no storage or retention charge.
- AWS Price List API, AWSQueueService offer: https://pricing.us-east-1.amazonaws.com/offers/v1.0/aws/AWSQueueService/current/us-east-1/index.json
- OCI price list API: https://apexapps.oracle.com/pls/apex/cetools/api/v1/products/
- Additional network transfer, backups, KMS, one-time migration and operational labor unless an explicit meter includes them.
- Destination application execution and separately billed downstream services; supply those allocations separately.
- Taxes, discounts, credits and free-tier allowances not explicitly listed by this model.
- Unmodeled dependent services, task execution and operations outside the selected workload family.
plan-15dc11b20607d1fce76620d26b1597e97614129d / 2026-10-22.planning.2. Curve: workload-1.
Sources: AWS Price List API, AWSQueueService offer, OCI price list API.
SQS Standard → OCI Queue: Authored native-usage planning example. Native monthly usage priced at the cited provider list prices; listed target allowances apply where present, excluding invoice credits, taxes and negotiated discounts.
Scenario source region: us-east-1. Scenario target region: us-ashburn-1 (OCI global price list). Currency: USD.
- Additional network transfer, backups, KMS, one-time migration and operational labor unless an explicit meter includes them.
- Destination application execution and separately billed downstream services; supply those allocations separately.
- Taxes, discounts, credits and free-tier allowances not explicitly listed by this model.
- Unmodeled dependent services, task execution and operations outside the selected workload family.
- Translated reads: 0 operations.
- Translated writes: 0 operations.
- Translated resident physical data: 0 GiB-month.
- Native provider operations: 0 operations.
- Published payload: 0 GiB.
- Delivered payload: 0 GiB.
- Allocated execution CPU: 0 vCPU-hour.
- Allocated execution RAM: 0 GiB-hour.
- Independent resource allocation: 0 resource-hour.
- Independent inventory: 0 resource-month.
- Input tokens: 0 tokens.
- Output tokens: 0 tokens.
- Billable network: 0 GiB.
- Dependent object sink retained data: 0 GiB-month.
- Dependent object sink writes: 0 writes.
- Rates are cited provider list prices, editable for discounts, commitments or another region. Workload translation and capacity coefficients remain editable planning assumptions, not benchmark measurements or a commercial quote.
- Default-zero rates are explicit assumptions, not evidence that the deployed service or resource is free.
- Provisioned-unit minimums use an editable approximate allocation floor. Modeled target service cost is max(usage/allocation, minimum), with billable network, durable staging and dependent sinks added separately; actual RU/TU sizing, scaling increments and throughput remain unqualified.
- Durable staging is priced once: provisioned targets include adapter state in their selected allocation; native targets add a separate staging allocation when required. Adapter hosting is a separate allocation and must exclude resources already priced as staging, workers or target capacity.
- A declared adapter mapping and cost model do not establish implementation availability or service equivalence.
- This is a declared directed mapping; a planning estimate does not establish deployment or request-serving support.
- Authored planning assumptions, not measured adapter capacity. Origin rates are cited first-tier list prices, before free allowances and discounts.
- A cost scenario does not establish backend availability, protocol fidelity or production readiness. Registry serving status remains independent.
- Storage follows resident original messages, not every monthly message. Broker delivery bytes include redeliveries.
- FIFO estimates do not qualify dedup support, group throughput or single-group latency; backend limitations remain applicable.
- OCI Queue bills requests after the first million each month; the price list counts each request as 64 KB, so larger messages or batches count as several requests, which the family’s call counts do not multiply. Queue has no storage or retention charge.
plan-15dc11b20607d1fce76620d26b1597e97614129d / 2026-10-22.planning.2. Scenario: planning-example.
Sources: AWS Price List API, AWSQueueService offer, OCI price list API.
Costs
Estimated monthly service charges for each backend with a published cost model, at one sampled workload from that model’s cost curve. Adapter hosting and Tensor9 fees are excluded. How Tensor9 estimates costs explains the method, what the estimates include and how to read their qualifications.Service level agreements
Listed terms cover requests sent through this service adapter. They do not cover direct connections to the target service or replace the cloud provider’s own SLA. Each origin-to-target pair has its own terms or an explicit pending status. See the SLA tables, measurement rules, and scaling conditions.SQS to Cosmos DB
Why these latency targets differ
The shared Standard/FIFO point-operation target is 20 ms, with 200 ms for a batch of up to ten sends. Cosmos FIFO uses a per-group sequence counter, a durable deduplication marker and an in-flight ownership slot. Their conditional reads/writes are adapter coordination; the clock cannot exclude them merely because they use Cosmos DB. The shared target preserves room for that work instead of advertising the cost of a simple native queue forwarder. Ready-message pickup and delay after the requested wait remain at 500 ms. Discovery, candidate inspection, conditional claims and polling can dominate this path even for a tiny message. The target is not an end-to-end promise for clearing a backlog, and Standard and FIFO observations must remain separate.Adapter and scope
Receive timing
Two phases ofReceiveMessage have separate measurements:
- Ready-message pickup: time from a message becoming available to a waiting receiver until the adapter sends the response. Only separately measured time spent waiting for the backend service is excluded.
- Delay after the requested wait: extra adapter time after the requested wait for a message has ended.
Message guarantees
A send can return success only after the message state has been durably saved. A deduplication marker alone must not produce success for a message that was never committed. The adapter must use the same record of accepted messages when returning success, checking for duplicates, and recovering from a crash. Standard queues can redeliver messages. FIFO preserves the profile’s per-group ordering and supported deduplication behavior; it does not promise global order across groups or exactly-once effects in your application. A consumer can perform a business action and fail before deleting the message, so application-side idempotency still matters. The adapter follows its documented rules for visibility, expiration, message deletion, and movement to a dead-letter queue. Successfully completed changes must survive the process failures covered by the agreement. An expired receipt handle produces the result documented for that adapter; different backends need not return the same error. Approximate queue counts help with troubleshooting but are not guaranteed to show the exact current queue depth.Useful throughput
Count completed API calls separately from message work. A valid emptyReceiveMessage completes an API call but delivers no message. One successful send, nonempty receive and delete form a message lifecycle involving at least three API calls. Redelivery and internal retries must not inflate the count of distinct messages processed.
Measure Standard and FIFO separately. FIFO group distribution, time between receive and delete, visibility timeout, delayed messages and dead-letter traffic change the scaling limit. A large number of consumers cannot make a single serialized group behave like many independent groups.
These standard service levels do not reserve a fixed message rate or specify a maximum throughput. Tensor9 and the customer must agree on limits for the actual workload and production deployment, including how quickly traffic can grow and how large a burst can be. Autoscaling is intended to maintain the stated latency and endpoint reachability within those limits. It cannot remove ordering requirements or backend-service limits.
Operation terms
The named operations retain their documented behavior with supported request options. The 1 KiB limits apply to the latency targets.DeleteMessageBatch, ChangeMessageVisibilityBatch, queue management, tagging and approximate-count reads have no numerical SLA under these standard terms. A capability in the service profile does not automatically receive another operation’s SLA.
The pickup service level differs from the Cloud SQL service level. These targets apply to their respective receive paths; they are not comparative benchmark results or a recommendation to choose one backend.
Scaling on Cosmos DB
Partition distribution, conditional message claims, deduplication and FIFO group serialization affect useful throughput. Native request-unit consumption and throttling need to be considered alongside adapter scheduling, repeated scans and retry amplification. Additional replicas can process independent work. They do not remove contention around the same message claim or FIFO group, and they do not grant additional native serverless capacity. Track completed message lifecycles, native calls per lifecycle and repeated failed claims separately. Once a message expires, the queue must treat it as expired even if the cloud provider has not yet removed its stored data. Do not count expired messages as available work merely because they still appear in a storage view. Time the adapter takes to find an available message, including waits between queue checks, also counts toward adapter latency. It is not automatically excluded as cloud-provider time.Example: two receivers see the same candidate
Two receivers discover a message. The adapter must use a conditional update to assign the message to a receiver under the documented queue rules. It must not give both receivers conflicting ownership just to meet a latency target. Record the claim outcomes and native conditional responses, along with local retries and scheduling. A later redelivery after visibility expires can be legitimate. It is different from simultaneous ownership caused by a broken claim. Inspect receipt timing and the selected queue semantics before calling either event data loss or a duplicate-delivery defect.Example: restart during a dead-letter transition
A message is copied to the dead-letter queue, then the process restarts before removing the source copy. Recovery must preserve the supported message semantics without adapter-induced loss. A valid redelivery is not the same as a missing accepted message. Preserve source and destination observations and identifiers before changing either queue. Do not delete both copies to make the counts agree, and do not replay a send solely to generate an Explain report. If Cosmos DB also reports throttling, investigate serverless/partition pressure and the adapter’s call/retry pattern. Backend throttling does not excuse an incorrect recovery algorithm or excessive local retries.Evidence for support
Record Standard versus FIFO, group distribution, message and attribute sizes, conditional-claim outcomes, wait/visibility settings, dead-letter configuration and the affected time window. Include native request IDs, request-unit/throttling observations and available adapter timing. Keep sensitive bodies and receipt handles out of shared reports. You can contact support before you know what caused the problem.SQS (Simple Queue Service, Classic) to PostgreSQL Flexible Server
What this adapter does
Forazure::1.0.0::postgresql::flexible, The SQL queue uses row locking and SKIP LOCKED; FIFO adds head-of-group selection and deduplication state. The current long-poll loop can sleep between polls. Queue configuration is cached and durable queue state remains in PostgreSQL. A ReceiveMessage response budget is not a delivery-time promise: messages may not yet exist, may be delayed, or may be blocked by a FIFO group head. The short-poll row deliberately removes that ambiguity. Requested long-poll waits need their own measurement treatment in the agreement.
How the latency targets were chosen
Small message send and settlement: +3 ms monthly p99 (adapter-added).ChangeMessageVisibility, DeleteMessage, SendMessage. Native forwarding needs bounded translation; SQL adds queue state; Cosmos FIFO requires multiple durable coordination steps and cannot honestly inherit a 1 ms forwarding budget.
Bounded short-poll receive: +10 ms monthly p99 (adapter-added). ReceiveMessage. Receive scans/selects candidates, claims visibility and creates receipt handles. FIFO head selection and Cosmos slot CAS cost more than a simple send.
Bounded message batches: +30 ms monthly p99 (adapter-added). DeleteMessageBatch, SendMessageBatch. A conservative upper budget for up to ten point paths plus aggregation. It does not assume the implementation parallelizes all target or metadata work.
Queue configuration and discovery: +20 ms monthly p99 (adapter-added). GetQueueAttributes, GetQueueUrl. Queue identity, attributes, tags and counts can use the adapter’s durable catalog; this is not excluded as target message work.
Your signed agreement sets the terms for your deployment. A target does not add an operation or option that the compatibility tables mark unavailable.
What counts toward latency
For a request-response row, measure from the agreed ingress boundary to dispatch of the complete response. A row that explicitly names a first response chunk ends at that chunk; its number does not cover the rest of the stream. A long-poll row names the intentional wait and when adapter delay starts. Include parsing, authorization, admission, translation, serialization, adapter-owned storage and coordination, retries and response handling. Subtract only separately measured target-workload waits and external network segments allowed by the measurement rules. The adapter’s own response handling and dispatch remain covered. A database used for adapter metadata is still adapter work, even if a cloud provider hosts it. For concurrent calls, exclude the union of permitted wait intervals, not the sum of overlapping spans. Calculate each request’s adapter duration first, then the monthly p99. Do not subtract one service’s p99 from another’s. Known adapter timeouts are over-budget samples; failed or incomplete requests cannot disappear to improve the percentile. Missing measurements do not become zero latency. An SDK call span alone does not prove how much of its duration can be excluded.Endpoint reachability and request failures
The endpoint-reachability target measures adapter health checks. Correctly forwarding a target quota or permission error is different from producing that error because the adapter sent the wrong request. Adapter-caused failures remain Tensor9’s responsibility even when the target is healthy. Correctness and data-integrity requirements apply to every supported request. Endpoint reachability does not measure request correctness or grant an allowance for incorrect results.Scaling and target-service capacity
Scale send, receive and settle capacity together, and track in-flight messages, pollers, candidate scans and FIFO group skew. Adding replicas helps independent groups but cannot parallelize the ordered head of one group. The agreement caps active pollers, groups inspected per receive, message bytes, retry amplification and batch entries. Tensor9 scales the fabric within those limits; the customer supplies sufficient broker capacity, Cosmos RU/s or PostgreSQL connections and I/O. Tell Tensor9 the expected steady rate, bursts, concurrency, payload sizes and operation mix. Tensor9 sizes and scales the adapter for the agreed load; you choose and monitor the target service’s capacity with Tensor9’s help. A latency budget is not a requests-per-second rating. Larger requests and higher rates need explicit terms, not silent inheritance of a small-request SLA.Data and behavior guarantees
Acceptance must not be returned before the documented message persistence point. Settlement must apply to the intended message/receipt; FIFO order and deduplication apply only where this directed profile supports them. Duplicate delivery can be legitimate under at-least-once delivery. Dead-letter transitions must not silently discard an accepted message. Durability of the target broker/database remains its own commitment, while broken adapter receipt, marker or coordination logic remains Tensor9’s responsibility.Example and diagnosis
Fororder-events, send a 2 KiB message, receive up to ten messages with WaitTimeSeconds=0, then settle each receipt. For a FIFO queue, distribute independent customers across groups instead of expecting one group to scale with replicas. If native message writes are fast but Cosmos FIFO sends slow down, inspect counter/dedup contention: those coordination waits still count against Tensor9’s fabric budget.
Use tensor9 explain and the documented explain headers to understand the selected adapter and its behavior. Correlate available request diagnostics with the target provider’s latency, throttling and capacity metrics. An explain report helps diagnose a request; it is not by itself a qualified SLA timing measurement. Share the operation, request shape, timestamps and request identifiers with support, with credentials and customer payloads removed.
SQS (Simple Queue Service, Classic) to Azure Queue Storage
What this adapter does
Forazure::1.0.0::queue-storage, The adapter maps message bodies, attributes, receipts and settlement onto the native queue API. Supported delay, long-polling, retention and redrive behavior is target-specific; API translation does not turn a standard queue into FIFO. A ReceiveMessage response budget is not a delivery-time promise: messages may not yet exist, may be delayed, or may be blocked by a FIFO group head. The short-poll row deliberately removes that ambiguity. Requested long-poll waits need their own measurement treatment in the agreement.
How the latency targets were chosen
Small message send and settlement: +1 ms monthly p99 (adapter-added).ChangeMessageVisibility, DeleteMessage, SendMessage. Native forwarding needs bounded translation; SQL adds queue state; Cosmos FIFO requires multiple durable coordination steps and cannot honestly inherit a 1 ms forwarding budget.
Bounded short-poll receive: +3 ms monthly p99 (adapter-added). ReceiveMessage. Receive scans/selects candidates, claims visibility and creates receipt handles. FIFO head selection and Cosmos slot CAS cost more than a simple send.
Bounded message batches: +10 ms monthly p99 (adapter-added). ChangeMessageVisibilityBatch, DeleteMessageBatch, SendMessageBatch. A conservative upper budget for up to ten point paths plus aggregation. It does not assume the implementation parallelizes all target or metadata work.
Queue configuration and discovery: +20 ms monthly p99 (adapter-added). CreateQueue, DeleteQueue, ListQueueTags, ListQueues, PurgeQueue, SetQueueAttributes, TagQueue, UntagQueue. Queue identity, attributes, tags and counts can use the adapter’s durable catalog; this is not excluded as target message work.
Your signed agreement sets the terms for your deployment. A target does not add an operation or option that the compatibility tables mark unavailable.
What counts toward latency
For a request-response row, measure from the agreed ingress boundary to dispatch of the complete response. A row that explicitly names a first response chunk ends at that chunk; its number does not cover the rest of the stream. A long-poll row names the intentional wait and when adapter delay starts. Include parsing, authorization, admission, translation, serialization, adapter-owned storage and coordination, retries and response handling. Subtract only separately measured target-workload waits and external network segments allowed by the measurement rules. The adapter’s own response handling and dispatch remain covered. A database used for adapter metadata is still adapter work, even if a cloud provider hosts it. For concurrent calls, exclude the union of permitted wait intervals, not the sum of overlapping spans. Calculate each request’s adapter duration first, then the monthly p99. Do not subtract one service’s p99 from another’s. Known adapter timeouts are over-budget samples; failed or incomplete requests cannot disappear to improve the percentile. Missing measurements do not become zero latency. An SDK call span alone does not prove how much of its duration can be excluded.Endpoint reachability and request failures
The endpoint-reachability target measures adapter health checks. Correctly forwarding a target quota or permission error is different from producing that error because the adapter sent the wrong request. Adapter-caused failures remain Tensor9’s responsibility even when the target is healthy. Correctness and data-integrity requirements apply to every supported request. Endpoint reachability does not measure request correctness or grant an allowance for incorrect results.Scaling and target-service capacity
Scale send, receive and settle capacity together, and track in-flight messages, pollers, candidate scans and FIFO group skew. Adding replicas helps independent groups but cannot parallelize the ordered head of one group. The agreement caps active pollers, groups inspected per receive, message bytes, retry amplification and batch entries. Tensor9 scales the fabric within those limits; the customer supplies sufficient broker capacity, Cosmos RU/s or PostgreSQL connections and I/O. Tell Tensor9 the expected steady rate, bursts, concurrency, payload sizes and operation mix. Tensor9 sizes and scales the adapter for the agreed load; you choose and monitor the target service’s capacity with Tensor9’s help. A latency budget is not a requests-per-second rating. Larger requests and higher rates need explicit terms, not silent inheritance of a small-request SLA.Data and behavior guarantees
Acceptance must not be returned before the documented message persistence point. Settlement must apply to the intended message/receipt; FIFO order and deduplication apply only where this directed profile supports them. Duplicate delivery can be legitimate under at-least-once delivery. Dead-letter transitions must not silently discard an accepted message. Durability of the target broker/database remains its own commitment, while broken adapter receipt, marker or coordination logic remains Tensor9’s responsibility.Example and diagnosis
Fororder-events, send a 2 KiB message, receive up to ten messages with WaitTimeSeconds=0, then settle each receipt. For a FIFO queue, distribute independent customers across groups instead of expecting one group to scale with replicas. If native message writes are fast but Cosmos FIFO sends slow down, inspect counter/dedup contention: those coordination waits still count against Tensor9’s fabric budget.
Use tensor9 explain and the documented explain headers to understand the selected adapter and its behavior. Correlate available request diagnostics with the target provider’s latency, throttling and capacity metrics. An explain report helps diagnose a request; it is not by itself a qualified SLA timing measurement. Share the operation, request shape, timestamps and request identifiers with support, with credentials and customer payloads removed.
SQS (Simple Queue Service, Classic) to Azure Service Bus
What this adapter does
Forazure::1.0.0::servicebus, Service Bus messages and locks implement queue delivery; FIFO uses sessions. Lock renewal, receipt mapping and settlement remain adapter responsibilities, while native broker delivery uses the target service. A ReceiveMessage response budget is not a delivery-time promise: messages may not yet exist, may be delayed, or may be blocked by a FIFO group head. The short-poll row deliberately removes that ambiguity. Requested long-poll waits need their own measurement treatment in the agreement.
How the latency targets were chosen
Small message send and settlement: +1 ms monthly p99 (adapter-added).ChangeMessageVisibility, DeleteMessage, SendMessage. Native forwarding needs bounded translation; SQL adds queue state; Cosmos FIFO requires multiple durable coordination steps and cannot honestly inherit a 1 ms forwarding budget.
Bounded short-poll receive: +3 ms monthly p99 (adapter-added). ReceiveMessage. Receive scans/selects candidates, claims visibility and creates receipt handles. FIFO head selection and Cosmos slot CAS cost more than a simple send.
Bounded message batches: +10 ms monthly p99 (adapter-added). SendMessageBatch. A conservative upper budget for up to ten point paths plus aggregation. It does not assume the implementation parallelizes all target or metadata work.
Queue configuration and discovery: +20 ms monthly p99 (adapter-added). DeleteQueue, ListQueueTags, ListQueues, SetQueueAttributes, TagQueue, UntagQueue. Queue identity, attributes, tags and counts can use the adapter’s durable catalog; this is not excluded as target message work.
Your signed agreement sets the terms for your deployment. A target does not add an operation or option that the compatibility tables mark unavailable.
What counts toward latency
For a request-response row, measure from the agreed ingress boundary to dispatch of the complete response. A row that explicitly names a first response chunk ends at that chunk; its number does not cover the rest of the stream. A long-poll row names the intentional wait and when adapter delay starts. Include parsing, authorization, admission, translation, serialization, adapter-owned storage and coordination, retries and response handling. Subtract only separately measured target-workload waits and external network segments allowed by the measurement rules. The adapter’s own response handling and dispatch remain covered. A database used for adapter metadata is still adapter work, even if a cloud provider hosts it. For concurrent calls, exclude the union of permitted wait intervals, not the sum of overlapping spans. Calculate each request’s adapter duration first, then the monthly p99. Do not subtract one service’s p99 from another’s. Known adapter timeouts are over-budget samples; failed or incomplete requests cannot disappear to improve the percentile. Missing measurements do not become zero latency. An SDK call span alone does not prove how much of its duration can be excluded.Endpoint reachability and request failures
The endpoint-reachability target measures adapter health checks. Correctly forwarding a target quota or permission error is different from producing that error because the adapter sent the wrong request. Adapter-caused failures remain Tensor9’s responsibility even when the target is healthy. Correctness and data-integrity requirements apply to every supported request. Endpoint reachability does not measure request correctness or grant an allowance for incorrect results.Scaling and target-service capacity
Scale send, receive and settle capacity together, and track in-flight messages, pollers, candidate scans and FIFO group skew. Adding replicas helps independent groups but cannot parallelize the ordered head of one group. The agreement caps active pollers, groups inspected per receive, message bytes, retry amplification and batch entries. Tensor9 scales the fabric within those limits; the customer supplies sufficient broker capacity, Cosmos RU/s or PostgreSQL connections and I/O. Tell Tensor9 the expected steady rate, bursts, concurrency, payload sizes and operation mix. Tensor9 sizes and scales the adapter for the agreed load; you choose and monitor the target service’s capacity with Tensor9’s help. A latency budget is not a requests-per-second rating. Larger requests and higher rates need explicit terms, not silent inheritance of a small-request SLA.Data and behavior guarantees
Acceptance must not be returned before the documented message persistence point. Settlement must apply to the intended message/receipt; FIFO order and deduplication apply only where this directed profile supports them. Duplicate delivery can be legitimate under at-least-once delivery. Dead-letter transitions must not silently discard an accepted message. Durability of the target broker/database remains its own commitment, while broken adapter receipt, marker or coordination logic remains Tensor9’s responsibility.Example and diagnosis
Fororder-events, send a 2 KiB message, receive up to ten messages with WaitTimeSeconds=0, then settle each receipt. For a FIFO queue, distribute independent customers across groups instead of expecting one group to scale with replicas. If native message writes are fast but Cosmos FIFO sends slow down, inspect counter/dedup contention: those coordination waits still count against Tensor9’s fabric budget.
Use tensor9 explain and the documented explain headers to understand the selected adapter and its behavior. Correlate available request diagnostics with the target provider’s latency, throttling and capacity metrics. An explain report helps diagnose a request; it is not by itself a qualified SLA timing measurement. Share the operation, request shape, timestamps and request identifiers with support, with credentials and customer payloads removed.
SQS to Cloud SQL for PostgreSQL
Why these latency targets differ
The shared Standard/FIFO point-operation target stays at 10 ms. A FIFO request can perform durable deduplication and group coordination, so reducing the target to 1 ms would ignore real adapter work. A batch of up to ten entries has a 100 ms budget; this allows sequential per-entry coordination rather than assuming every batch path runs in parallel. Latency targets do not imply a throughput guarantee or favor this backend over another. Ready-message pickup and delay after the requested wait retain their 250 ms targets. The PostgreSQL backend currently polls with sleeps of up to 100 ms between checks. Sleep after a message becomes eligible counts as adapter delay; it is not Cloud SQL execution time. A future notification-driven implementation could support a lower pickup target, but request parsing alone cannot justify one today.Adapter and scope
Receive timing
Two phases ofReceiveMessage have separate measurements:
- Ready-message pickup: time from a message becoming available to a waiting receiver until the adapter sends the response. Only separately measured time spent waiting for the backend service is excluded.
- Delay after the requested wait: extra adapter time after the requested wait for a message has ended.
Message guarantees
A send can return success only after the message state has been durably saved. A deduplication marker alone must not produce success for a message that was never committed. The adapter must use the same record of accepted messages when returning success, checking for duplicates, and recovering from a crash. Standard queues can redeliver messages. FIFO preserves the profile’s per-group ordering and supported deduplication behavior; it does not promise global order across groups or exactly-once effects in your application. A consumer can perform a business action and fail before deleting the message, so application-side idempotency still matters. The adapter follows its documented rules for visibility, expiration, message deletion, and movement to a dead-letter queue. Successfully completed changes must survive the process failures covered by the agreement. An expired receipt handle produces the result documented for that adapter; different backends need not return the same error. Approximate queue counts help with troubleshooting but are not guaranteed to show the exact current queue depth.Useful throughput
Count completed API calls separately from message work. A valid emptyReceiveMessage completes an API call but delivers no message. One successful send, nonempty receive and delete form a message lifecycle involving at least three API calls. Redelivery and internal retries must not inflate the count of distinct messages processed.
Measure Standard and FIFO separately. FIFO group distribution, time between receive and delete, visibility timeout, delayed messages and dead-letter traffic change the scaling limit. A large number of consumers cannot make a single serialized group behave like many independent groups.
These standard service levels do not reserve a fixed message rate or specify a maximum throughput. Tensor9 and the customer must agree on limits for the actual workload and production deployment, including how quickly traffic can grow and how large a burst can be. Autoscaling is intended to maintain the stated latency and endpoint reachability within those limits. It cannot remove ordering requirements or backend-service limits.
Operation terms
The listed operations retain their documented behavior with the request options supported by the adapter. The 1 KiB limits apply to the latency target. Supported larger messages have no numerical request-latency target under these standard terms. Queue management, tagging, approximate-count reads andChangeMessageVisibilityBatch have no numerical SLA under these standard terms. That does not declare them unsupported. Check the adapter’s support details separately. A similar operation name does not make an operation covered by the SLA.
For batch calls, retain per-entry successes and failures. The response to a partial batch is not evidence that every submitted message completed successfully.
Scaling on Cloud SQL
Connection budgets, transaction/lock contention and message claims can limit the adapter before the database reaches its advertised compute capacity. A pool limit configured independently on every replica can exceed the database’s total allowance during scale-out or rollout. Limit total database connections across all adapter instances, including instances that are starting or shutting down. Review query work and lock contention alongside Cloud SQL CPU, storage and connection metrics. Native database execution is separately timed, but acquiring a local connection and scheduling local polling remain adapter work. Independent messages and FIFO groups offer parallel work. A hot group still requires ordered progress. Adding adapter instances must not make competing claims or repeated retries appear to be more successfully processed messages.Example: an empty long poll receives a job
Thejobs queue has an outstanding 20-second ReceiveMessage. Ten seconds later, a message becomes eligible for that receiver. The first ten seconds are legitimate waiting. Measure the subsequent local polling, claim scheduling and response handling against pickup conditions, with native execution recorded separately.
If no message becomes eligible, measure the adapter delay after the requested 20-second deadline instead. Do not compare the entire long poll with the receive processing budget, and do not use approximate queue depth to infer the exact eligibility timestamp.
Example: a committed send loses its response
PostgreSQL commits a message, then the adapter restarts before returning success. The response-path failure remains an adapter failure even though the message exists. The caller’s outcome is uncertain. Inspect the observed state and supported deduplication behavior before retrying. Standard-queue redelivery remains possible. If recovery leaks connections or fails to restore message state, that is not excluded merely because a managed database holds the data. A Cloud SQL outage not caused by the adapter is outside the standard adapter SLA. Tensor9 still helps investigate recovery and backlog behavior. Excessive retries or broken connection recovery remain adapter issues.Evidence for support
Keep the queue type, operation, message-size range, batch outcomes, active FIFO group distribution, wait/visibility settings, time between receiving and deleting a message and relevant request IDs. Include Cloud SQL connections, contention and backend timing for the same interval. Redact message bodies and receipt handles before sharing. An available Explain report supplements these observations; its absence does not prevent support.SQS (Simple Queue Service, Classic) to Pub/Sub
What this adapter does
Forgoogle::1.0.0::pubsub, The adapter maps message bodies, attributes, receipts and settlement onto the native queue API. Supported delay, long-polling, retention and redrive behavior is target-specific; API translation does not turn a standard queue into FIFO. A ReceiveMessage response budget is not a delivery-time promise: messages may not yet exist, may be delayed, or may be blocked by a FIFO group head. The short-poll row deliberately removes that ambiguity. Requested long-poll waits need their own measurement treatment in the agreement.
How the latency targets were chosen
Small message send and settlement: +1 ms monthly p99 (adapter-added).ChangeMessageVisibility, DeleteMessage, SendMessage. Native forwarding needs bounded translation; SQL adds queue state; Cosmos FIFO requires multiple durable coordination steps and cannot honestly inherit a 1 ms forwarding budget.
Bounded short-poll receive: +3 ms monthly p99 (adapter-added). ReceiveMessage. Receive scans/selects candidates, claims visibility and creates receipt handles. FIFO head selection and Cosmos slot CAS cost more than a simple send.
Queue configuration and discovery: +20 ms monthly p99 (adapter-added). SetQueueAttributes. Queue identity, attributes, tags and counts can use the adapter’s durable catalog; this is not excluded as target message work.
Your signed agreement sets the terms for your deployment. A target does not add an operation or option that the compatibility tables mark unavailable.
What counts toward latency
For a request-response row, measure from the agreed ingress boundary to dispatch of the complete response. A row that explicitly names a first response chunk ends at that chunk; its number does not cover the rest of the stream. A long-poll row names the intentional wait and when adapter delay starts. Include parsing, authorization, admission, translation, serialization, adapter-owned storage and coordination, retries and response handling. Subtract only separately measured target-workload waits and external network segments allowed by the measurement rules. The adapter’s own response handling and dispatch remain covered. A database used for adapter metadata is still adapter work, even if a cloud provider hosts it. For concurrent calls, exclude the union of permitted wait intervals, not the sum of overlapping spans. Calculate each request’s adapter duration first, then the monthly p99. Do not subtract one service’s p99 from another’s. Known adapter timeouts are over-budget samples; failed or incomplete requests cannot disappear to improve the percentile. Missing measurements do not become zero latency. An SDK call span alone does not prove how much of its duration can be excluded.Endpoint reachability and request failures
The endpoint-reachability target measures adapter health checks. Correctly forwarding a target quota or permission error is different from producing that error because the adapter sent the wrong request. Adapter-caused failures remain Tensor9’s responsibility even when the target is healthy. Correctness and data-integrity requirements apply to every supported request. Endpoint reachability does not measure request correctness or grant an allowance for incorrect results.Scaling and target-service capacity
Scale send, receive and settle capacity together, and track in-flight messages, pollers, candidate scans and FIFO group skew. Adding replicas helps independent groups but cannot parallelize the ordered head of one group. The agreement caps active pollers, groups inspected per receive, message bytes, retry amplification and batch entries. Tensor9 scales the fabric within those limits; the customer supplies sufficient broker capacity, Cosmos RU/s or PostgreSQL connections and I/O. Tell Tensor9 the expected steady rate, bursts, concurrency, payload sizes and operation mix. Tensor9 sizes and scales the adapter for the agreed load; you choose and monitor the target service’s capacity with Tensor9’s help. A latency budget is not a requests-per-second rating. Larger requests and higher rates need explicit terms, not silent inheritance of a small-request SLA.Data and behavior guarantees
Acceptance must not be returned before the documented message persistence point. Settlement must apply to the intended message/receipt; FIFO order and deduplication apply only where this directed profile supports them. Duplicate delivery can be legitimate under at-least-once delivery. Dead-letter transitions must not silently discard an accepted message. Durability of the target broker/database remains its own commitment, while broken adapter receipt, marker or coordination logic remains Tensor9’s responsibility.Example and diagnosis
Fororder-events, send a 2 KiB message, receive up to ten messages with WaitTimeSeconds=0, then settle each receipt. For a FIFO queue, distribute independent customers across groups instead of expecting one group to scale with replicas. If native message writes are fast but Cosmos FIFO sends slow down, inspect counter/dedup contention: those coordination waits still count against Tensor9’s fabric budget.
Use tensor9 explain and the documented explain headers to understand the selected adapter and its behavior. Correlate available request diagnostics with the target provider’s latency, throttling and capacity metrics. An explain report helps diagnose a request; it is not by itself a qualified SLA timing measurement. Share the operation, request shape, timestamps and request identifiers with support, with credentials and customer payloads removed.
SQS (Simple Queue Service, Classic) to OCI Queue
What this adapter does
Foroci::1.0.0::queue, The adapter maps message bodies, attributes, receipts and settlement onto the native queue API. Supported delay, long-polling, retention and redrive behavior is target-specific; API translation does not turn a standard queue into FIFO. A ReceiveMessage response budget is not a delivery-time promise: messages may not yet exist, may be delayed, or may be blocked by a FIFO group head. The short-poll row deliberately removes that ambiguity. Requested long-poll waits need their own measurement treatment in the agreement.
How the latency targets were chosen
Small message send and settlement: +1 ms monthly p99 (adapter-added).ChangeMessageVisibility, DeleteMessage, SendMessage. Native forwarding needs bounded translation; SQL adds queue state; Cosmos FIFO requires multiple durable coordination steps and cannot honestly inherit a 1 ms forwarding budget.
Bounded short-poll receive: +3 ms monthly p99 (adapter-added). ReceiveMessage. Receive scans/selects candidates, claims visibility and creates receipt handles. FIFO head selection and Cosmos slot CAS cost more than a simple send.
Queue configuration and discovery: +20 ms monthly p99 (adapter-added). SetQueueAttributes. Queue identity, attributes, tags and counts can use the adapter’s durable catalog; this is not excluded as target message work.
Your signed agreement sets the terms for your deployment. A target does not add an operation or option that the compatibility tables mark unavailable.
What counts toward latency
For a request-response row, measure from the agreed ingress boundary to dispatch of the complete response. A row that explicitly names a first response chunk ends at that chunk; its number does not cover the rest of the stream. A long-poll row names the intentional wait and when adapter delay starts. Include parsing, authorization, admission, translation, serialization, adapter-owned storage and coordination, retries and response handling. Subtract only separately measured target-workload waits and external network segments allowed by the measurement rules. The adapter’s own response handling and dispatch remain covered. A database used for adapter metadata is still adapter work, even if a cloud provider hosts it. For concurrent calls, exclude the union of permitted wait intervals, not the sum of overlapping spans. Calculate each request’s adapter duration first, then the monthly p99. Do not subtract one service’s p99 from another’s. Known adapter timeouts are over-budget samples; failed or incomplete requests cannot disappear to improve the percentile. Missing measurements do not become zero latency. An SDK call span alone does not prove how much of its duration can be excluded.Endpoint reachability and request failures
The endpoint-reachability target measures adapter health checks. Correctly forwarding a target quota or permission error is different from producing that error because the adapter sent the wrong request. Adapter-caused failures remain Tensor9’s responsibility even when the target is healthy. Correctness and data-integrity requirements apply to every supported request. Endpoint reachability does not measure request correctness or grant an allowance for incorrect results.Scaling and target-service capacity
Scale send, receive and settle capacity together, and track in-flight messages, pollers, candidate scans and FIFO group skew. Adding replicas helps independent groups but cannot parallelize the ordered head of one group. The agreement caps active pollers, groups inspected per receive, message bytes, retry amplification and batch entries. Tensor9 scales the fabric within those limits; the customer supplies sufficient broker capacity, Cosmos RU/s or PostgreSQL connections and I/O. Tell Tensor9 the expected steady rate, bursts, concurrency, payload sizes and operation mix. Tensor9 sizes and scales the adapter for the agreed load; you choose and monitor the target service’s capacity with Tensor9’s help. A latency budget is not a requests-per-second rating. Larger requests and higher rates need explicit terms, not silent inheritance of a small-request SLA.Data and behavior guarantees
Acceptance must not be returned before the documented message persistence point. Settlement must apply to the intended message/receipt; FIFO order and deduplication apply only where this directed profile supports them. Duplicate delivery can be legitimate under at-least-once delivery. Dead-letter transitions must not silently discard an accepted message. Durability of the target broker/database remains its own commitment, while broken adapter receipt, marker or coordination logic remains Tensor9’s responsibility.Example and diagnosis
Fororder-events, send a 2 KiB message, receive up to ten messages with WaitTimeSeconds=0, then settle each receipt. For a FIFO queue, distribute independent customers across groups instead of expecting one group to scale with replicas. If native message writes are fast but Cosmos FIFO sends slow down, inspect counter/dedup contention: those coordination waits still count against Tensor9’s fabric budget.
Use tensor9 explain and the documented explain headers to understand the selected adapter and its behavior. Correlate available request diagnostics with the target provider’s latency, throttling and capacity metrics. An explain report helps diagnose a request; it is not by itself a qualified SLA timing measurement. Share the operation, request shape, timestamps and request identifiers with support, with credentials and customer payloads removed.
SQS (Simple Queue Service, Classic) to PostgreSQL
What this adapter does
Forpostgres::1.0.0::database, The SQL queue uses row locking and SKIP LOCKED; FIFO adds head-of-group selection and deduplication state. The current long-poll loop can sleep between polls. Queue configuration is cached and durable queue state remains in PostgreSQL. A ReceiveMessage response budget is not a delivery-time promise: messages may not yet exist, may be delayed, or may be blocked by a FIFO group head. The short-poll row deliberately removes that ambiguity. Requested long-poll waits need their own measurement treatment in the agreement.
How the latency targets were chosen
Small message send and settlement: +3 ms monthly p99 (adapter-added).ChangeMessageVisibility, DeleteMessage, SendMessage. Native forwarding needs bounded translation; SQL adds queue state; Cosmos FIFO requires multiple durable coordination steps and cannot honestly inherit a 1 ms forwarding budget.
Bounded short-poll receive: +10 ms monthly p99 (adapter-added). ReceiveMessage. Receive scans/selects candidates, claims visibility and creates receipt handles. FIFO head selection and Cosmos slot CAS cost more than a simple send.
Bounded message batches: +30 ms monthly p99 (adapter-added). DeleteMessageBatch, SendMessageBatch. A conservative upper budget for up to ten point paths plus aggregation. It does not assume the implementation parallelizes all target or metadata work.
Queue configuration and discovery: +20 ms monthly p99 (adapter-added). GetQueueAttributes, GetQueueUrl. Queue identity, attributes, tags and counts can use the adapter’s durable catalog; this is not excluded as target message work.
Your signed agreement sets the terms for your deployment. A target does not add an operation or option that the compatibility tables mark unavailable.
What counts toward latency
For a request-response row, measure from the agreed ingress boundary to dispatch of the complete response. A row that explicitly names a first response chunk ends at that chunk; its number does not cover the rest of the stream. A long-poll row names the intentional wait and when adapter delay starts. Include parsing, authorization, admission, translation, serialization, adapter-owned storage and coordination, retries and response handling. Subtract only separately measured target-workload waits and external network segments allowed by the measurement rules. The adapter’s own response handling and dispatch remain covered. A database used for adapter metadata is still adapter work, even if a cloud provider hosts it. For concurrent calls, exclude the union of permitted wait intervals, not the sum of overlapping spans. Calculate each request’s adapter duration first, then the monthly p99. Do not subtract one service’s p99 from another’s. Known adapter timeouts are over-budget samples; failed or incomplete requests cannot disappear to improve the percentile. Missing measurements do not become zero latency. An SDK call span alone does not prove how much of its duration can be excluded.Endpoint reachability and request failures
The endpoint-reachability target measures adapter health checks. Correctly forwarding a target quota or permission error is different from producing that error because the adapter sent the wrong request. Adapter-caused failures remain Tensor9’s responsibility even when the target is healthy. Correctness and data-integrity requirements apply to every supported request. Endpoint reachability does not measure request correctness or grant an allowance for incorrect results.Scaling and target-service capacity
Scale send, receive and settle capacity together, and track in-flight messages, pollers, candidate scans and FIFO group skew. Adding replicas helps independent groups but cannot parallelize the ordered head of one group. The agreement caps active pollers, groups inspected per receive, message bytes, retry amplification and batch entries. Tensor9 scales the fabric within those limits; the customer supplies sufficient broker capacity, Cosmos RU/s or PostgreSQL connections and I/O. Tell Tensor9 the expected steady rate, bursts, concurrency, payload sizes and operation mix. Tensor9 sizes and scales the adapter for the agreed load; you choose and monitor the target service’s capacity with Tensor9’s help. A latency budget is not a requests-per-second rating. Larger requests and higher rates need explicit terms, not silent inheritance of a small-request SLA.Data and behavior guarantees
Acceptance must not be returned before the documented message persistence point. Settlement must apply to the intended message/receipt; FIFO order and deduplication apply only where this directed profile supports them. Duplicate delivery can be legitimate under at-least-once delivery. Dead-letter transitions must not silently discard an accepted message. Durability of the target broker/database remains its own commitment, while broken adapter receipt, marker or coordination logic remains Tensor9’s responsibility.Example and diagnosis
Fororder-events, send a 2 KiB message, receive up to ten messages with WaitTimeSeconds=0, then settle each receipt. For a FIFO queue, distribute independent customers across groups instead of expecting one group to scale with replicas. If native message writes are fast but Cosmos FIFO sends slow down, inspect counter/dedup contention: those coordination waits still count against Tensor9’s fabric budget.
Use tensor9 explain and the documented explain headers to understand the selected adapter and its behavior. Correlate available request diagnostics with the target provider’s latency, throttling and capacity metrics. An explain report helps diagnose a request; it is not by itself a qualified SLA timing measurement. Share the operation, request shape, timestamps and request identifiers with support, with credentials and customer payloads removed.
SQS (Simple Queue Service, Classic) to Scaleway Queues (SQS-compatible)
What this adapter does
Forscaleway::1.0.0::queues, The adapter maps message bodies, attributes, receipts and settlement onto the native queue API. Supported delay, long-polling, retention and redrive behavior is target-specific; API translation does not turn a standard queue into FIFO. A ReceiveMessage response budget is not a delivery-time promise: messages may not yet exist, may be delayed, or may be blocked by a FIFO group head. The short-poll row deliberately removes that ambiguity. Requested long-poll waits need their own measurement treatment in the agreement.
How the latency targets were chosen
Small message send and settlement: +1 ms monthly p99 (adapter-added).ChangeMessageVisibility, DeleteMessage, SendMessage. Native forwarding needs bounded translation; SQL adds queue state; Cosmos FIFO requires multiple durable coordination steps and cannot honestly inherit a 1 ms forwarding budget.
Bounded short-poll receive: +3 ms monthly p99 (adapter-added). ReceiveMessage. Receive scans/selects candidates, claims visibility and creates receipt handles. FIFO head selection and Cosmos slot CAS cost more than a simple send.
Queue configuration and discovery: +20 ms monthly p99 (adapter-added). GetQueueAttributes, SetQueueAttributes. Queue identity, attributes, tags and counts can use the adapter’s durable catalog; this is not excluded as target message work.
Your signed agreement sets the terms for your deployment. A target does not add an operation or option that the compatibility tables mark unavailable.
What counts toward latency
For a request-response row, measure from the agreed ingress boundary to dispatch of the complete response. A row that explicitly names a first response chunk ends at that chunk; its number does not cover the rest of the stream. A long-poll row names the intentional wait and when adapter delay starts. Include parsing, authorization, admission, translation, serialization, adapter-owned storage and coordination, retries and response handling. Subtract only separately measured target-workload waits and external network segments allowed by the measurement rules. The adapter’s own response handling and dispatch remain covered. A database used for adapter metadata is still adapter work, even if a cloud provider hosts it. For concurrent calls, exclude the union of permitted wait intervals, not the sum of overlapping spans. Calculate each request’s adapter duration first, then the monthly p99. Do not subtract one service’s p99 from another’s. Known adapter timeouts are over-budget samples; failed or incomplete requests cannot disappear to improve the percentile. Missing measurements do not become zero latency. An SDK call span alone does not prove how much of its duration can be excluded.Endpoint reachability and request failures
The endpoint-reachability target measures adapter health checks. Correctly forwarding a target quota or permission error is different from producing that error because the adapter sent the wrong request. Adapter-caused failures remain Tensor9’s responsibility even when the target is healthy. Correctness and data-integrity requirements apply to every supported request. Endpoint reachability does not measure request correctness or grant an allowance for incorrect results.Scaling and target-service capacity
Scale send, receive and settle capacity together, and track in-flight messages, pollers, candidate scans and FIFO group skew. Adding replicas helps independent groups but cannot parallelize the ordered head of one group. The agreement caps active pollers, groups inspected per receive, message bytes, retry amplification and batch entries. Tensor9 scales the fabric within those limits; the customer supplies sufficient broker capacity, Cosmos RU/s or PostgreSQL connections and I/O. Tell Tensor9 the expected steady rate, bursts, concurrency, payload sizes and operation mix. Tensor9 sizes and scales the adapter for the agreed load; you choose and monitor the target service’s capacity with Tensor9’s help. A latency budget is not a requests-per-second rating. Larger requests and higher rates need explicit terms, not silent inheritance of a small-request SLA.Data and behavior guarantees
Acceptance must not be returned before the documented message persistence point. Settlement must apply to the intended message/receipt; FIFO order and deduplication apply only where this directed profile supports them. Duplicate delivery can be legitimate under at-least-once delivery. Dead-letter transitions must not silently discard an accepted message. Durability of the target broker/database remains its own commitment, while broken adapter receipt, marker or coordination logic remains Tensor9’s responsibility.Example and diagnosis
Fororder-events, send a 2 KiB message, receive up to ten messages with WaitTimeSeconds=0, then settle each receipt. For a FIFO queue, distribute independent customers across groups instead of expecting one group to scale with replicas. If native message writes are fast but Cosmos FIFO sends slow down, inspect counter/dedup contention: those coordination waits still count against Tensor9’s fabric budget.
Use tensor9 explain and the documented explain headers to understand the selected adapter and its behavior. Correlate available request diagnostics with the target provider’s latency, throttling and capacity metrics. An explain report helps diagnose a request; it is not by itself a qualified SLA timing measurement. Share the operation, request shape, timestamps and request identifiers with support, with credentials and customer payloads removed.
SQS (Simple Queue Service, Classic) to Scaleway Managed Database for PostgreSQL
What this adapter does
Forscaleway::1.0.0::rdb::postgresql, The SQL queue uses row locking and SKIP LOCKED; FIFO adds head-of-group selection and deduplication state. The current long-poll loop can sleep between polls. Queue configuration is cached and durable queue state remains in PostgreSQL. A ReceiveMessage response budget is not a delivery-time promise: messages may not yet exist, may be delayed, or may be blocked by a FIFO group head. The short-poll row deliberately removes that ambiguity. Requested long-poll waits need their own measurement treatment in the agreement.
How the latency targets were chosen
Small message send and settlement: +3 ms monthly p99 (adapter-added).ChangeMessageVisibility, DeleteMessage, SendMessage. Native forwarding needs bounded translation; SQL adds queue state; Cosmos FIFO requires multiple durable coordination steps and cannot honestly inherit a 1 ms forwarding budget.
Bounded short-poll receive: +10 ms monthly p99 (adapter-added). ReceiveMessage. Receive scans/selects candidates, claims visibility and creates receipt handles. FIFO head selection and Cosmos slot CAS cost more than a simple send.
Bounded message batches: +30 ms monthly p99 (adapter-added). DeleteMessageBatch, SendMessageBatch. A conservative upper budget for up to ten point paths plus aggregation. It does not assume the implementation parallelizes all target or metadata work.
Queue configuration and discovery: +20 ms monthly p99 (adapter-added). GetQueueAttributes, GetQueueUrl. Queue identity, attributes, tags and counts can use the adapter’s durable catalog; this is not excluded as target message work.
Your signed agreement sets the terms for your deployment. A target does not add an operation or option that the compatibility tables mark unavailable.
What counts toward latency
For a request-response row, measure from the agreed ingress boundary to dispatch of the complete response. A row that explicitly names a first response chunk ends at that chunk; its number does not cover the rest of the stream. A long-poll row names the intentional wait and when adapter delay starts. Include parsing, authorization, admission, translation, serialization, adapter-owned storage and coordination, retries and response handling. Subtract only separately measured target-workload waits and external network segments allowed by the measurement rules. The adapter’s own response handling and dispatch remain covered. A database used for adapter metadata is still adapter work, even if a cloud provider hosts it. For concurrent calls, exclude the union of permitted wait intervals, not the sum of overlapping spans. Calculate each request’s adapter duration first, then the monthly p99. Do not subtract one service’s p99 from another’s. Known adapter timeouts are over-budget samples; failed or incomplete requests cannot disappear to improve the percentile. Missing measurements do not become zero latency. An SDK call span alone does not prove how much of its duration can be excluded.Endpoint reachability and request failures
The endpoint-reachability target measures adapter health checks. Correctly forwarding a target quota or permission error is different from producing that error because the adapter sent the wrong request. Adapter-caused failures remain Tensor9’s responsibility even when the target is healthy. Correctness and data-integrity requirements apply to every supported request. Endpoint reachability does not measure request correctness or grant an allowance for incorrect results.Scaling and target-service capacity
Scale send, receive and settle capacity together, and track in-flight messages, pollers, candidate scans and FIFO group skew. Adding replicas helps independent groups but cannot parallelize the ordered head of one group. The agreement caps active pollers, groups inspected per receive, message bytes, retry amplification and batch entries. Tensor9 scales the fabric within those limits; the customer supplies sufficient broker capacity, Cosmos RU/s or PostgreSQL connections and I/O. Tell Tensor9 the expected steady rate, bursts, concurrency, payload sizes and operation mix. Tensor9 sizes and scales the adapter for the agreed load; you choose and monitor the target service’s capacity with Tensor9’s help. A latency budget is not a requests-per-second rating. Larger requests and higher rates need explicit terms, not silent inheritance of a small-request SLA.Data and behavior guarantees
Acceptance must not be returned before the documented message persistence point. Settlement must apply to the intended message/receipt; FIFO order and deduplication apply only where this directed profile supports them. Duplicate delivery can be legitimate under at-least-once delivery. Dead-letter transitions must not silently discard an accepted message. Durability of the target broker/database remains its own commitment, while broken adapter receipt, marker or coordination logic remains Tensor9’s responsibility.Example and diagnosis
Fororder-events, send a 2 KiB message, receive up to ten messages with WaitTimeSeconds=0, then settle each receipt. For a FIFO queue, distribute independent customers across groups instead of expecting one group to scale with replicas. If native message writes are fast but Cosmos FIFO sends slow down, inspect counter/dedup contention: those coordination waits still count against Tensor9’s fabric budget.
Use tensor9 explain and the documented explain headers to understand the selected adapter and its behavior. Correlate available request diagnostics with the target provider’s latency, throttling and capacity metrics. An explain report helps diagnose a request; it is not by itself a qualified SLA timing measurement. Share the operation, request shape, timestamps and request identifiers with support, with credentials and customer payloads removed.